Chapter 3 — Predicting with Linear Regression
What This Chapter Covers
A manager needs a prediction and a reason to trust it. We will estimate a line, interpret coefficients, quantify uncertainty, check residuals, and evaluate predictions on later data.
Simple linear regression leads into inference, diagnostics, multiple regression, multicollinearity and test-set accuracy. The pharmacy example supplies the multiple-regression and model-comparison data.
Chapter Roadmap
| Section | Question we will answer |
|---|---|
| 1 | What relationship is worth modelling? |
| 2 | How is a regression line fitted? |
| 3 | How can SPY return explain NVDA return? |
| 4 | What do standard errors, tests, and intervals tell us? |
| 5 | What can we predict, and how uncertain is it? |
| 6 | What do residuals and unusual observations reveal? |
| 7 | How do we interpret several predictors together? |
| 8 | Does the model predict later records well? |
| 9 | Which pharmacy predictors help predict Profit? |
Business Questions and Association
Choose an outcome, choose relevant predictors, and inspect the relationship before fitting a model.
Outcome Y and Predictor X
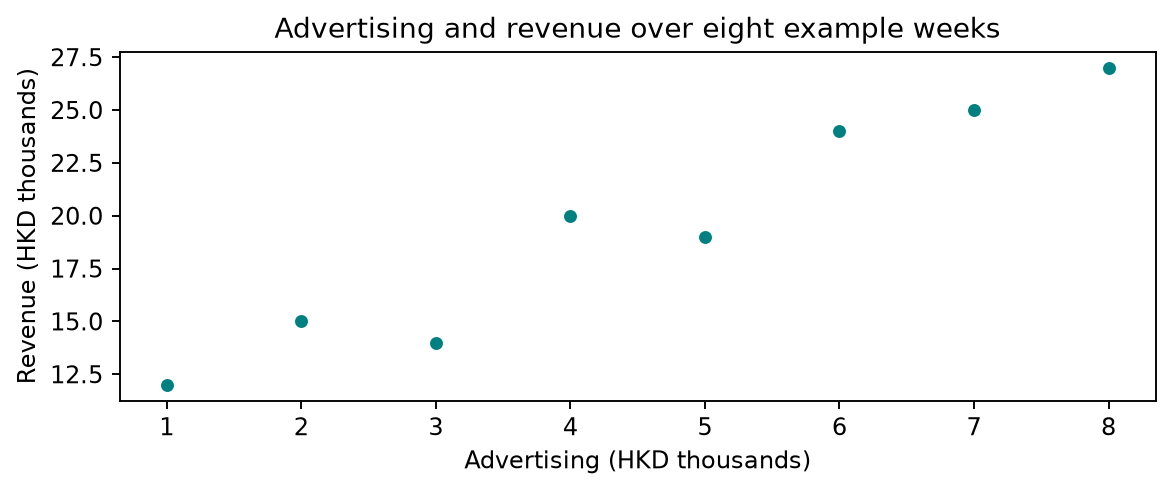
A response/outcome is what we want to explain or predict. A predictor/feature is an input. Here Y is weekly revenue; X is advertising spending. Each row refers to the same week.
Pairing matters: advertising from one week and revenue from another create a different question. An identifier helps organise rows but normally is not a numerical predictor. Units determine how the slope is interpreted.
Association, Direction, and Shape
Two variables are associated when their values show a relationship. A positive pattern tends to rise as X increases; a negative pattern tends to fall. A linear pattern follows approximately a straight line. A nonlinear pattern bends or changes direction.
Association is broader than Pearson correlation. A curved relationship can be increasing throughout, decreasing throughout, or U-shaped. Describe the direction, shape, strength around that shape, and unusual observations before choosing a model.
Yes. A tight U-shaped or other curved pattern can show strong association while a single straight line describes it poorly.
Scatterplot Before Correlation
Each point represents one week. Put Ads on the horizontal axis and Revenue on the vertical axis. Look for direction, curvature, spread, and isolated observations.
Four Scatterplot Patterns
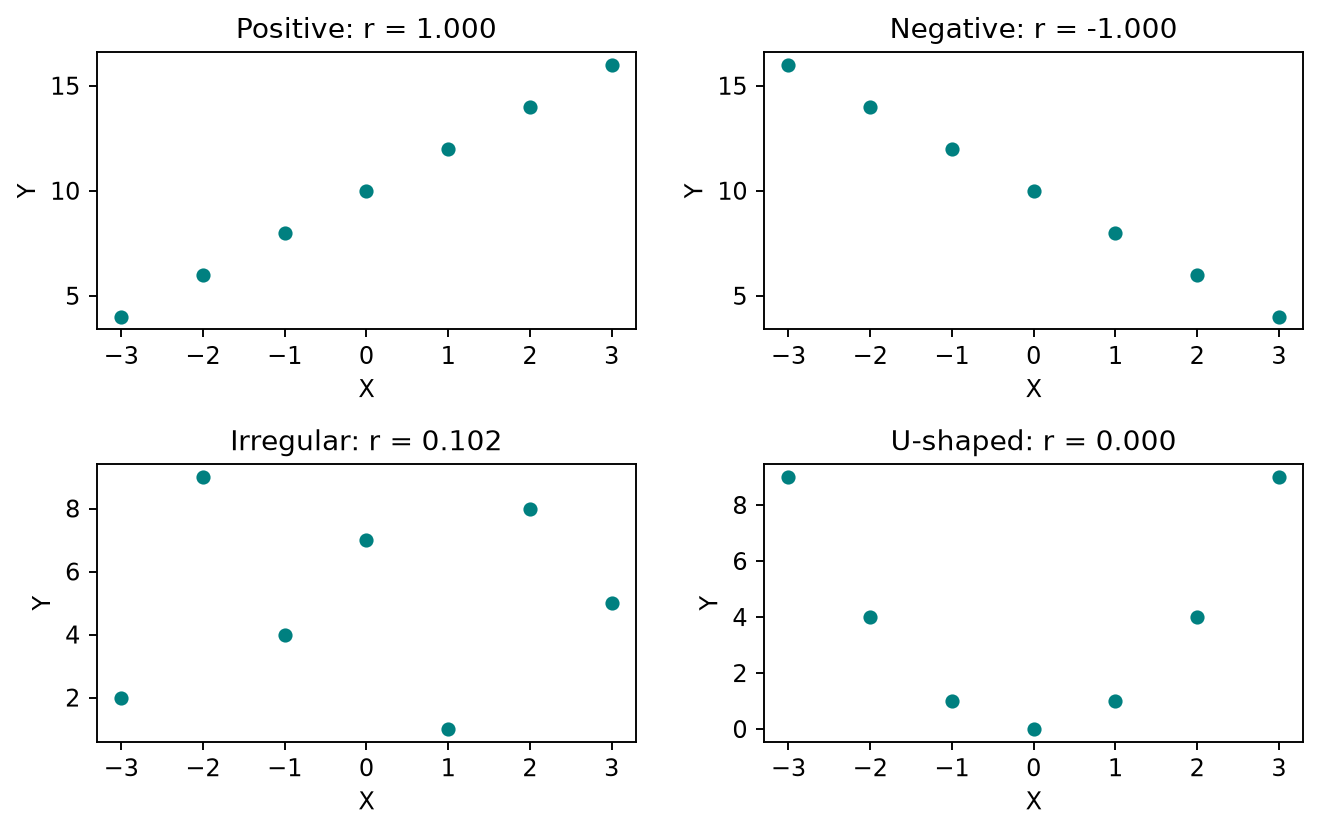
These constructed examples use the same X values. Compare a positive line, a negative line, irregular scatter, and a U-shaped curve. Read the shape before comparing the reported Pearson correlations.
The irregular seven-point example illustrates weak linear association; a scatterplot cannot prove independence. The U-shaped observations follow an exact rule, although their Pearson correlation is zero.
Read a Correlation as Linear Association
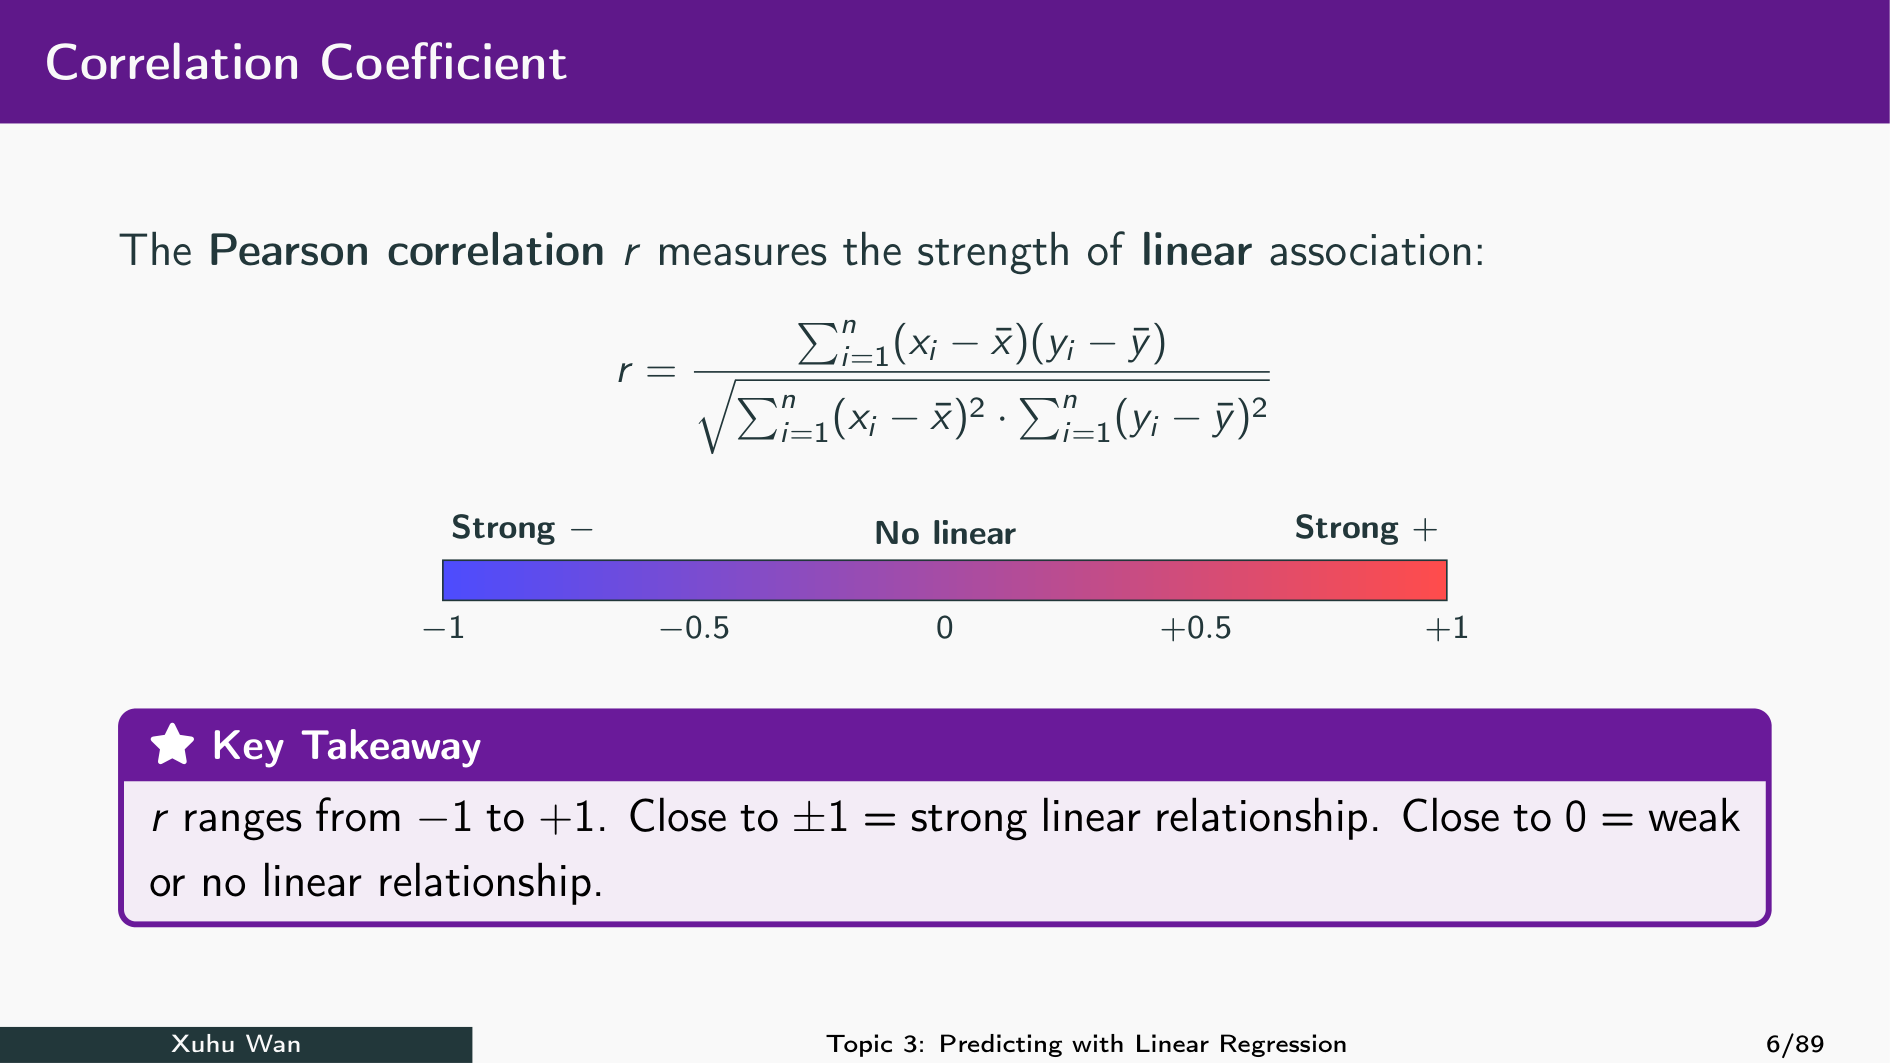
Pearson correlation \(r\) ranges from −1 to +1 when both variables vary. Its sign gives direction; its magnitude describes linear association. A high correlation alone does not show causation.
Correlation has no units. Near zero means weak linear association in this sample; it does not rule out a nonlinear pattern. If either variable is constant, Pearson correlation is undefined. Use the scatterplot alongside the number.
How Pearson Correlation Works
\(r=\frac{\sum_i(x_i-\bar x)(y_i-\bar y)}{\sqrt{\sum_i(x_i-\bar x)^2\sum_i(y_i-\bar y)^2}}\). Centre both variables by subtracting their means. Same-direction deviations contribute positive products; opposite-direction deviations contribute negative products. The denominator removes the units.
Positive and negative products can cancel in a curved pattern. That is why a near-zero value can coexist with a strong relationship. Correlation is symmetric: swapping X and Y gives the same number, although a regression slope generally changes.
Zero Correlation with a Clear Business Pattern
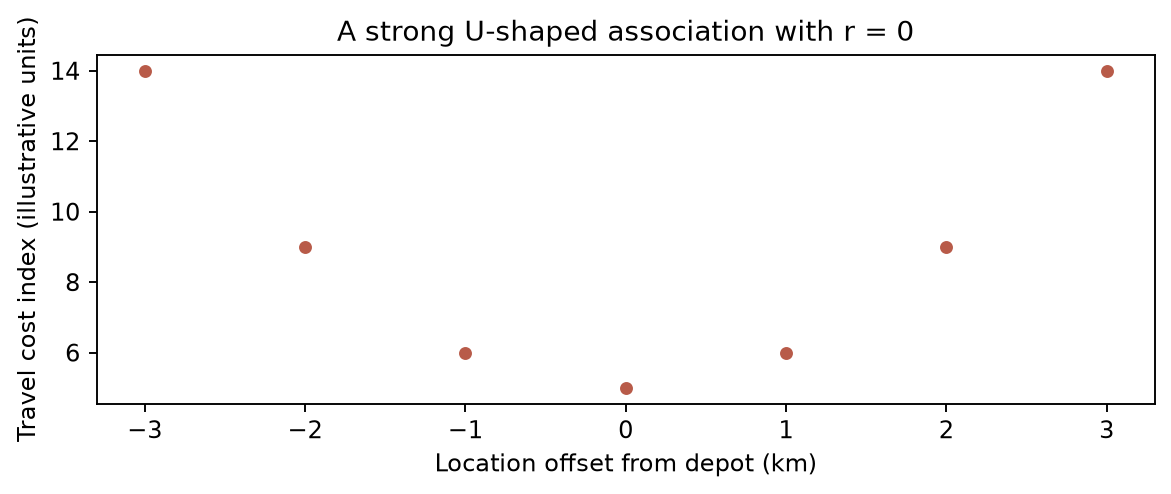
In this constructed delivery example, LocationOffset is kilometres east (+) or west (−) of a depot. TravelCost is an illustrative cost index: \(5+\mathrm{LocationOffset}^2\). Both directions become more expensive farther from the depot. Predict the correlation before running.
Cost falls as locations move toward the depot from the west, then rises as locations move east. A single positive or negative direction cannot describe both halves. This is an exact illustrative rule, not an estimated delivery-company cost function. Zero correlation does not imply independence or constant travel cost.
Interactive Association: Change the Shape
Choose a positive, negative, or U-shaped relationship. Increase the noise and watch Pearson r change. Predict first: can the U-shape have r close to zero even when X clearly matters?
These are fixed, constructed example points, not observed business records. The orange line is the OLS straight-line fit. Changing the noise keeps the same underlying pattern and noise sequence.
No. Inspect the scatterplot: a clear curved relationship can have near-zero linear correlation.
Linear and Nonlinear Patterns with Noise
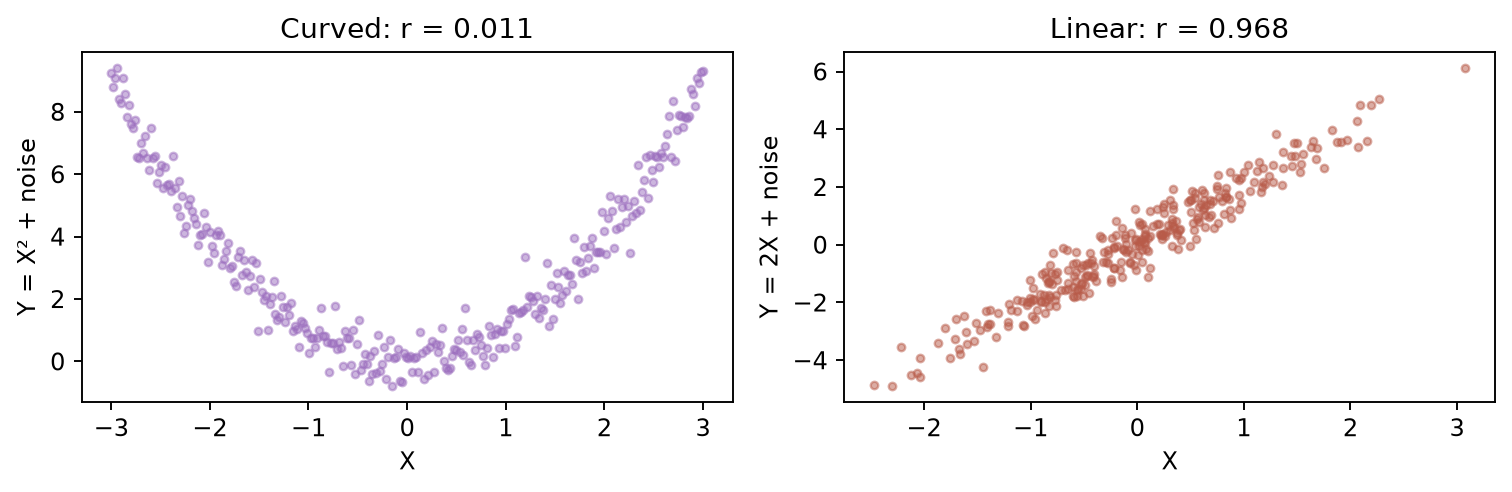
Compare \(Y=X^2+\mathrm{noise}\) with \(Y=2X+\mathrm{noise}\). The curved example can have a correlation near zero even when the U shape is obvious. Change the noise scale and compare the pictures with the numbers.
Both samples are constructed with seed 42 and 300 observations. A seed repeats an illustration; it does not validate a business model. A nonlinear pattern is a reason to inspect alternative mean functions rather than conclude that X is irrelevant.
Correlation and Units
Changing HKD thousands into HKD multiplies the values by 1,000. The correlation stays the same; the numerical slope may change when the units of X or Y change.
Reading a Correlation Matrix
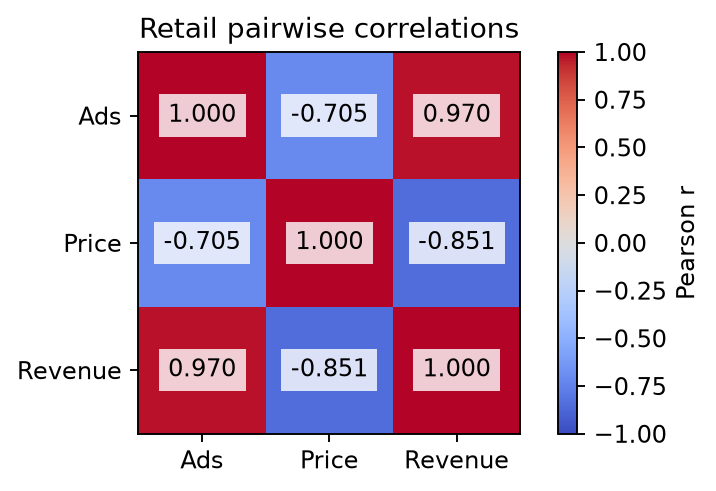
Series.corr(other) returns one number. DataFrame.corr() returns every pairwise correlation for the selected numeric columns. Find a pair at its row and column intersection. The table is symmetric; the diagonal is 1 for each varying variable.
Select meaningful numeric variables rather than record IDs. With missing values, pandas normally uses complete pairs separately for each correlation; different entries can use different rows. This complete eight-row example avoids that issue. A pairwise correlation does not hold the other columns constant.
Sources: pandas DataFrame.corr · pandas Series.corr
Nonlinear Pattern and Correlation
When correlation is close to zero, there is little linear association. The data may have no obvious pattern, or they may follow a strong nonlinear pattern. Pearson correlation measures the direction and strength of a linear relationship. Always check the scatterplot.
These two constructed examples use the same X values. The random-scatter example has Pearson r about -0.008. The U-shaped example follows the exact rule Y = 5 + X² and has Pearson r zero: negative and positive linear contributions cancel. A near-zero sample correlation alone cannot establish independence or rule out a useful nonlinear relationship.
A Heatmap Shows the Same Correlation Matrix
Run Code to draw the heatmap. .corr() calculates the matrix; ax.imshow(...) draws its colours; plt.show() displays the figure. vmin=-1, vmax=1 fixes the colour scale.
The complete code below runs independently, including the retail data setup. Scroll within the editor to see axis labels, the two loops that annotate the nine cells, the colour bar, and plt.show(). The output is generated by Python; changing a spending value and clicking Run Code recalculates the correlations and redraws the figure. Read both the colours and the numbers. A heatmap summarises linear association and cannot reveal a U-shaped relationship.
Association in NVDA and Market Returns
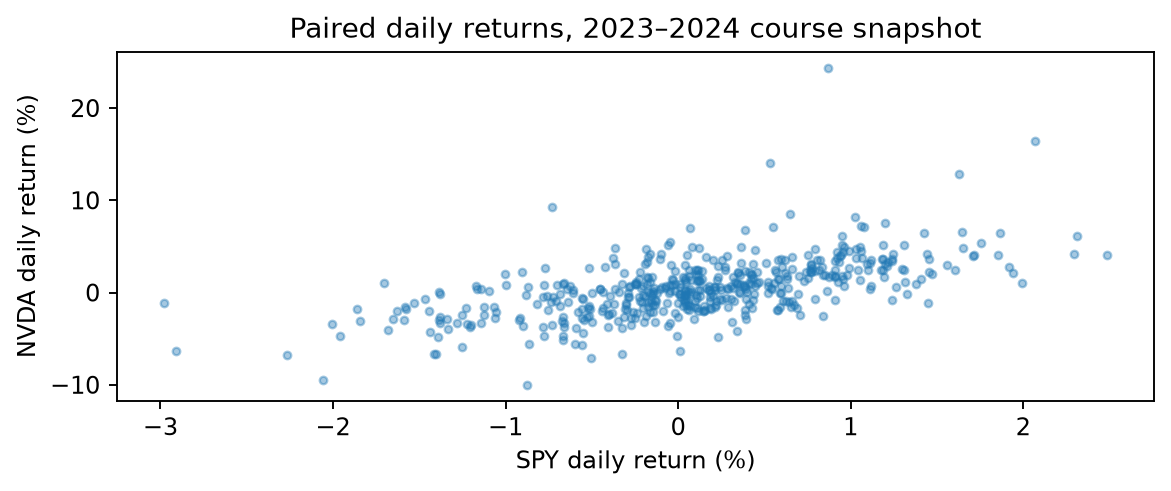
NVDA is our stock example and SPY is our market proxy. We use the existing course price snapshot: sort dates, compute each daily proportional change, and retain complete pairs. The first change is missing because it needs a preceding price. Decimal 0.01 means a 1% return.
Use SPY return as X and NVDA return as Y throughout the stock example. Correlation describes the supplied historical sample. It does not equal the regression slope or establish causation.
Association Is a Starting Point
Busy weeks may have more advertising and lower prices. A simple linear regression cannot separate those relationships. A model with several predictors can account for measured price differences, while observational controls do not automatically establish causation.
In-Class Practice: A Number and a Picture
Use the delivery example. Print the LocationOffset–TravelCost correlation, draw the scatterplot, and explain how both results can be correct. Then create DistanceSquared = LocationOffset ** 2 and inspect its correlation with TravelCost.
Section 1 Practice — Business Questions and Association
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Identify the response
Warm-up. Print the Revenue Series. State its units.
Write your answer, then run it.
2. Select paired variables
Warm-up. Print only Ads and Revenue for the first three weeks.
Write your answer, then run it.
3. Count observations
Warm-up. Print the number of paired weekly records.
Write your answer, then run it.
4. Compute correlation
Build your skills. Print the Ads–Revenue correlation rounded to three decimals.
Write your answer, then run it.
5. Change currency units
Build your skills. Convert Revenue into HKD and verify that correlation is unchanged.
Write your answer, then run it.
6. Compare two relationships
Build your skills. Print correlations of Revenue with Ads and Price.
Write your answer, then run it.
7. Inspect an unusual week
Build your skills. Replace the last Revenue by 45 and print the new correlation.
Write your answer, then run it.
8. Calculate a curved example
Challenge. Create a Series of location offsets [-3, -2, -1, 0, 1, 2, 3]. Set cost = 5 + offset ** 2. Print their correlation rounded to six decimals.
Write your answer, then run it.
9. Compare a transformed predictor
Challenge. Using the same offsets and costs, compare correlation with offset against correlation with offset ** 2. Print both to three decimals.
Write your answer, then run it.
10. Support a cautious conclusion
Challenge. Print the Ads–Revenue correlation. Then explain why a near-zero correlation cannot rule out association, and why a large correlation does not prove an advertising effect.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Identify the response
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
print(sales["Revenue"])Expected output
0    12
1    15
2    14
3    20
4    19
5    24
6    25
7    27
Name: Revenue, dtype: int64Revenue is the response, measured in thousands of HKD per week.
2. Select paired variables
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
print(sales[["Ads", "Revenue"]].head(3))Expected output
   Ads  Revenue
0    1       12
1    2       15
2 3 14The two columns remain aligned by week.
3. Count observations
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
print(len(sales[["Ads", "Revenue"]].dropna()))Expected output
8Each complete row supplies one paired observation.
4. Compute correlation
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
print(round(sales["Ads"].corr(sales["Revenue"]), 3))Expected output
0.97The positive value describes linear association in these eight weeks.
5. Change currency units
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
revenue_hkd = sales["Revenue"] * 1000
print(round(sales["Ads"].corr(revenue_hkd), 3))Expected output
0.97Positive unit conversion preserves correlation.
6. Compare two relationships
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
print(sales[["Ads", "Price", "Revenue"]].corr()["Revenue"].round(3))Expected output
Ads        0.970
Price     -0.851
Revenue    1.000
Name: Revenue, dtype: float64Each is a separate pairwise association; neither controls for the other predictor.
7. Inspect an unusual week
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
sales.loc[7, "Revenue"] = 45
print(round(sales["Ads"].corr(sales["Revenue"]), 3))Expected output
0.863The altered observation changes the relationship; inspect its business explanation.
8. Calculate a curved example
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
offset = pd.Series([-3, -2, -1, 0, 1, 2, 3])
cost = 5 + offset ** 2
print(round(offset.corr(cost), 6))Expected output
0.0The symmetric U-shaped relationship has zero Pearson correlation despite following an exact rule.
9. Compare a transformed predictor
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
offset = pd.Series([-3, -2, -1, 0, 1, 2, 3])
cost = 5 + offset ** 2
print(round(offset.corr(cost), 3))
print(round((offset ** 2).corr(cost), 3))Expected output
0.0
1.0Squared offset captures the shape of this constructed rule. Transformations should reflect the problem and then face validation.
10. Support a cautious conclusion
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
print(round(sales["Ads"].corr(sales["Revenue"]), 3))
print(
    "Near-zero Pearson correlation can hide curvature. Large correlation alone does not isolate advertising from price or season."
)Expected output
0.97
Near-zero Pearson correlation can hide curvature. Large correlation alone does not isolate advertising from price or season.Check the scatterplot for nonlinear patterns and distinguish observed association from causation.
Fitting and Interpreting a Regression Line
Read the model equation, fit ordinary least squares, and connect fitted values, residuals, and R-squared.
A Line Plus an Error
Simple linear regression (SLR) uses one predictor.
Population model
\[Y=\beta_0+\beta_1X+\varepsilon\]
- \(\beta_0\): true intercept — average \(Y\) when \(X=0\).
- \(\beta_1\): true slope — change in average \(Y\) for a one-unit increase in \(X\).
- \(\varepsilon\): noise — an individual outcome’s deviation from the population mean line.
Fitted line (estimated from the sample)
\[\hat y(x)=\hat\beta_0+\hat\beta_1x\]
- \(\hat y(x)\): estimated average of \(Y\) given \(X=x\).
- \(\hat\beta_0\): estimated intercept; \(\hat\beta_1\): estimated slope. Hats mean estimates.
The population mean assumes E[ε | X=x]=0. The true population coefficients are unknown; fitting the sample estimates them. The unobserved population error ε differs from the calculated residual e = observed Y − fitted Y. Interpreting an intercept at X=0 requires caution if zero is outside the observed range.
Calculate a Prediction by Hand
Suppose the fitted regression line is Predicted Revenue = 10 + 2 × Ads. The coefficients are supplied for illustration. At Ads = 4, predicted average revenue is 18 thousand HKD; an individual week may differ.
This hand calculation assumes a fitted line with intercept 10 and slope 2. These are not the OLS estimates from the eight-week example table: fitting that table on the following slides gives an intercept of about 9.643 and a slope of about 2.190. The calculation shows how to use supplied coefficients; the later fit shows how to estimate coefficients from data. Under the supplied line, increasing Ads by 1 thousand HKD corresponds to 2 thousand HKD more predicted revenue.
Why Ordinary Least Squares?
Each vertical gap is a residual: observed \(y\) minus predicted \(\hat y\). SSE adds all eight squared gaps. Move the line, then play its movement toward the smallest SSE.
The observed values stay fixed while the line and its predictions change. A smaller SSE means less total squared error on these same records; an individual residual can become larger. OLS chooses both intercept and slope to minimise this total. Squaring prevents positive and negative residuals from cancelling and penalises large gaps more. This calculated residual is distinct from the unobserved population error ε. The animation follows a straight path in coefficient space to the exact OLS solution; it illustrates the objective rather than an optimisation algorithm.
No. The total squared vertical error decreases, but some individual residuals may increase.
Calculate Squared Errors and SSE
For Revenue = 10 + 2 × Ads, read each observed value, prediction, residual and squared residual. Add the last column: \(SSE=\sum_i(y_i-\hat y_i)^2\). SSE is measured in squared outcome units.
Fit with statsmodels
Fit means finding the best line: the line with the smallest sum of squared residuals (SSE).
\[SSE=\sum_{i=1}^{n}(y_i-\hat y_i)^2\]
- A residual is a vertical gap: observed \(y_i\) minus fitted \(\hat y_i\).
.fit()chooses the intercept \(\hat\beta_0\) and slope \(\hat\beta_1\) that minimise SSE.sm.add_constant(...)adds the intercept column;sm.OLS(y, X)sets up the model;.fit()fits it to the data.
Array-based OLS does not add an intercept automatically. The constant column has coefficient const. Keep the predictor column names so outputs and later predictions can be read by name.
Sources: OLS documentation
Results: Attributes and Methods
model.params, model.fittedvalues, model.resid, and model.rsquared are attributes: stored results, without parentheses. model.nobs counts observations used for fitting. .predict(...), .conf_int(), and .summary() are methods: calls that calculate or format a result.
Read stored values with .params; call an operation with .predict(…).
Observed, Fitted, and Residual
A positive residual means the observed revenue is above the fitted line. A negative residual means it is below. Residuals have the same units as Revenue.
See the Fitted Line
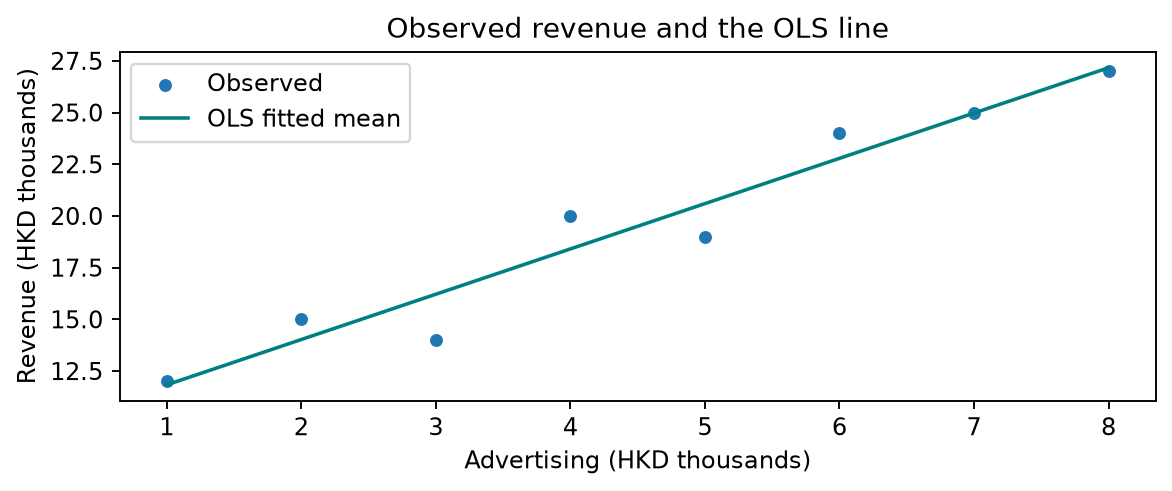
The line is an estimated mean relationship. The vertical gaps from the observations to the line are residuals. It does not pass through every observation.
Interactive Line: Change the Slope
Move the intercept and slope. Watch the predicted values, residuals, and SSE change for the same eight weeks. The smallest SSE is what OLS seeks.
Start with Variation Around the Mean
Before fitting a line, predict the same mean \(\bar y\) for every record. SST adds the squared distances from that mean. Sample variance divides this total by \(n-1\).
\[SST=\sum_{i=1}^{n}(y_i-\bar y)^2,\qquad s_y^2=\frac{SST}{n-1}.\]
For the eight retail weeks, \(\bar y=19.5\), \(SST=214\), and \(s_y^2=30.571\). Variance has squared revenue units.
SST, SSR, and SSE: Three Different Distances
| Total variation | Explained by the regression | Remaining error |
|---|---|---|
| \(SST=\sum(y_i-\bar y)^2\) | \(SSR=\sum(\hat y_i-\bar y)^2\) | \(SSE=\sum(y_i-\hat y_i)^2\) |
| Observed → mean | Fitted → mean | Observed → fitted |
\[\boxed{SST=SSR+SSE}\quad\text{for OLS with an intercept, on its training rows.}\]
Here SSR means regression (explained) sum of squares. Some sources use SSR for residual sum of squares; always check the definition.
The identity follows from OLS residuals being orthogonal to the fitted values and having zero mean when an intercept is included. It is not generally an identity for an arbitrary line, a model without an intercept, or held-out predictions. All three sums use the same observations and squared outcome units.
Sources: Penn State: sums of squares
Interactive Decomposition: Follow One Observation
Select a week. The three coloured vertical distances show \(y_i-\bar y\), \(\hat y_i-\bar y\), and \(y_i-\hat y_i\). The signed distances add for each point; the squared totals add across the OLS training sample.
Not generally. SST = SSR + SSE is an aggregate identity for the fitted OLS training sample with an intercept.
RMSE Returns the Error to Revenue Units
RMSE and R² are two measures of SLR fit. RMSE expresses residual variation in the units of \(Y\); R² describes the proportion of variation explained. Regression RMSE, denoted \(s\), estimates the standard deviation \(\sigma\) of the underlying noise \(\varepsilon\) in \(Y=\beta_0+\beta_1X+\varepsilon\):
\[s=\mathrm{RMSE}=\sqrt{\frac{\mathrm{SSE}}{n-2}} =\sqrt{\frac{1}{n-2}\sum_{i=1}^{n}(y_i-\hat{y}_i)^2}.\]
\(n\) is the training sample size. We subtract 2 because we estimated an intercept and a slope. For the 8 retail weeks: \(\sqrt{12.476/(8-2)}=1.442\) thousand HKD.
This lesson uses regression root MSE, also called residual standard error: sqrt(SSE/(n−2)) for SLR. Under a correctly specified constant-variance regression model, sigma is the unknown standard deviation of the underlying errors, while s is calculated from sample residuals. Its square s² is an unbiased estimator of sigma²; s itself need not be unbiased. It is not the standard deviation of Y or the standard error of an estimated coefficient. In ISOM2600, RMSE always refers to this residual standard error s.
Sources: statsmodels: residual mean square
R-Squared Compares Two Fits
R² compares the line with the mean-only baseline:
\[R^2=1-\frac{SSE}{SST}=\frac{SSR}{SST}.\]
For the fitted retail OLS line: \(SST=214\), \(SSR=201.524\), \(SSE=12.476\), so \(R^2=0.9417\). It explains about 94.2% of the training variation around the mean. This does not establish causation or future prediction accuracy.
The SSR/SST equality uses an intercept and the OLS training sample. R² has no units; RMSE has outcome units. If the outcome is constant, SST is zero and this R² formula is undefined. A high R² alone does not establish that the conditional-mean form or error assumptions are appropriate.
Two Measures of SLR Fit: RMSE and R-Squared
Use both measures to describe the same fitted regression line.
| Regression RMSE | R² | |
|---|---|---|
| Question | How large is the residual variation? | What proportion of variation does the line explain? |
| Formula | \(s=\sqrt{SSE/(n-2)}\) | \(1-SSE/SST\) |
| Units | Same as \(Y\) | No units |
| Better sample fit | Smaller | Larger |
| Retail example | 1.442 thousand HKD | 0.9417, or 94.17% |
Regression RMSE \(s\) estimates the underlying noise standard deviation \(\sigma\); R² gives an explained proportion. Good training fit does not guarantee good prediction on new records.
These are evaluation measures, not alternative ways of fitting the line: OLS produces the fitted model, then both measures summarise it. For SLR with an intercept on the same nonconstant outcome and same training records, higher R² corresponds to lower regression RMSE because SST and n−2 are fixed. Do not compare RMSE across different outcome units. Test-set prediction error is introduced separately in Section 8.
RMSE expresses the residual scale in outcome units; R-squared expresses the fraction of training variation explained. Neither alone establishes future accuracy.
Interactive R-Squared: Reduce the Squared Errors
Start with the mean-only prediction. Move toward the OLS line and compare the vertical errors. At the OLS endpoint, R² is the fraction of the original squared error removed.
The dashed line predicts the same sample mean for every week. SST is its squared error; SSE is the current line’s squared error. Intermediate lines illustrate 1 − SSE/SST; only the final endpoint is the fitted OLS model. This is training fit, not a causal effect or a test-set accuracy guarantee.
The fitted line’s SSE with the same-sample mean baseline’s SST: R² = 1 − SSE/SST.
In-Class Practice: Explain the Slope
Print the fitted Ads coefficient. Explain both units in one sentence. Predict Revenue at Ads=4 using .predict() and a table with columns const and Ads.
Section 2 Practice — Fitting and Interpreting a Regression Line
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Read the intercept
Warm-up. Print the estimated intercept rounded to three decimals.
Write your answer, then run it.
2. Read the slope
Warm-up. Print the Ads coefficient rounded to three decimals.
Write your answer, then run it.
3. Compute regression RMSE
Warm-up. Print the SLR regression RMSE using n-2 and explain why two degrees of freedom are used.
Write your answer, then run it.
4. Calculate one residual
Build your skills. Print observed minus fitted revenue for the first week.
Write your answer, then run it.
5. Calculate SSE
Build your skills. Square and sum residuals; print SSE.
Write your answer, then run it.
6. Predict a new input
Build your skills. Predict Revenue at Ads=4 with a one-row design table.
Write your answer, then run it.
7. Decompose variation
Build your skills. Calculate SST, SSR and SSE for the fitted OLS model; verify SST = SSR + SSE and print R-squared.
Write your answer, then run it.
8. Compare a proposed line
Challenge. Compare fitted SSE against SSE for the line Revenue=10+2*Ads.
Write your answer, then run it.
9. Find the largest deviation
Challenge. Print the index and signed value of the residual with greatest absolute size.
Write your answer, then run it.
10. Change predictor units
Challenge. Fit using Ads in HKD rather than thousands; print the new slope and compare it with the old slope divided by 1000.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Read the intercept
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(model.params["const"], 3))Expected output
9.643This is fitted revenue at zero advertising, in HKD thousands.
2. Read the slope
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(model.params["Ads"], 3))Expected output
2.19Units are revenue HKD thousands per advertising HKD thousand.
3. Compute regression RMSE
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
import numpy as np

n = len(sales)
sse = (model.resid**2).sum()
print(round(np.sqrt(sse / (n - 2)), 3))
print(
    "Two fitted coefficients: intercept and slope. Regression RMSE is residual standard error."
)Expected output
1.442
Two fitted coefficients: intercept and slope. Regression RMSE is residual standard error.Divide SSE by the residual degrees of freedom n-2, then take the square root.
4. Calculate one residual
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(sales.loc[0, "Revenue"] - model.fittedvalues.loc[0], 3))Expected output
0.167The subtraction order determines the sign.
5. Calculate SSE
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round((model.resid ** 2).sum(), 3))Expected output
12.476SSE is an aggregate squared deviation, not a revenue amount.
6. Predict a new input
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [4]})
print(round(model.predict(new).iloc[0], 3))Expected output
18.405New input columns match the fitted constant and Ads columns.
7. Decompose variation
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
import numpy as np
y = sales["Revenue"]
sst = ((y - y.mean()) ** 2).sum()
ssr = ((model.fittedvalues - y.mean()) ** 2).sum()
sse = (model.resid ** 2).sum()
print(round(sst, 3), round(ssr, 3), round(sse, 3))
print(np.isclose(sst, ssr + sse))
print(round(ssr / sst, 4))Expected output
214.0 201.524 12.476
True
0.9417SSR is explained regression variation here; the identity uses the OLS training fit with an intercept.
8. Compare a proposed line
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
other = sales["Revenue"] - (10 + 2 * sales["Ads"])
print(round((model.resid ** 2).sum(), 3))
print(round((other ** 2).sum(), 3))Expected output
12.476
16The OLS SSE is no larger than that of the proposed line.
9. Find the largest deviation
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
position = model.resid.abs().idxmax()
print(position, round(model.resid.loc[position], 3))Expected output
2 -2.214Largest absolute size can refer to a negative residual.
10. Change predictor units
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
sales["AdsHKD"] = sales["Ads"] * 1000
changed = sm.OLS(sales["Revenue"], sm.add_constant(sales[["AdsHKD"]])).fit()
print(round(changed.params["AdsHKD"], 6))
print(round(model.params["Ads"] / 1000, 6))Expected output
0.00219
0.00219Units change the coefficient even though fitted revenue stays the same.
Simple Regression with SPY and NVDA Returns
Use SPY return as X and NVDA return as Y. Fit a line, read its intercept and slope, and make a conditional prediction.
Prices and Returns Answer Different Questions
A stock price is a level. A daily return measures the proportional price change since the previous trading day. pct_change() calculates that change. Its first row is missing because it has no previous price in the file.
Decimal Returns and Percentage Points
| Decimal stored in Python | Return displayed as a percentage |
|---|---|
| 0.01 | +1% |
| 0.02 | +2% |
| -0.01 | -1% |
Multiplying a decimal return by 100 displays it as a percentage. Moving from 1% to 2% is an increase of one percentage point.
X Is SPY Return and Y Is NVDA Return
SPY represents broad US market performance. NVDA is the individual stock whose return we want to explain. Each row contains the two returns from the same trading day.
\[\text{Fitted NVDA return}=\text{intercept}+\text{slope}\times\text{SPY return}.\]
Actual NVDA return can differ from the fitted return because other influences remain.
Keep X and Y on the Same Date
The Date index identifies each trading day. Select the SPY and NVDA columns together before calculating returns, then use dropna() to remove incomplete pairs. One row is one shared date. Do not pair an NVDA return with a SPY return from another day.
Keep Later Dates for Testing
Fit using the first 80% of complete dates. Reserve the later 20% to check predictions. cut is the row position where the test period begins. .iloc[:cut] excludes that position and .iloc[cut:] starts there.
Fit NVDA Return on SPY Return
Y contains NVDA returns. The design X contains SPY returns plus the constant column added by sm.add_constant. sm.OLS(Y, X).fit() estimates the intercept and slope from the training dates.
The Intercept Is the Fitted Return When X Is Zero
Set SPY return to 0% in the fitted equation. The remaining fitted NVDA return is the intercept. Read it from model.params["const"]. The model and Python store returns as decimals.
An Intercept Describes This Fitted Line
A positive intercept puts the fitted NVDA return above zero when SPY return is zero. A negative intercept puts it below zero.
This is a description of the fitted historical relationship. It is not a guarantee that NVDA will earn that return on any particular day.
Calculate a Return from a Supplied SPY Scenario
For an illustrative line, take an intercept of 0.1% and a slope of 1.5. If SPY returns 1%, the fitted NVDA return is 0.1% + 1.5 × 1% = 1.6%. If SPY returns -1%, the fitted return is -1.4%. These illustrative coefficients are separate from the estimated NVDA model.
The Slope Describes a Change in Y for a Change in X
In a fitted straight line, a one-unit increase in X corresponds to a fitted change in Y equal to the slope. Keep the units of both variables explicit.
Here both variables are decimal returns. More practically, a one percentage-point increase in SPY return corresponds to a fitted increase in NVDA return equal to the slope in percentage points. For a slope of 1.5, that fitted increase is 1.5 percentage points.
Calculate the Slope from Covariance
For OLS with an intercept, divide the covariance of X and Y by the variance of X. Use the same complete training pairs in both calculations. Here X is SPY return and Y is NVDA return.
Compare Slopes Using the Same Return Units
| Illustrative slope | Fitted NVDA change when SPY increases by 1 percentage point |
|---|---|
| 1.5 | Increases by 1.5 percentage points |
| 1.0 | Increases by 1 percentage point |
| 0.6 | Increases by 0.6 percentage points |
| 0 | No fitted linear change |
| -0.5 | Decreases by 0.5 percentage points |
These are slope illustrations, not estimates for several stocks. Actual returns also contain residual variation.
Interactive Return Prediction: Intercept and Slope
Change the intercept, slope or SPY return, then read the fitted NVDA return. The values here are illustrative percentages.
Plot the Fitted Stock-Return Line
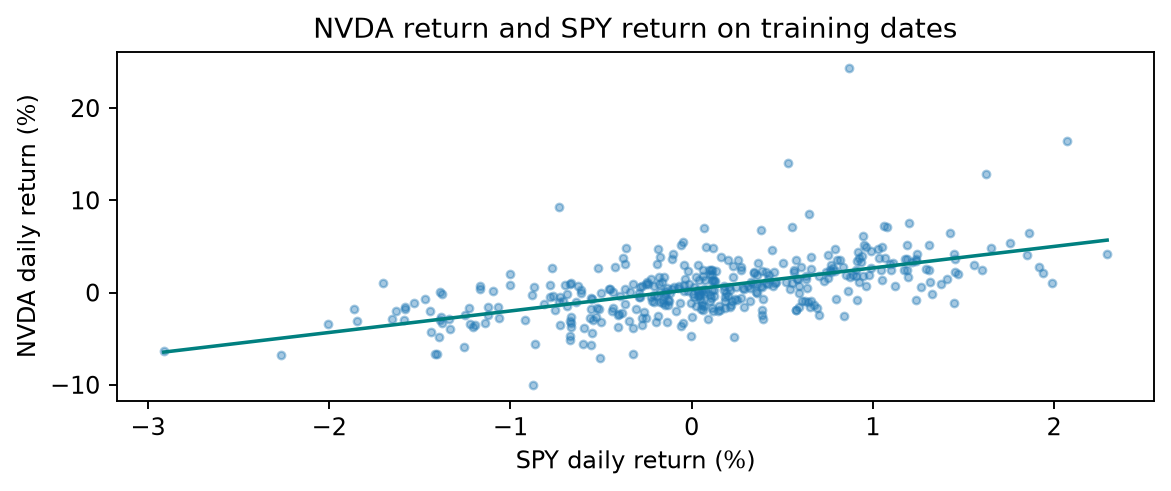
Each dot represents one training date. Its horizontal position is SPY return and its vertical position is NVDA return. The line shows fitted NVDA returns. Vertical distances from the dots to the line are residuals.
In-Class Practice: A Conditional Return
Supply SPY return of 0.01, meaning 1%, and use the fitted model to predict NVDA return. Display the result as a percentage. Explain why an unknown future SPY return must be supplied before the model can predict that day.
Section 3 Practice — Simple Regression with SPY and NVDA Returns
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Read paired returns
Warm-up. Print the first three paired SPY and NVDA daily returns.
Write your answer, then run it.
2. Count complete dates
Warm-up. Print the number of complete return dates.
Write your answer, then run it.
3. Check the time split
Warm-up. Print the final training date and first test date.
Write your answer, then run it.
4. Read fitted coefficients
Build your skills. Print the intercept and SPY slope.
Write your answer, then run it.
5. Interpret the slope
Build your skills. Print the fitted change in NVDA return, in percentage points, for a one percentage-point increase in SPY return.
Write your answer, then run it.
6. Interpret the intercept
Build your skills. Print fitted NVDA return, as a percentage, when SPY return is zero.
Write your answer, then run it.
7. Supply a scenario
Build your skills. Predict NVDA return, as a percentage, when SPY return is 1%.
Write your answer, then run it.
8. Inspect a residual
Challenge. Print the first training date’s observed, fitted and residual NVDA returns.
Write your answer, then run it.
9. Read a slope interval
Challenge. Print the 95% confidence interval for the SPY slope.
Write your answer, then run it.
10. State the required input
Challenge. Print the SPY inputs needed for the first three reserved test dates.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Read paired returns
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(data[["SPY", "NVDA"]].head(3))Expected output
                 SPY      NVDA
Date
2023-01-04  0.007720  0.030318
2023-01-05 -0.011413 -0.032816
2023-01-06 0.022932 0.041640Both returns in a row belong to the same trading day.
2. Count complete dates
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(len(data))Expected output
500The first price row has no previous observation and cannot supply a return.
3. Check the time split
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(train.index.max())
print(test.index.min())Expected output
2024-08-07 00:00:00
2024-08-08 00:00:00The reserved dates follow all fitting dates.
4. Read fitted coefficients
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(model.params)Expected output
const    0.003357
SPY      2.332029
dtype: float64const is the intercept and SPY labels the slope.
5. Interpret the slope
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(model.params["SPY"])Expected output
2.3320290464037203Both returns use the same scale, so the slope also converts changes expressed in percentage points.
6. Interpret the intercept
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(model.params["const"] * 100)Expected output
0.3356858253159234Set the predictor to zero in the fitted equation.
7. Supply a scenario
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
new = pd.DataFrame({"const": [1], "SPY": [0.01]})
print(model.predict(new) * 100)Expected output
0    2.667715
dtype: float64This uses a supplied SPY return as the model input.
8. Inspect a residual
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(train["NVDA"].iloc[0])
print(model.fittedvalues.iloc[0])
print(model.resid.iloc[0])Expected output
0.030317967052142514
0.021360532392055622
0.008957434660086892Observed return equals fitted return plus residual.
9. Read a slope interval
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(model.conf_int().loc["SPY"])Expected output
0    2.005432
1    2.658626
Name: SPY, dtype: float64This interval concerns the fitted slope, not the range of individual future returns.
10. State the required input
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(test[["SPY"]].head(3))Expected output
                 SPY
Date
2024-08-08  0.023117
2024-08-09  0.004410
2024-08-12 0.000526A same-day return regression needs that day's SPY return. It does not forecast an unknown SPY return.
Coefficient Uncertainty and Statistical Inference
Distinguish estimates from standard errors; perform specified tests and interpret confidence intervals.
Why an Estimate Needs a Standard Error
sales contains eight example weeks, one row per week. Ads = weekly advertising spending (HKD thousands); Revenue = weekly sales revenue (HKD thousands); Price = selling price (HKD per item). This fit predicts Revenue using Ads; Price is not included.
A new sample gives a different fitted slope. A standard error (SE) estimates the standard deviation of these estimates across repeated samples.
\[\hat\beta_1=2.1905,\qquad SE(\hat\beta_1)=0.2225\]
- Ads estimate = 2.1905: an extra HKD 1,000 of advertising corresponds to HKD 2,190.50 more fitted average revenue.
- Ads SE = 0.2225: if we repeatedly collected samples of the same size under the same conditions and fitted each one, the Ads slope estimates would vary. Their standard deviation is estimated as 0.2225.
- SE has the slope’s units: HKD thousands of Revenue per HKD thousand of Ads. Smaller SE means a more precise slope estimate.
- It is not the standard deviation of Revenue, or the known distance from our estimate to the true slope.
Classical small-sample t inference assumes a correctly specified conditional mean, independent normally distributed errors with constant variance, and a full-rank design. Diagnostics later look for violations; a good-looking plot does not prove the assumptions.
Read a Coefficient Table
Columns: coef is the estimate; std err is its standard error; t tests coefficient=0; P>|t| is the two-sided p-value for that zero null; [0.025,0.975] gives a 95% coefficient interval.
\[t=\frac{\text{coefficient estimate}-\text{null value}}{\text{standard error}}.\]
The Null Value Belongs in the Numerator
The null specifies the slope value to test. Here test a slope of 1, rather than the default value 0. Subtract 1 from the estimated SPY slope, then divide by its standard error. With one predictor and an intercept the residual degrees of freedom are n−2. A two-sided test considers departures above or below 1.
Two-Sided p-Value: Both Tails
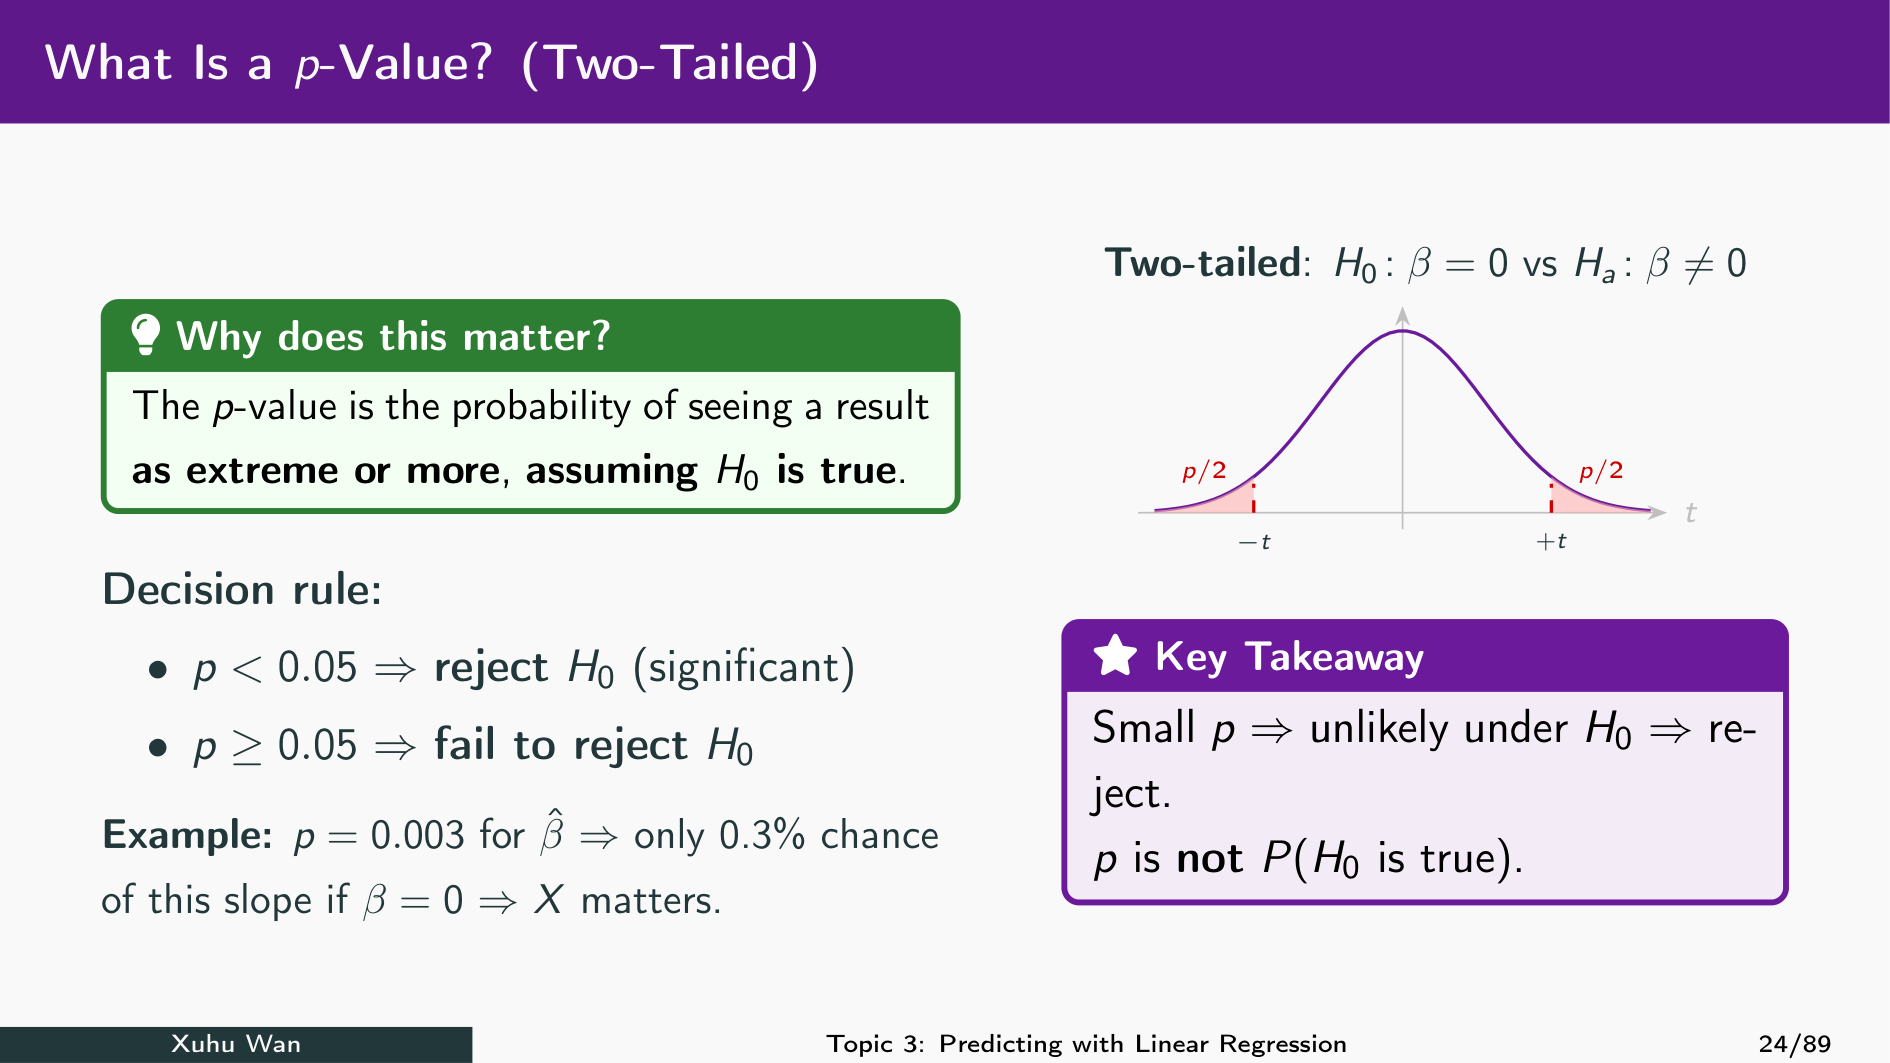
A p-value is the probability, assuming the null and model assumptions, of a test statistic at least as extreme as observed. It is not the probability that the null is true. Both tails matter for a “different from” alternative.
\[p_{\mathrm{two\ sided}}=2P\big(T_{df}\ge |t_{\mathrm{observed}}|\big).\]
Choose the null, alternative, and significance level before inspecting results. A small p-value is evidence against that specified null under the assumptions. It does not measure the size of the business effect.
Calculate the Two-Sided p-Value
stats.t.sf(t, df) gives the right-tail area. For a two-sided test use 2 * sf(abs(t), df). The survival function is convenient and avoids subtracting a CDF very close to 1.
Render the Test Distribution
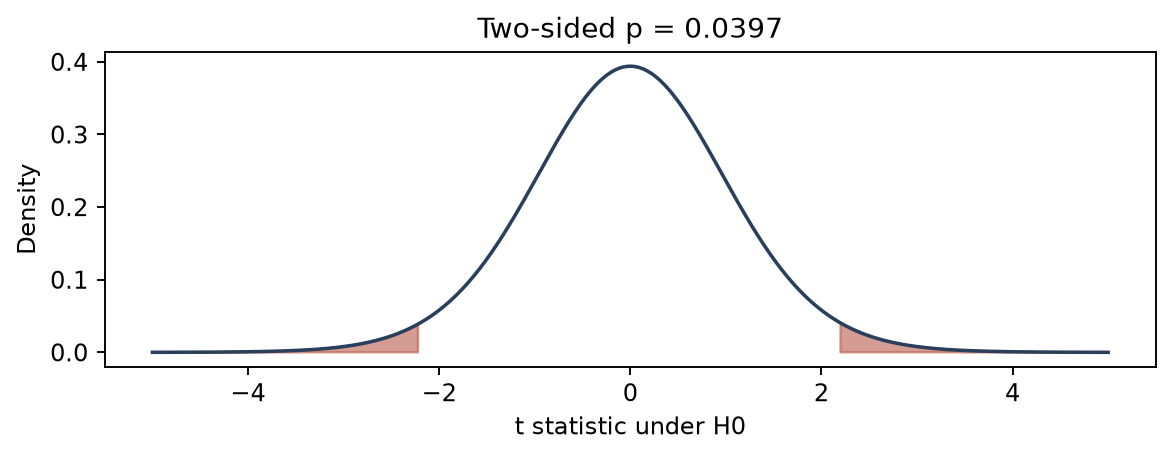
The shaded region is the two-sided p-value for an illustrative t=2.2 with 20 degrees of freedom. Change t_obs and predict how the shaded area changes. This figure is not the estimated stock-return regression test.
What Does p = 0.0397 Mean?
The previous graph is an illustration with \(t=2.2\) and 20 degrees of freedom. Suppose we test \(H_0:\beta_1=0\) against \(H_1:\beta_1\ne0\).
\[p=P\bigl(|T|\ge 2.2\mid H_0\bigr)=2P(T\ge2.2)=0.0397,\qquad T\sim t_{20}.\]
- Meaning: if the true slope is zero and the model assumptions hold, there is about a 3.97% chance of obtaining a t statistic at least this far from zero, in either direction.
- Repeated-sample picture: among 1,000 such samples when the null is true, about 40 would give \(t\le-2.2\) or \(t\ge2.2\).
- Decision at 5%: \(0.0397<0.05\), so reject \(H_0\). There is evidence that the slope differs from zero. At a 1% level, we would fail to reject.
- It does not mean a 3.97% probability that \(H_0\) is true, or a 96.03% probability that \(H_1\) is true.
This p-value belongs to the preceding illustrative t=2.2, df=20 distribution, not the retail Ads or estimated stock-return regression coefficient. Choose the significance level before viewing the data. Rejecting a zero slope does not establish causation or business importance.
A Confidence Interval for a Coefficient
A classical 95% coefficient interval is \(\hat\beta\pm t_{0.975,df}\,SE(\hat\beta)\). In repeated samples, this procedure covers the fixed true coefficient 95% of the time under the assumptions. It is not an interval for an individual outcome.
For the same classical two-sided zero test at 5%, an interval excluding zero agrees with rejection. A wide interval signals imprecision. Raising confidence from 95% to 99% makes the interval wider, with the same fitted model.
Statistical and Business Importance
Use reject or fail to reject, rather than “accept the null.” Discuss effect size, units, interval width, and assumptions.
Two-sided test: Ads slope = 0 versus Ads slope ≠ 0. A small p-value provides evidence that advertising spending is linearly associated with weekly revenue, under the model assumptions. Read the estimated slope for the direction and size.
It does not establish causation or show that the advertising increase pays for itself.
In-Class Practice: Does the Slope Differ from One?
Test whether the SPY slope equals 1 against a two-sided alternative. A slope of 1 means a one percentage-point increase in SPY return corresponds to a fitted one percentage-point increase in NVDA return. State the null, alternative, t statistic, degrees of freedom, p-value and conclusion at 5%.
Interactive Test: Move the Observed t
Move the observed t statistic. The alternative is different from the null value: a two-sided test. Compare the shaded probability with the Python survival-function calculation; degrees of freedom stay fixed at 20.
Section 4 Practice — Coefficient Uncertainty and Statistical Inference
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Read a standard error
Warm-up. Print the Ads coefficient standard error.
Write your answer, then run it.
2. Read degrees of freedom
Warm-up. Print residual degrees of freedom.
Write your answer, then run it.
3. Reconstruct the default t statistic
Warm-up. Calculate slope/SE for a zero null.
Write your answer, then run it.
4. Read a two-sided p-value
Build your skills. Print the stored two-sided p-value for Ads.
Write your answer, then run it.
5. Read a 95% interval
Build your skills. Print the coefficient interval for Ads.
Write your answer, then run it.
6. Calculate a critical value
Build your skills. Calculate the two-sided 5% critical t value using df_resid.
Write your answer, then run it.
7. Use a nonzero null
Build your skills. Test Ads slope=2; print the t statistic and two-sided p-value.
Write your answer, then run it.
8. Test a different null
Challenge. For H0: Ads slope=3 against a two-sided alternative, print the p-value.
Write your answer, then run it.
9. Compare confidence levels
Challenge. Print widths of 95% and 99% Ads intervals.
Write your answer, then run it.
10. Check agreement of test and interval
Challenge. Print whether the 95% Ads interval excludes zero, and whether the classical two-sided p-value is below 0.05.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Read a standard error
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(model.bse["Ads"], 4))Expected output
0.2225This is coefficient uncertainty, not outcome spread.
2. Read degrees of freedom
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(int(model.df_resid))Expected output
6Eight observations minus the intercept and one slope gives six.
3. Reconstruct the default t statistic
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(model.params["Ads"] / model.bse["Ads"], 4))Expected output
9.8446The null is zero in the default coefficient table.
4. Read a two-sided p-value
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(model.pvalues["Ads"], 6))Expected output
6.3e-05This applies to slope=0 under the classical fitted model.
5. Read a 95% interval
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(model.conf_int().loc["Ads"].round(4).to_list())Expected output
[1.646, 2.7349]These are lower and upper coefficient limits, not sales predictions.
6. Calculate a critical value
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
from scipy import stats
print(round(stats.t.ppf(0.975, model.df_resid), 4))Expected output
2.4469The upper critical value is the 97.5th percentile.
7. Use a nonzero null
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
from scipy import stats
t_stat = (model.params["Ads"] - 2) / model.bse["Ads"]
print(round(t_stat, 4))
print(round(2 * stats.t.sf(abs(t_stat), model.df_resid), 6))Expected output
0.8561
0.424831Subtract 2 rather than reading the stored zero-null p-value.
8. Test a different null
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
from scipy import stats
t_stat = (model.params["Ads"] - 3) / model.bse["Ads"]
print(round(2 * stats.t.sf(abs(t_stat), model.df_resid), 6))Expected output
0.010858Count equally extreme departures on both sides of the null value 3.
9. Compare confidence levels
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
ci95 = model.conf_int(alpha=0.05).loc["Ads"]
ci99 = model.conf_int(alpha=0.01).loc["Ads"]
print(round(ci95.iloc[1] - ci95.iloc[0], 4))
print(round(ci99.iloc[1] - ci99.iloc[0], 4))Expected output
1.0889
1.6498Higher confidence requires a wider interval.
10. Check agreement of test and interval
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
ci = model.conf_int().loc["Ads"]
print(bool((ci.iloc[0] > 0) or (ci.iloc[1] < 0)))
print(bool(model.pvalues["Ads"] < 0.05))Expected output
True
TrueFor the same classical procedure, these decisions agree.
Point Predictions and Two Kinds of Interval
Separate a conditional mean from one new observation, and recognise interpolation and extrapolation.
Two Prediction Questions
At Ads=4, what is the mean revenue across comparable weeks? What revenue might one new week produce? The point estimate is the same, but the second question also includes individual-week variation.
Mean Confidence Interval versus Prediction Interval
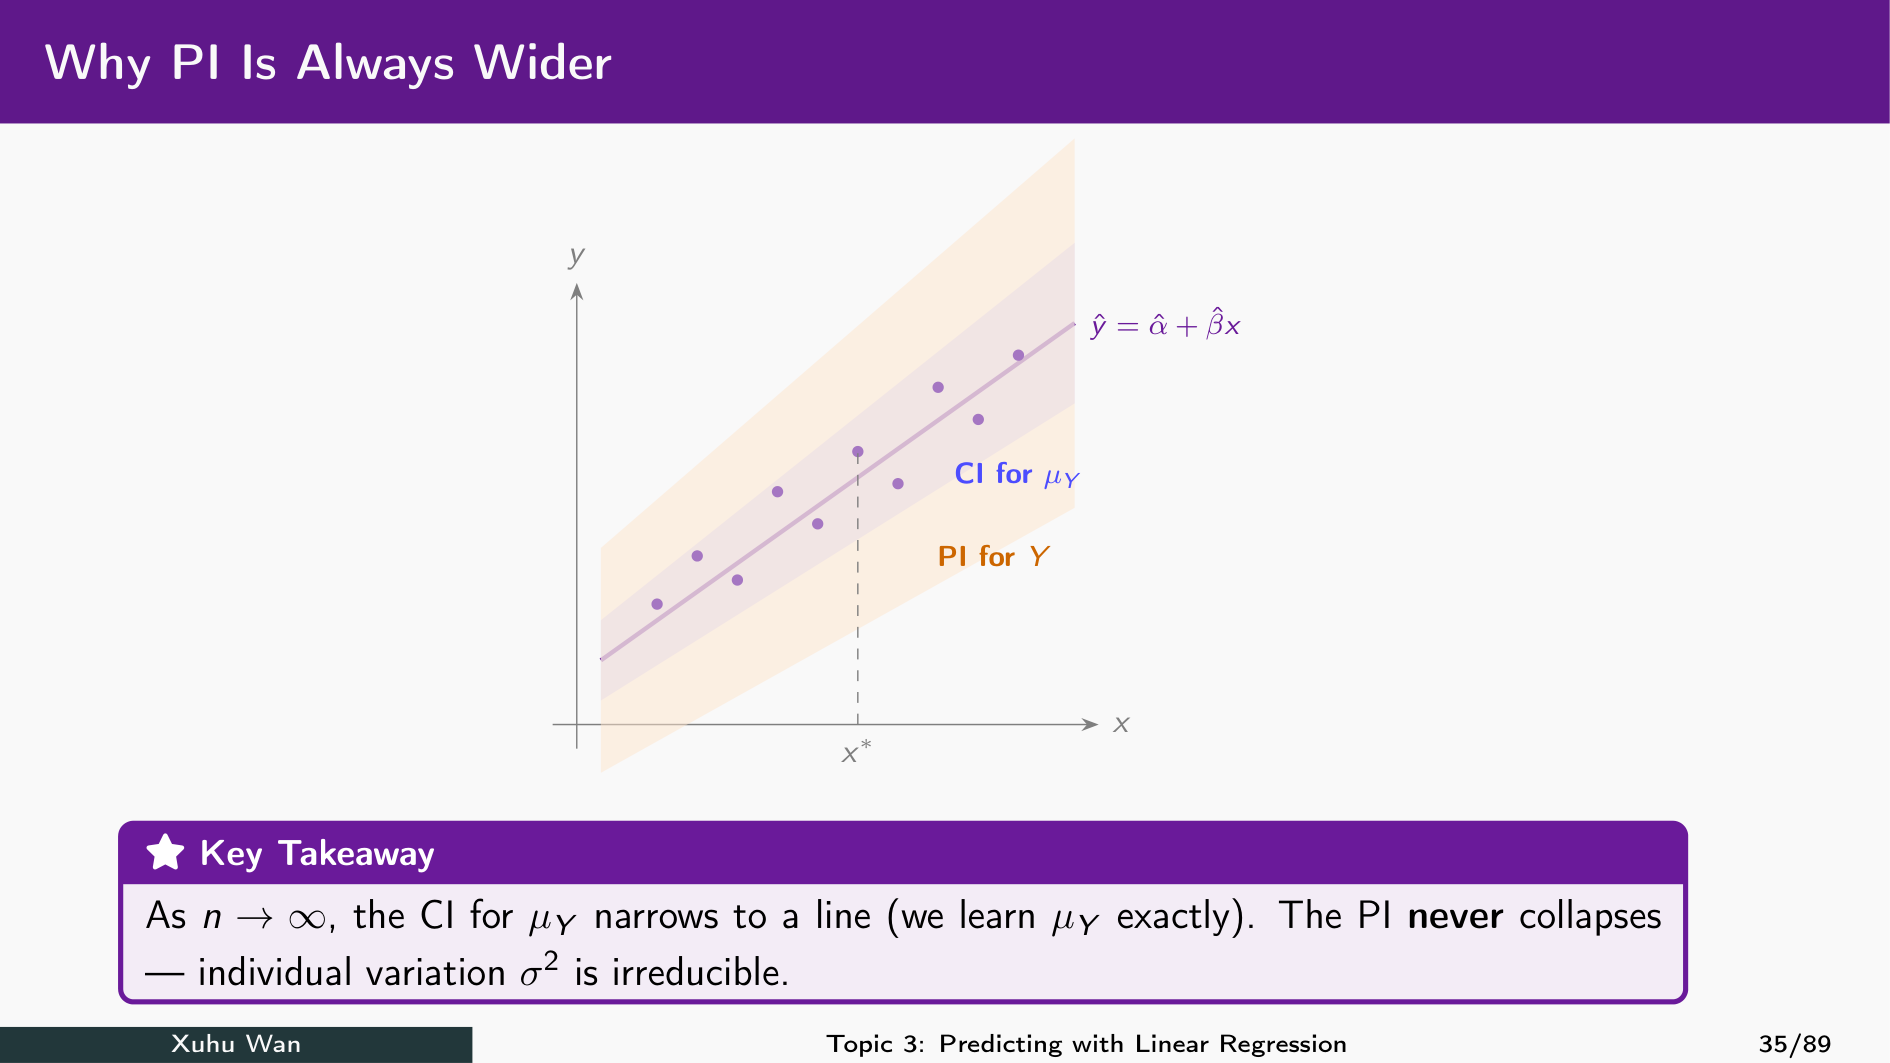
The inner band describes uncertainty in the mean line. The outer band describes uncertainty for one new outcome. Under the same classical model and confidence level, the individual prediction interval is wider when residual variance is positive.
The schematic communicates the distinction; the next Python plot calculates the actual intervals for the retail observations. More data can estimate the mean more precisely, but individual outcome variation remains.
Read the Prediction Symbols
For the retail example, choose advertising of 4 thousand HKD.
| Symbol | Meaning | Retail example |
|---|---|---|
| \(x_0\) | The predictor value where we want a prediction | Ads = 4 |
| \(\mu_0=E[Y\mid X=x_0]\) | Unknown population mean outcome at this input | Average revenue across comparable weeks with Ads = 4 |
| \(\hat y_0=\hat\beta_0+\hat\beta_1x_0\) | Our estimate of that mean, read from the fitted line | Fitted average revenue at Ads = 4 |
| \(Y_0\) | One new, not-yet-observed outcome at this input | Revenue for one future week with Ads = 4 |
The subscript 0 labels the target case; it does not mean \(X=0\). A hat means estimated from the training sample.
The fitted mean estimates average Y at x0. One new outcome also contains its own underlying noise.
What Does SE of the Fitted Mean Measure?
If we collected another training sample and fitted again, the line and \(\hat y_0\) would change. \(SE(\hat y_0)\) estimates the standard deviation of this mean estimator across repeated samples.
\[SE(\hat y_0)=s\sqrt{\frac{1}{n}+\frac{(x_0-\bar x)^2}{S_{xx}}},\qquad S_{xx}=\sum_{i=1}^{n}(x_i-\bar x)^2.\]
Here \(n\) is training sample size, \(\bar x\) is the training mean of \(X\), and \(S_{xx}\) measures its spread. \(s\) is regression RMSE, our estimate of the underlying noise standard deviation \(\sigma\).
For Ads = 4: \(n=8\), \(\bar x=4.5\), \(S_{xx}=42\), \(s=1.442\), giving \(SE(\hat y_0)\approx0.522\) thousand HKD. Across repeated training samples, the fitted average at Ads = 4 would vary; we estimate that variation’s standard deviation as about HKD 522. This measures how precisely we estimate the average, not how much one week’s revenue varies.
These are classical SLR formulas with an intercept and independent, constant-variance errors. Normal errors give the exact finite-sample t intervals used here. The mean standard error is smallest near the training X mean and larger far from it.
No. s estimates individual noise spread; mean_se estimates uncertainty in the fitted conditional mean at the chosen input.
Confidence Interval: For the Average Revenue
Question: with advertising fixed at HKD 4,000, what is the average revenue across comparable weeks? The target is the unknown population mean \(\mu_0=E[Y\mid X=4]\).
\[\text{95% mean CI: }\quad \hat y_0\pm t^*SE(\hat y_0)\] \[=\hat y_0\pm t^*s\sqrt{\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}}.\]
- \(\hat y_0\): fitted average; \(SE(\hat y_0)\): uncertainty in that estimated average.
- \(t^*=t_{0.975,n-2}\): the 95% critical t value for simple linear regression. With \(n=8\), \(t^*=2.447\).
Example (HKD thousands):
\[18.405\pm2.447(0.522)\ \approx\ [17.128,\ 19.682].\]
We are 95% confident that the population average revenue at Ads = 4 lies between approximately HKD 17,128 and HKD 19,682. This interval is for the average, not one particular week.
These are pointwise intervals at the specified x0, not simultaneous confidence bands for all x. Under the classical model assumptions, 95% of intervals produced by repeated training samples cover the fixed true conditional mean. The population mean is fixed; the calculated endpoints change between samples. This is not a prediction interval for the realised average of a finite set of future weeks. Numerical endpoints use the unrounded fit.
No. Its target is the unknown population average at the chosen advertising input.
Prediction Interval: For One New Week
Question: with advertising fixed at HKD 4,000, what revenue might one new week produce? The target is that week’s unknown outcome \(Y_0\).
\[\text{95% individual PI: }\quad\hat y_0\pm t^*\sqrt{SE(\hat y_0)^2+s^2}\] \[=\hat y_0\pm t^*s\sqrt{1+\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}}.\]
- \(SE(\hat y_0)^2\): uncertainty in the estimated average.
- Extra \(s^2\): variation from the new week’s own noise. Here \(s=1.442\) and \(t^*=2.447\).
Same example (HKD thousands):
\[18.405\pm2.447\sqrt{0.522^2+1.442^2}\ \approx\ [14.652,\ 22.157].\]
The 95% prediction interval for one new week’s revenue is approximately HKD 14,652 to HKD 22,157. It is wider than the mean CI because one week can differ from the population average. Use this interval when planning for one future week.
For simple linear regression, s=sqrt(SSE/(n−2)) is the course RMSE convention. Both formulas assume the same correctly specified linear model with independent, normally distributed, constant-variance errors, and a new observation independent of the fitting sample. Repeatedly fitting samples and predicting one new outcome at the same input gives 95% coverage under these assumptions. This is not a guaranteed range or a worst-case bound. The prediction standard error sqrt(mean_se²+s²) differs from the coefficient SE and mean SE. Numerical endpoints use the unrounded fit.
Even with the population average known exactly, one new week would still vary around it.
Ask statsmodels for Both Intervals
For \(x_0=4\), .get_prediction(new).summary_frame(alpha=0.05) returns:
| Output column | Symbol and meaning |
|---|---|
mean |
\(\hat y_0\): estimated mean revenue |
mean_se |
\(SE(\hat y_0)\): standard error of that estimated mean |
mean_ci_lower, mean_ci_upper |
95% confidence interval for the unknown mean \(\mu_0\) |
obs_ci_lower, obs_ci_upper |
95% prediction interval for one new outcome \(Y_0\) |
Both intervals are centred on \(\hat y_0\). The PI includes the new week’s own noise as well as uncertainty in the fitted mean.
Sources: Prediction results
Render Both Bands from the Same Fit
The numerical bands are narrowest near the centre of the observed Ads values. The outer band adds residual variation. Change alpha to 0.01 to request 99% intervals.
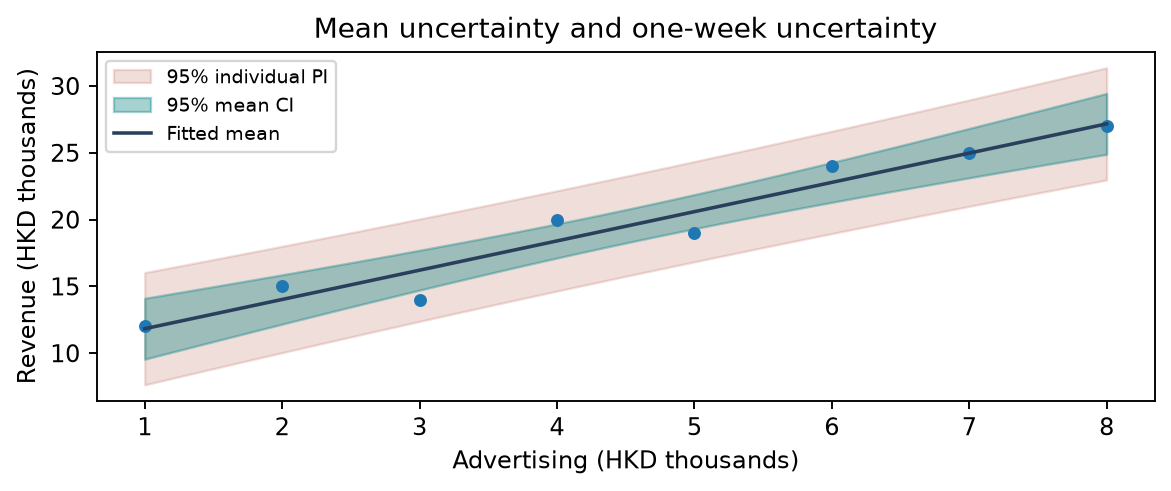
Why the Extra Term Matters
A mean confidence interval describes uncertainty about the average at \(x_0\). A prediction interval must also allow for one new observation’s own noise.
\[\text{Mean CI: }\hat y_0\pm t^*SE(\hat y_0).\] \[\text{Individual PI: }\hat y_0\pm t^*\sqrt{SE(\hat y_0)^2+s^2}.\]
\(s^2\) estimates the variance of the underlying noise. \(t^*=t_{0.975,n-2}\) is the 95% critical value for SLR. The extra \(s^2\) makes the PI wider. Both intervals use the same \(x_0\), fitted model and confidence level.
Multiply either standard error by the same critical t value to obtain its interval half-width. These formulas depend on the classical model; they do not protect against a wrong functional form or a future business regime change.
Interpolation and Extrapolation
Ads=4 lies inside the observed 1–8 range. Ads=15 lies outside it: extrapolation. A numerical prediction still exists, but the fitted relationship is not checked there by our observations.
Use the Interval for the Decision
An inventory decision for one future week needs individual-outcome uncertainty, not just a precise estimate of average demand. A 95% PI is not a worst-case bound and is conditional on the inputs and assumptions.
For many future weeks, uncertainty in their total also depends on whether errors are related over time. Do not multiply a single-week prediction interval by the number of weeks and call it a valid total interval.
In-Class Practice: Mean or One Week?
Produce the mean CI and individual PI at Ads=6. Print both widths and explain which is relevant when planning stock for a single week.
Interactive Intervals: Change the Input and Confidence
Move Ads within and beyond the observed range and switch 95% to 99% confidence. Compare the fitted mean, mean CI, and individual PI for the eight-week retail model.
Section 5 Practice — Point Predictions and Two Kinds of Interval
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Create a prediction row
Warm-up. Print a one-row design table for Ads=4.
Write your answer, then run it.
2. Calculate a point prediction
Warm-up. Print predicted revenue at Ads=4.
Write your answer, then run it.
3. Read the mean interval
Warm-up. Print only the 95% mean CI at Ads=4.
Write your answer, then run it.
4. Read the individual interval
Build your skills. Print only the 95% individual PI at Ads=4.
Write your answer, then run it.
5. Compare widths
Build your skills. Print the widths of both intervals at Ads=4.
Write your answer, then run it.
6. Change the confidence level
Build your skills. Print the 99% individual PI at Ads=4.
Write your answer, then run it.
7. Predict several inputs
Build your skills. Print mean predictions for Ads=2,4,6 together.
Write your answer, then run it.
8. Detect extrapolation
Challenge. Print whether Ads=15 is inside the observed predictor range.
Write your answer, then run it.
9. Compare centre and edge uncertainty
Challenge. Compare the mean standard errors at Ads=4.5 and Ads=8.
Write your answer, then run it.
10. Reconstruct a mean standard error
Challenge. Manually calculate the mean SE at Ads=4 and compare it with summary_frame.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Create a prediction row
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [4]})
print(new)Expected output
   const  Ads
0 1 4The constant and predictor columns match the fitted design.
2. Calculate a point prediction
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [4]})
print(round(model.predict(new).iloc[0], 3))Expected output
18.405This is a fitted conditional mean.
3. Read the mean interval
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [4]})
p = model.get_prediction(new).summary_frame()
print(p[["mean_ci_lower", "mean_ci_upper"]].round(3))Expected output
   mean_ci_lower  mean_ci_upper
0 17.128 19.682The interval concerns the mean for comparable weeks.
4. Read the individual interval
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [4]})
p = model.get_prediction(new).summary_frame()
print(p[["obs_ci_lower", "obs_ci_upper"]].round(3))Expected output
   obs_ci_lower  obs_ci_upper
0 14.652 22.157The interval includes variation of one new outcome.
5. Compare widths
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [4]})
p = model.get_prediction(new).summary_frame().iloc[0]
print(round(p["mean_ci_upper"] - p["mean_ci_lower"], 3))
print(round(p["obs_ci_upper"] - p["obs_ci_lower"], 3))Expected output
2.554
7.505Individual variation makes the PI wider.
6. Change the confidence level
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [4]})
p = model.get_prediction(new).summary_frame(alpha=0.01)
print(p[["obs_ci_lower", "obs_ci_upper"]].round(3))Expected output
   obs_ci_lower  obs_ci_upper
0 12.719 24.09alpha=0.01 requests 99% rather than 95% coverage.
7. Predict several inputs
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1, 1, 1], "Ads": [2, 4, 6]})
print(model.predict(new).round(3).to_list())Expected output
[14.024, 18.405, 22.786]Each row supplies one scenario.
8. Detect extrapolation
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(bool(sales["Ads"].min() <= 15 <= sales["Ads"].max()))Expected output
FalseA computable prediction can still be extrapolation.
9. Compare centre and edge uncertainty
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1, 1], "Ads": [4.5, 8]})
p = model.get_prediction(new).summary_frame()
print(p["mean_se"].round(3).to_list())Expected output
[0.51, 0.931]With this simple model, mean uncertainty is smaller near the sample X mean.
10. Reconstruct a mean standard error
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
import numpy as np
x = sales["Ads"]
sxx = ((x - x.mean()) ** 2).sum()
se = np.sqrt(model.mse_resid * (1 / len(x) + (4 - x.mean()) ** 2 / sxx))
p = model.get_prediction(pd.DataFrame({"const": [1], "Ads": [4]})).summary_frame()
print(round(se, 4), round(p["mean_se"].iloc[0], 4))Expected output
0.5218 0.5218The manual calculation matches the software under the same fitted model.
Residual Analysis and Unusual Observations
Use residual plots to question the model assumptions and distinguish a large residual from high leverage.
LINE Is a Diagnostic Checklist
L: linear conditional mean. I: independent errors. N: normal errors for classical exact small-sample inference. E: equal error variance. Normal X values are not required; a scatterplot alone cannot verify the full checklist.
A correctly specified conditional mean also requires zero conditional mean error, E(ε|X)=0. This is needed for standard coefficient interpretations but cannot be established just by looking at residuals. Exact collinearity must also be absent. With time series, dependence deserves particular attention.
Four Assumptions: Which Plot Should We Use?
Use residuals as observable clues about the model’s unobserved errors.
| Assumption | Visual check | What we hope to see | Warning pattern |
|---|---|---|---|
| L — Linear mean | Residuals vs fitted values (or predictor \(X\)) | Points centred near zero without a curve | U-shape, curve, systematic pattern |
| I — Independent errors | Residuals vs time / meaningful observation order | No runs, cycles or persistent pattern | Long runs above/below zero, cycles |
| N — Normal errors | Normal Q–Q plot of residuals | Points roughly follow the reference line | Systematic bending or large tail departures |
| E — Equal variance | Residuals vs fitted values; absolute residuals vs fitted values | Roughly constant vertical spread | Fan/funnel shape or rising residual magnitude |
The same residual plot checks L through its centre and E through its spread. Plots reveal warning signs; they cannot prove the assumptions.
Independence also depends on how observations were collected: repeated customers, related units and time ordering matter. An arbitrary row-order plot cannot rule out dependence in cross-sectional data. Normality concerns the errors conditional on X, not the distribution of X; Q–Q plots inspect residuals as proxies. The following pages show the corresponding plotting code.
A curved centre warns about the mean form (L); changing vertical spread warns about unequal error variance (E).
Residuals versus Fitted Values
Look for a curved pattern or changing spread around zero. The fitted mean may be too simple if the residual pattern is systematic. Eight points are useful for explanation, but weak evidence for diagnosing a real business process.
\[\text{Horizontal: }\hat y_i\qquad\text{Vertical: }e_i=y_i-\hat y_i\qquad\text{Reference: }e_i=0.\]
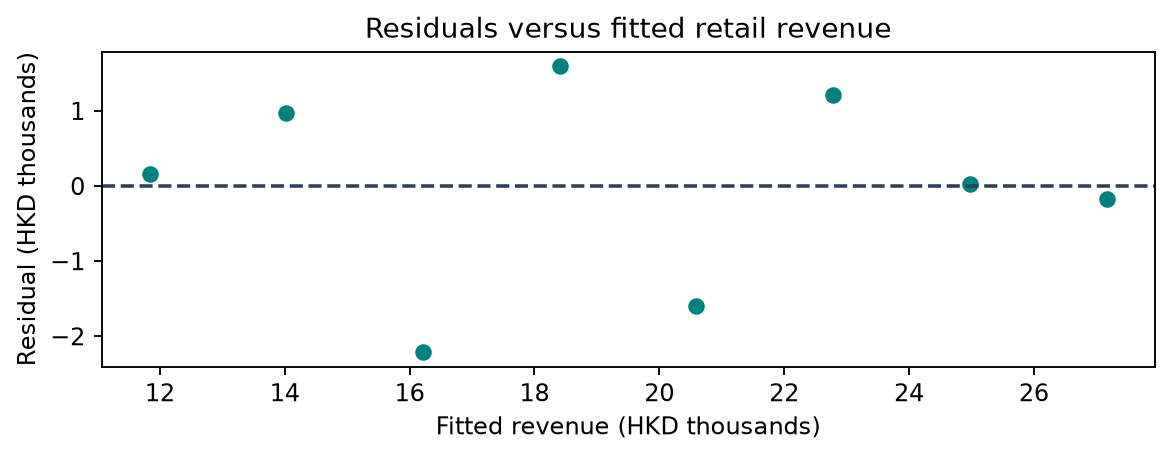
Illustration: Curvature and a Fan Shape
These constructed diagnostic examples show two warning patterns. A curved residual pattern suggests a missing shape in the mean; widening spread suggests nonconstant variance. These are illustrations, not fitted evidence about NVDA.
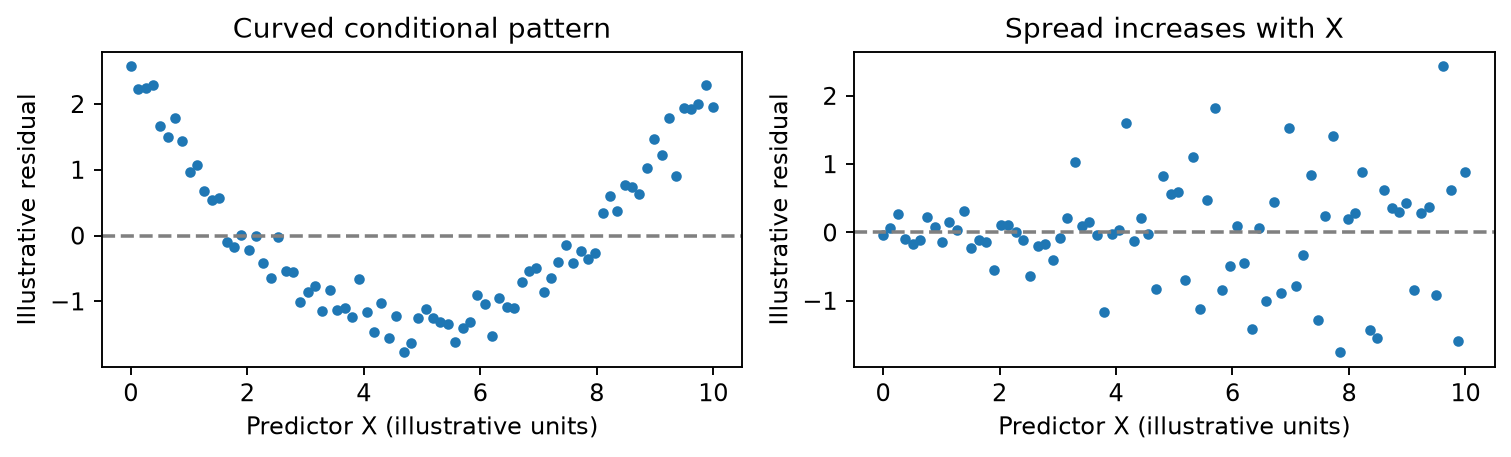
Interactive Residuals: Recognise the Warning
Switch among no clear pattern, a curve, and a widening fan. Predict what each picture suggests before revealing the explanation. These are schematic residual plots.
A curve suggests the conditional mean may need a different form. A fan suggests nonconstant error variance. A pattern-free plot does not establish independence, normality, or every other regression assumption.
The error spread changes with fitted values; investigate the constant-variance assumption.
Independence: Inspect Time Order
For daily returns, plot residuals by date. Consecutive runs, persistence, or volatility bursts deserve investigation. A random-looking plot is not proof of independence.
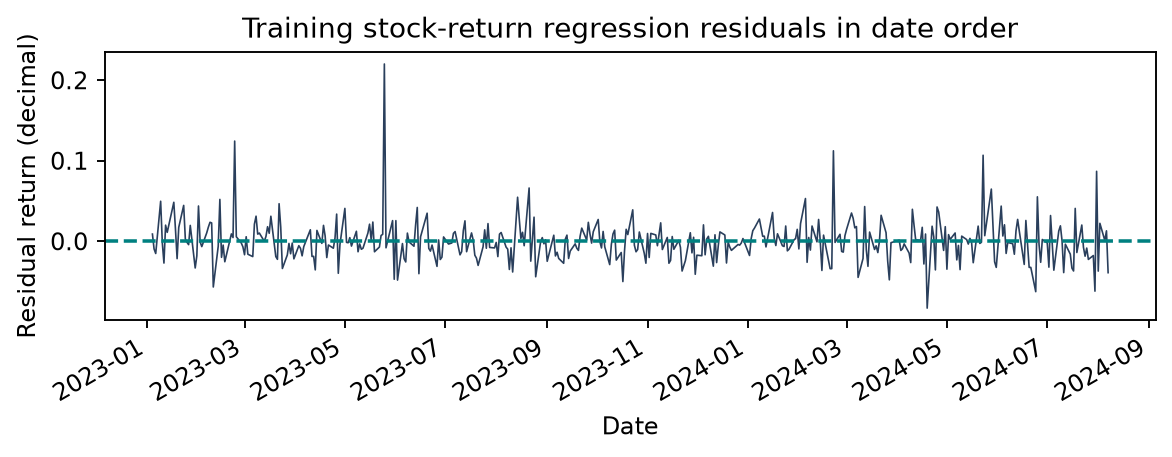
Normality: Read a Q-Q Plot
A normal Q-Q plot compares ordered residuals with normal reference quantiles. Tail deviations suggest departures from normality. The question is about errors, using residuals as a diagnostic proxy, not whether market returns themselves must be normal.
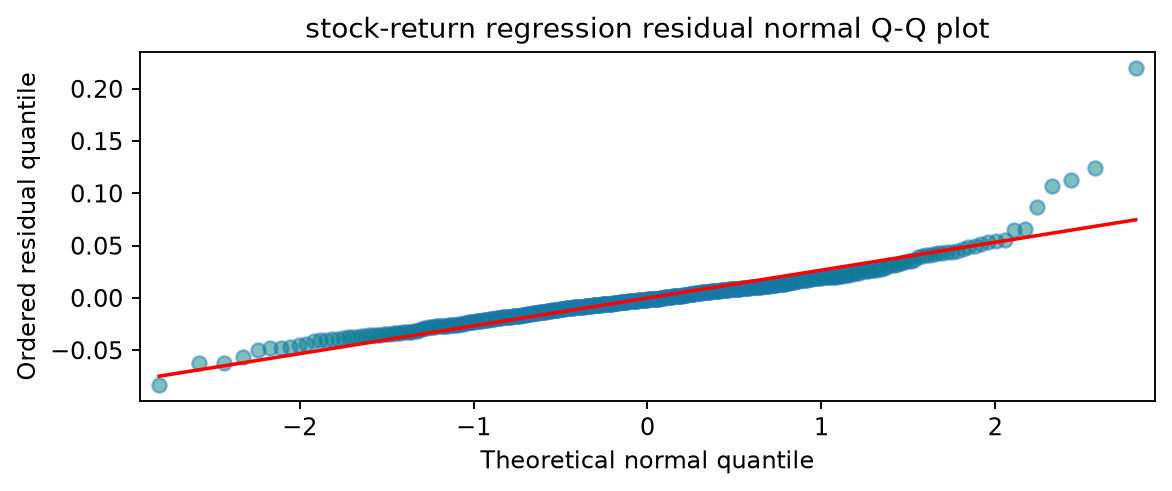
Equal Variance: Inspect the Spread
Plot absolute residual size against fitted values. A systematic rise in the spread may contradict equal variance. A constant-looking spread does not resolve independence or the correctness of the mean equation.
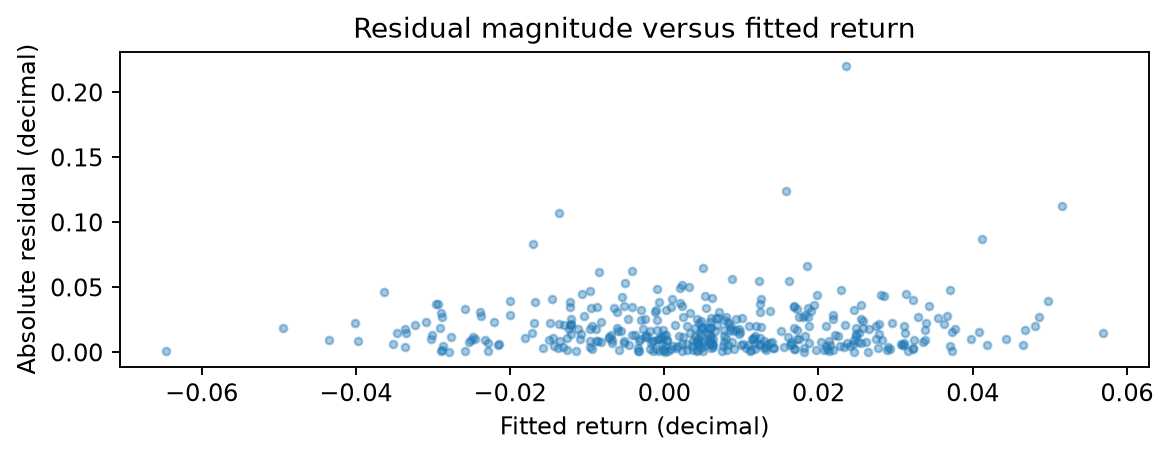
Outlier, Leverage, and Influence
A large residual is an unusual Y relative to the fitted line. High leverage is an unusual predictor position. Influence means an observation substantially changes the fit. These are related but different ideas.
Investigate data errors, unusual events, and model scope before removing a row. A valid unusual observation may be important to the business problem. Cook’s distance combines residual size and leverage; thresholds are screening aids rather than automatic deletion rules.
Interactive Observation: Does One Point Change the Fit?
Switch an extra observation on and off: Ads=20, Revenue=12. Its predictor is far outside the original 1–8 range. Compare slope and SSE, then explain why the point needs a business explanation.
Render the Effect of an Unusual Week
Both lines use OLS with an intercept. The extra observation changes the model, not just its correlation. Do not delete a genuine week simply to make a line look better.
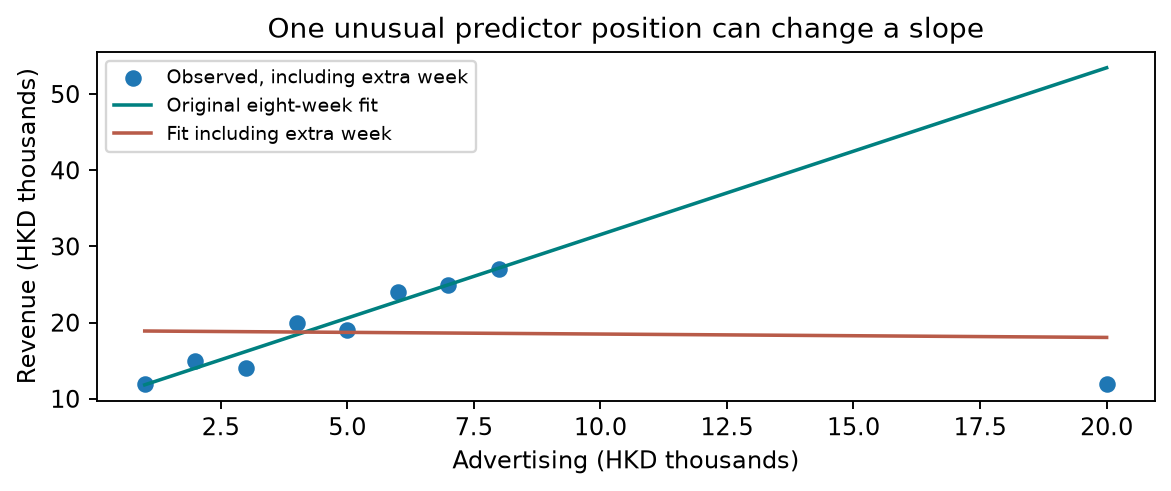
In-Class Practice: Investigate a Residual
Find the retail week with the largest absolute residual. Print its complete record and explain two possible reasons for the deviation that would require additional evidence.
Section 6 Practice — Residual Analysis and Unusual Observations
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Read residuals
Warm-up. Print the first three residuals.
Write your answer, then run it.
2. Check residual mean
Warm-up. Print the mean residual rounded to six decimals.
Write your answer, then run it.
3. Find the largest residual magnitude
Warm-up. Print the week index with greatest absolute residual.
Write your answer, then run it.
4. Read the unusual record
Build your skills. Print the complete row for the largest absolute residual.
Write your answer, then run it.
5. Read leverage
Build your skills. Print all leverage values rounded to three decimals.
Write your answer, then run it.
6. Read Cook’s distance
Build your skills. Print the index with highest Cook’s distance.
Write your answer, then run it.
7. Choose a time-order diagnostic
Build your skills. Print the plot used to investigate error independence, and one warning pattern.
Write your answer, then run it.
8. Compare a leave-one-out fit
Challenge. Remove the row with index 7 (the eighth week), refit, and print the original and revised slopes.
Write your answer, then run it.
9. Match assumptions to plots
Challenge. Print the visual check for each of the four LINE assumptions.
Write your answer, then run it.
10. Separate a diagnostic from a guarantee
Challenge. Print residual mean and a sentence explaining why it cannot verify the population zero-conditional-mean assumption.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Read residuals
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(model.resid.head(3).round(3))Expected output
0    0.167
1    0.976
2   -2.214
dtype: float64Residuals are observed minus fitted outcomes.
2. Check residual mean
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(model.resid.mean(), 6))Expected output
0.0OLS with an intercept makes the sample residual mean essentially zero; this does not prove exogeneity.
3. Find the largest residual magnitude
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(model.resid.abs().idxmax())Expected output
2Absolute size differs from choosing the largest signed residual.
4. Read the unusual record
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
week = model.resid.abs().idxmax()
print(sales.loc[week])Expected output
Ads         3
Revenue    14
Price      10
Name: 2, dtype: int64Context is needed before deciding that a row is erroneous.
5. Read leverage
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
influence = model.get_influence()
print(pd.Series(influence.hat_matrix_diag).round(3).to_list())Expected output
[0.417, 0.274, 0.179, 0.131, 0.131, 0.179, 0.274, 0.417]Leverage depends on predictor positions, not directly on residual size.
6. Read Cook's distance
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
influence = model.get_influence()
cook = pd.Series(influence.cooks_distance[0])
print(cook.idxmax())Expected output
2Influence combines predictor position and deviation from the fitted line.
7. Choose a time-order diagnostic
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print("Plot residuals against time or meaningful observation order.")
print(
    "Long runs above or below zero can warn of dependence; a random-looking plot does not prove independence."
)Expected output
Plot residuals against time or meaningful observation order.
Long runs above or below zero can warn of dependence; a random-looking plot does not prove independence.The time-order plot has already been introduced; no new method is required.
8. Compare a leave-one-out fit
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
reduced = sales.drop(index=7)
changed = sm.OLS(reduced["Revenue"], sm.add_constant(reduced[["Ads"]])).fit()
print(round(model.params["Ads"], 4), round(changed.params["Ads"], 4))Expected output
2.1905 2.2143A sensitivity comparison is informative; it does not justify deleting the week.
9. Match assumptions to plots
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print("L: residuals versus fitted values; look for curvature")
print("I: residuals versus time or meaningful order; look for runs or cycles")
print("N: normal Q-Q plot of residuals; look for departures from the reference line")
print("E: residuals or absolute residuals versus fitted values; look for changing spread")Expected output
L: residuals versus fitted values; look for curvature
I: residuals versus time or meaningful order; look for runs or cycles
N: normal Q-Q plot of residuals; look for departures from the reference line
E: residuals or absolute residuals versus fitted values; look for changing spreadPlots can reveal warning patterns but cannot prove that the assumptions hold.
10. Separate a diagnostic from a guarantee
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(round(model.resid.mean(), 6))
print("The fitted residual mean is an OLS identity, not proof of E(error | X)=0.")Expected output
0.0
The fitted residual mean is an OLS identity, not proof of E(error | X)=0.A sample fitting identity is not evidence that confounding is absent.
Multiple Linear Regression and Multicollinearity
Use city demographics to model annual pharmacy profit, interpret partial coefficients, and assess multicollinearity.
Pharmacy Profit: Why Use Several Predictors?
| Source column | Meaning and unit |
|---|---|
Profit |
Annual pharmacy profit, US dollars; the outcome Y |
Income |
City median annual salary, US dollars |
Disposable Income |
City median income after taxes, US dollars |
Birth Rate (per 1,000) |
Births per 1,000 residents |
Soc Security (per 1,000) |
Social-security recipients per 1,000 residents |
CV Death (per 100,000) |
Cardiovascular deaths per 100,000 residents |
% 65 or Older |
Residents aged 65+, in percentage points: 14 means 14% |
Location identifies a city; it is not a numerical predictor. The file contains 110 cities with observed profit and one proposed Kansas City location with no profit yet.
A pharmacy chain wants to understand how annual profit is associated with the surrounding city. The original case has 110 existing cities and a proposed Kansas City store. Do not fill the missing proposed profit or fit it as if it were observed. The data are cross-sectional cities, not 111 dated observations.
Read the Six-Predictor Design Table
The response is annual Profit. The design table contains an intercept column const and six demographic columns. sm.add_constant() creates the column of ones; .fit() estimates all seven coefficients together.
The order of the design columns must match the order used for prediction. Location is an identifier, not an input to this numerical model. With 110 complete rows and six predictors, residual degrees of freedom are 110−6−1=103.
Partial Coefficients Have Units
Compare two otherwise identical demographic profiles. Hold the other five predictors fixed.
| Input difference | Difference in fitted annual profit, full model |
|---|---|
| Income higher by US$1,000 | About US$599 higher |
| Disposable income higher by US$1,000 | About US$2,535 higher |
| Birth rate higher by 1 birth per 1,000 | About US$1,704 higher |
| Age 65+ share higher by 1 percentage point | About US$7,714 higher |
A slope describes a fitted association conditional on the included inputs. It is not a causal effect, a probability or a change that every individual store must experience. One percentage point means, for example, 11% to 12%, rather than a 1% proportional increase. The intercept predicts profit when all six inputs are zero, a profile far from these cities.
Interactive Prediction: Hold the Other Inputs Fixed
Each line keeps the other inputs fixed. Move disposable income along it, or change the age-65+ share. Both axes use USD thousands.
The widget uses the six-predictor fit to all 110 observed cities. Income is fixed at US$28,774, birth rate at 14.4 per 1,000, social-security recipients at 148.8 per 1,000 and cardiovascular deaths at 338.5 per 100,000. These are the proposed city’s supplied inputs. Moving an input illustrates the fitted equation; it does not establish a feasible intervention or causal effect.
R-Squared versus Adjusted R-Squared
Compare Income-only and six-predictor models on the same 110 cities. Adding inputs cannot lower training R² when both models include an intercept. Adjusted R² also accounts for the number of fitted predictors; it can fall when an added input contributes too little.
These are explanatory fits to all observed cities. Section 3.9 will demonstrate model selection using separate training, validation and test cities. A high training R² does not by itself establish reliable predictions or causal effects.
Adjusted R-Squared: Allow for the Number of Predictors
\(R^2_{adj}=1-\dfrac{SSE/(n-k-1)}{SST/(n-1)}\). Here \(n=110\), \(k=6\) and \(n-k-1=103\). The intercept is estimated but is not counted in \(k\).
Compare models on identical outcome rows. Adjusted R² is unitless and can be negative. Do not count Location as a predictor or count the intercept twice.
MLR RMSE: Allow for All Estimated Coefficients
The course uses regression RMSE \(s=\sqrt{SSE/(n-k-1)}\). Six demographic predictors and one intercept leave 103 residual degrees of freedom. Here \(s\approx\text{US}\$13,547\) per year.
The unit is the same as Profit: annual US dollars, not a percentage. Throughout this chapter the course reports s with n−k−1 in the denominator, including explicitly labelled holdout comparisons.
What Is Multicollinearity?
Multicollinearity is linear dependence among the predictors. If one input is nearly a linear combination of the others, little independent variation remains to estimate its separate association with profit.
In these cities, social-security recipients and the share aged 65+ move closely together.
Perfect dependence: coefficients are not uniquely identifiable. Strong imperfect dependence: coefficients can be estimated but may be imprecise.
The relevant dependence is among X variables, rather than a strong relationship between X and Profit. More than two predictors can create near dependence even without an extreme pairwise correlation. Perfect dependence makes the design rank deficient; a reported generalized-inverse solution is not proof of unique coefficients.
Multicollinearity: Coefficients and Standard Errors
Strong imperfect dependence makes the separate predictor associations hard to estimate.
| What changes? | Consequence |
|---|---|
| Coefficient estimates | Small data changes can alter their size or sign; estimates depend on the other predictors included. |
| Standard errors | Coefficient variance and SE increase, other conditions held fixed. |
| Numerical stability | Near-perfect dependence can amplify rounding and numerical errors. |
Not automatic bias: imperfect multicollinearity does not itself bias OLS under a correctly specified, full-rank model with zero conditional mean error.
The variance comparison holds the error variance, sample size and predictor variation fixed. Statistical imprecision differs from numerical instability, although extreme near dependence can cause both. Perfect dependence removes unique identification. Do not delete a substantively necessary variable solely to reduce a VIF; omission can bias a differently specified model.
Sources: Penn State STAT 501: multicollinearity, inference and prediction · statsmodels: perfect multicollinearity and numerical instability
Multicollinearity: Tests and Confidence Intervals
Individual t-tests and coefficient intervals depend on the coefficient SE.
| What changes? | Consequence |
|---|---|
| Individual t-tests | Lower power; a useful predictor may have a large p-value after accounting for the others. |
| Coefficient confidence intervals | Wider intervals can include zero and both signs. |
| Overall F-test and R² | A significant joint test and high training R² can coexist with weak individual t-tests. |
A large p-value can reflect imprecision, rather than the absence of a useful association.
The variance comparison holds the error variance, sample size and variation of the predictor of interest fixed. For a conventional two-sided test, a larger SE reduces the absolute t statistic for a given estimate and null value, lowering power; actual p-values need not always rise because estimates can change too. A nonsignificant individual test is not evidence that a predictor is useless, and the overall F-test pattern is a possible symptom rather than proof of multicollinearity. Under the classical assumptions and full rank, confidence intervals and tests remain valid; the main problem is imprecision, not automatic loss of coverage. Near-perfect dependence can also cause numerical instability. Dropping a substantively necessary predictor can introduce omitted-variable bias; a large VIF alone is not an instruction to delete it.
Sources: Penn State STAT 501: multicollinearity, inference and prediction · statsmodels: perfect multicollinearity and numerical instability
Multicollinearity: Prediction and Prediction Intervals
Individual coefficients can be uncertain while their combined prediction remains precise for familiar input combinations.
| Target | What multicollinearity means |
|---|---|
| Point prediction | Can remain stable for familiar combinations; validate accuracy on test data. |
| Mean-response CI | Can remain narrow for familiar combinations, but widen for unusual combinations. |
| New-outcome PI | Adds new-outcome noise to fitted-mean uncertainty; not automatically wide. |
Joint support matters: familiar social-security and age-share ranges do not guarantee a familiar combination. Validate predictions on representative test data.
The uncertainty of a predicted mean depends on the covariances among coefficient estimates as well as their individual variances. Large individual coefficient SEs can coexist with a precise fitted mean for well-supported predictor combinations. Predictions that depart from the observed relationship among predictors can be much more uncertain, even when neither input separately exceeds its observed range. This is why prediction quality must be assessed on held-out records representative of the intended use. A new-outcome prediction interval adds irreducible outcome variation and, under the same classical model and confidence level, is wider than the mean-response interval. Multicollinearity alone guarantees neither bad nor good predictions.
Sources: Penn State STAT 501: multicollinearity, inference and prediction
VIF: Predict a Predictor with the Others
For each demographic input \(X_j\), fit an auxiliary regression on the other five inputs. Then \(VIF_j=1/(1-R_j^2)\). Profit is not used in this auxiliary regression. A large value signals little variation unique to that input.
In this full observed-city design the social-security and age-65+ VIFs are about 10.04 and 11.39. These are descriptive warnings, not automatic deletion rules. Removing a substantively necessary predictor can change the meaning of the other coefficients.
Three Predictors: What Are the Auxiliary R-Squared Values?
For a smaller VIF illustration, use Income, Disposable Income and the age-65+ share. Fit three auxiliary regressions. Each takes one of these inputs as its response and the other two as predictors. Do not use Profit.
These numbers concern this three-input demonstration. They differ from full six-input VIFs because the auxiliary regressions use different predictor lists. Neither is the R² of the model whose outcome is Profit.
Illustration: VIF Grows Near Dependence
The relationship is nonlinear: auxiliary R² of 0.5 gives VIF=2; 0.9 gives VIF=10; 0.99 gives VIF=100. The graph illustrates the formula rather than six estimated pharmacy VIFs.
Overall F-Test: Do the Predictors Help Together?
\(H_0:b_1=b_2=\cdots=b_6=0\) versus \(H_1\): at least one slope differs from zero. Compare the six-input profit model with an intercept-only mean-profit model. The intercept is not part of the joint null.
A small p-value supplies evidence of a joint linear association with Profit under the inference assumptions. It does not prove that all six predictors matter separately or that changing demographics causes profit to change.
The F Statistic Compares Explained Variation with Noise
\(F=(SSR/k)/(SSE/(n-k-1))\). Here \(k=6\) and the denominator degrees of freedom are 103. The pharmacy fit gives \(F\approx53.12\).
In statsmodels, model.ess is explained sum of squares and model.ssr is sum of squared residuals. The course formula calls these SSR and SSE respectively. Read the definitions to avoid confusing the names.
Individual t-Test: Does This Input Help Given the Others?
For social-security recipients, test \(H_0:b_j=0\) against \(H_1:b_j\ne0\). The two-sided test asks whether this partial linear association differs from zero after including the other five inputs.
The statistic is the estimated slope divided by its standard error when the null value is zero. A large p-value does not establish that social-security recipients are irrelevant; overlap with the age profile can make their separate associations hard to distinguish.
Overall F-Test and Individual t-Tests
A large overall F can coexist with small absolute t statistics for some inputs. The six demographics jointly help explain profit, while some separate associations remain imprecise.
In this sample, F≈53.12, while the social-security t statistic is about −0.43. The overall F-test and an individual t-test answer different questions.
This pattern is compatible with multicollinearity, but does not diagnose it by itself. Use predictor relationships and VIF as additional evidence. The individual tests remain conditional on the other included predictors.
If LINE Assumptions Fail: What Changes?
The diagrams are schematic shapes, not observed data or diagnostic test results. SE means standard error; CI means confidence interval; PI means a prediction interval for a new individual outcome. The normality assumption concerns errors conditional on X, not normally distributed predictors or outcomes.
- L — the conditional mean has the specified form. If the true mean bends but the model uses a straight line in the original X, fitted means can systematically miss. OLS still calculates a line, which may be a useful best linear approximation, but its coefficients do not recover the incorrectly assumed mean relationship. Transformations such as X² can model a curved mean while remaining linear in the coefficients. Robust standard errors do not repair a wrong mean form.
- I — errors are independent. Dependence alone need not bias OLS when the design has full rank and the error has zero conditional mean given the full design matrix. However, the usual independent-error SE, t/F tests and intervals may be wrong, and OLS may be inefficient. Use inference appropriate to the dependence, such as suitable clustered or autocorrelation-aware covariance estimates. Use time- or group-respecting validation separately to assess prediction; changing a split does not correct a standard error. In practice, dependence can also accompany a failure of the zero conditional mean condition.
- N — errors are normal. Normality is not required for unbiased OLS coefficients or mean point prediction under the other required conditions. The usual exact small-sample t and F results rely on normal errors together with the other classical assumptions. Large-sample approximate inference can relax normality only with suitable regularity conditions and SE estimates. A large sample does not make the next individual error normal, so a conventional normal-based PI can still have incorrect coverage.
- E — errors have equal conditional variance. Unequal variance alone need not bias OLS when zero conditional mean and full rank hold, but OLS is generally less efficient and the usual homoskedastic SE, t/F tests and CIs can be wrong. Suitable heteroskedasticity-robust SE can support large-sample coefficient inference. They do not remove omitted-variable bias, fix a wrong mean form, or automatically calibrate a PI; a new-outcome interval also needs an appropriate conditional noise variance and distribution.
Choose assumptions for the goal. Predicting the mean mainly requires a useful mean relationship and honest test-set evaluation; N and E are not essential for an OLS point prediction. Coefficient tests and CIs require valid uncertainty estimates. New-outcome PIs require attention to the future error distribution, spread and dependence. Thus no assumption is simply unimportant for every application. Full rank and zero conditional mean are additional requirements, and checking LINE alone establishes neither those requirements nor causation.
Sources: Penn State STAT 501: LINE assumptions and effects of violations · Penn State STAT 501: confidence intervals and prediction intervals · statsmodels: robust covariance and statistical tools
Predict Profit with Every Required Input
The final row is the proposed Kansas City store. Supply all six demographic inputs in the same column order as the fitted design. Add the intercept column explicitly for this single new row.
The mean-response confidence interval concerns average annual profit for comparable demographic profiles. The wider prediction interval concerns one store’s annual profit. The proposal has no observed Profit, so it cannot be included in fit or holdout accuracy scores.
In-Class Practice: A Controlled Demographic Comparison
Start with the proposed city’s inputs. Predict with the full model, then increase Disposable Income by US$1,000 while keeping every other input unchanged. Predict the difference before running. Does it equal 1,000 times that input’s fitted slope?
Section 7 Practice — Multiple Linear Regression and Multicollinearity
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Count usable cities
Warm-up. Print the number of raw rows, observed-profit cities and residual degrees of freedom.
Write your answer, then run it.
2. Read a partial slope
Warm-up. Print the disposable-income slope and the fitted profit difference for US$1,000 higher disposable income, holding the other inputs fixed.
Write your answer, then run it.
3. Predict the proposal
Warm-up. Supply the six proposed-city inputs and print its full-model predicted annual Profit.
Write your answer, then run it.
4. Reconstruct adjusted R-squared
Build your skills. Reconstruct adjusted R-squared from SSE, SST, n and the six predictors; compare with statsmodels.
Write your answer, then run it.
5. Read regression RMSE
Build your skills. Calculate course RMSE s in annual US dollars using the correct degrees of freedom.
Write your answer, then run it.
6. Inspect predictor dependence
Build your skills. Print the correlation between social-security recipients and the age-65+ share.
Write your answer, then run it.
7. Calculate an auxiliary VIF
Build your skills. Regress social-security recipients on the other five demographics and calculate its VIF.
Write your answer, then run it.
8. Read joint significance
Challenge. Print the overall F statistic and its p-value.
Write your answer, then run it.
9. Read individual uncertainty
Challenge. Print the social-security t statistic, p-value and coefficient confidence interval.
Write your answer, then run it.
10. Recognise perfect dependence
Challenge. Create a predictor equal to twice Income. Print the matrix rank and number of columns for the intercept plus these two income columns.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Count usable cities
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
print(len(raw), len(observed), int(model.df_resid))Expected output
111 110 103The file includes one proposal with no Profit; it is excluded from the 110-row fit.
2. Read a partial slope
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
print(model.params["Disposable Income"])
print(model.params["Disposable Income"] * 1000)Expected output
2.535033685877819
2535.0336858778187The slope has units of annual profit dollars per income dollar.
3. Predict the proposal
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
new = raw.loc[raw["Profit"].isna(), features].copy()
new["const"] = 1.0
new = new[["const"] + features]
print(model.predict(new).iloc[0])Expected output
185509.19914483736The missing proposed outcome is not used in model estimation.
4. Reconstruct adjusted R-squared
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
n, k = len(observed), len(features)
sse = (model.resid ** 2).sum()
sst = ((observed["Profit"] - observed["Profit"].mean()) ** 2).sum()
print(1 - (sse / (n - k - 1)) / (sst / (n - 1)))
print(model.rsquared_adj)Expected output
0.7415425112215834
0.7415425112215834There are six predictors and one fitted intercept.
5. Read regression RMSE
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
n, k = len(observed), len(features)
print(((model.resid ** 2).sum() / (n - k - 1)) ** 0.5)Expected output
13547.405851410773The denominator is 103; the unit is the Profit unit.
6. Inspect predictor dependence
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
print(observed["Soc Security (per 1,000)"].corr(observed["% 65 or Older"]))Expected output
0.9380039475543935This is dependence among two predictors, not their correlations with Profit.
7. Calculate an auxiliary VIF
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
name = "Soc Security (per 1,000)"
others = [column for column in features if column != name]
auxiliary = sm.OLS(observed[name], sm.add_constant(observed[others])).fit()
print(1 / (1 - auxiliary.rsquared))Expected output
10.03817284743602Profit is excluded from this auxiliary regression.
8. Read joint significance
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
print(model.fvalue)
print(model.f_pvalue)Expected output
53.12213306024511
2.4060224708208015e-29The joint null sets all six slopes to zero.
9. Read individual uncertainty
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
name = "Soc Security (per 1,000)"
print(model.tvalues[name], model.pvalues[name])
print(model.conf_int().loc[name])Expected output
-0.431131118541678 0.6672739996214572
0   -266.097397
1    171.065013
Name: Soc Security (per 1,000), dtype: float64The coefficient is conditional on the other five demographics; a large p-value can reflect imprecision.
10. Recognise perfect dependence
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
import numpy as np
observed["IncomeTwice"] = 2 * observed["Income"]
design = sm.add_constant(observed[["Income", "IncomeTwice"]])
print(np.linalg.matrix_rank(design), design.shape[1])Expected output
2 3Rank two for three columns means the two income slopes are not uniquely identifiable.
Test-Set Accuracy and Honest Prediction Scope
Evaluate frozen training fits on later data and identify the information each prediction requires.
Predict the Reserved Test Dates
Use the training model to predict the later test rows. Do not fit another model on the test data before assessing the original model. The matching const/SPY design is required.
These are conditional predictions given realised same-day market returns. A later test period checks whether the fitted relationship transfers; it does not make the unknown future market return available in advance.
Animated Evaluation: Fit, Freeze, Predict, Check
Step through a small holdout demonstration: train on weeks 1–6 and test on weeks 7–8. Keep the fitted coefficients frozen while later outcomes are revealed. Assume the test Ads inputs are supplied.
This visual uses a six/two split of the eight-week example retail table so the sequence is visible. The finance example still uses its chronological 80/20 split. Test predictions require available or supplied Ads inputs. Do not use test outcomes to refit or select this model; two test records are too few for a reliable performance assessment.
No. That would let the held-out answers influence the fitted model and spoil this test.
RMSE Measures Residual Variation
In ISOM2600, RMSE means residual standard error \(s\), an estimate of the underlying noise standard deviation. For SLR, \(s=\sqrt{\frac{1}{n-2}\sum_{i=1}^{n}(y_i-\hat y_i)^2}\). For MLR, replace \(n-2\) by \(n-k-1\). Here \(n\) is the sample size used to fit the model, and \(k\) excludes the intercept.
Test R-Squared Can Be Negative
The conventional test R² compares test SSE with deviations from the test sample mean. A negative value means the predictions perform worse than that test-mean reference. The test mean is a retrospective denominator, not a forecast available before the test period.
\[R^2_{test}=1-\frac{\sum_{test}(y_i-\hat y_i)^2}{\sum_{test}(y_i-\bar y_{test})^2}.\]
Render Actual versus Predicted Test Returns
The diagonal represents perfect prediction. Distance from it is prediction error. A narrow range of predictions beside a wide range of actual returns shows remaining uncertainty.
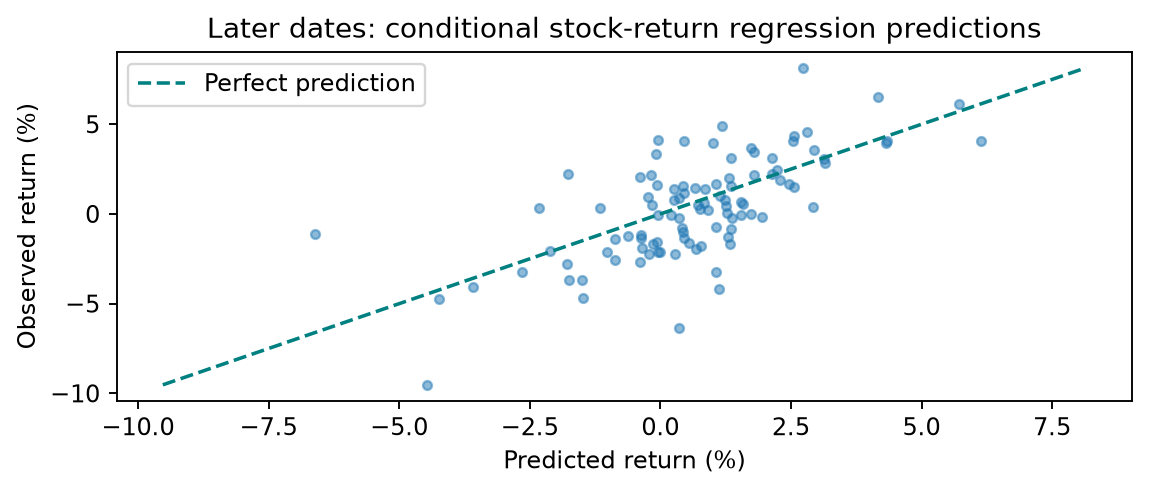
Read Training and Test Performance Carefully
Compare adjusted R² (higher is better) and RMSE (lower is better) on training and test records. Keep the training coefficients fixed when predicting the test set.
\[\text{Adjusted }R^2=1-\frac{SSE/(n-k-1)}{SST/(n-1)},\qquad RMSE=\sqrt{\frac{SSE}{n-k-1}}.\]
Calculate \(SSE\), \(SST\) and \(n\) separately for each set; \(k\) is the number of predictors excluding the intercept (here \(k=1\)). \(SST\) uses that set’s own mean. RMSE below is in percentage points of daily return.
Strong training scores but weaker test scores can suggest overfitting, a changed relationship or a difficult test period. Weak scores on both sets can indicate an inadequate model or substantial noise. There is no universal safe gap.
The course applies the displayed degree-of-freedom-adjusted formulas separately to the training and test records. For this simple linear regression k=1, so both RMSE denominators are n−2, using the relevant sample size. The test coefficients are never refitted. Test adjusted R-squared here is a descriptive out-of-sample score calculated explicitly from frozen predictions; it is not model.rsquared_adj from an OLS fit to the test outcomes. Require n>k+1 and nonzero SST. Different sample outcome variation affects adjusted R-squared, so compare both metrics and the business context.
Underfitting and Overfitting
Underfitting: the model is too simple to capture important patterns in the data.
| Underfitting | Useful fit | Overfitting |
|---|---|---|
| Misses important patterns | Captures the repeatable pattern | Fits sample-specific noise too closely |
| Usually poor on both training and new test records | Performs reasonably on new records | Excellent training fit can deteriorate on new records |
A straight line can underfit a curved relationship. Test performance being better than training performance does not define underfitting. Choose complexity using validation; reserve an untouched test set for final evaluation.
Underfitting concerns a model that misses important structure, not just any model with few predictors. For example, a flat prediction misses a rising mean, and a straight line can miss a curved mean. Such a model typically makes substantial errors on both training and new records. It may still outperform an overfitted model on validation data, but that comparison is not the definition of underfitting. Better test scores than training scores can result from sampling variation, a less noisy test period or different outcome variation; they do not diagnose underfitting. Weak scores on both sets can also reflect substantial noise or limited signal, so inspect the pattern rather than diagnosing from two numbers alone. This is a bias–variance intuition, not a rule that every training/test gap proves overfitting. Use training to fit, validation to select, and an untouched test set for final evaluation.
Interactive Complexity: Better Training Fit, Worse New Predictions
Compare three models on the same constructed data. Circles are training records; crosses are held-out validation records. Here the true mean is a straight line. The flexible curve uses powers of X only to illustrate overfitting; learning polynomial syntax is not required.
Seed 42 fixes two independently generated noise samples around 5 + 2X. All three fits use only 12 training records. The validation sample has 36 records. Even adjusted R² can prefer the flexible fit in this small example while validation adjusted R² falls and validation RMSE rises; it is not a substitute for held-out evaluation. These validation records help compare models and therefore are not an untouched final test.
In-Class Practice: Write a Supported Recommendation
Report training and test adjusted R-squared and RMSE for the frozen training model. Interpret both metrics and state what same-day SPY input the model requires.
Section 8 Practice — Test-Set Accuracy and Honest Prediction Scope
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Recognise overfitting
Warm-up. A simpler model has training RMSE s=0.4 and validation RMSE s=0.6; a flexible model has training RMSE s=0.2 and validation RMSE s=0.9. Print which model validation RMSE favours and explain why.
Write your answer, then run it.
2. Predict test rows
Warm-up. Print the first three test predictions.
Write your answer, then run it.
3. Read prediction errors
Warm-up. Print the first three test errors, observed minus predicted.
Write your answer, then run it.
4. Calculate test R-squared
Build your skills. Print test R-squared.
Write your answer, then run it.
5. Read prediction scope
Build your skills. Print why this stock-return regression test is conditional rather than a standalone forecast before market close.
Write your answer, then run it.
6. Compare training and test fit
Build your skills. Print training and test adjusted R-squared, then training and test RMSE in percentage points, using the course n-k-1 formula. Keep the training model fixed and round to four decimals.
Write your answer, then run it.
7. Check time separation
Build your skills. Print whether the last training date precedes the first test date.
Write your answer, then run it.
8. Check the fitted sample
Challenge. Print model.nobs and the number of training rows.
Write your answer, then run it.
9. Reconstruct RMSE s
Challenge. Calculate fitted stock-return regression RMSE s using n-2 and compare it with model.mse_resid.
Write your answer, then run it.
10. Interpret negative test R-squared
Challenge. If test R-squared is -0.2, print its interpretation.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Recognise overfitting
simple_validation, flexible_validation = 0.6, 0.9
print(simple_validation < flexible_validation)
print(
    "Validation favours the simple model. The flexible model fits training more closely but predicts held-out records worse."
)Expected output
True
Validation favours the simple model. The flexible model fits training more closely but predicts held-out records worse.These constructed values illustrate overfitting; validation is used for choice and a separate final test is still needed.
2. Predict test rows
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
p = model.predict(sm.add_constant(test[["SPY"]]))
print(p.head(3).round(5))Expected output
Date
2024-08-08    0.05727
2024-08-09    0.01364
2024-08-12    0.00458
dtype: float64Coefficients remain fitted on training rows.
3. Read prediction errors
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
p = model.predict(sm.add_constant(test[["SPY"]]))
print((test["NVDA"] - p).head(3).round(5))Expected output
Date
2024-08-08    0.00400
2024-08-09   -0.01574
2024-08-12    0.03618
dtype: float64One observation can differ from its fitted mean.
4. Calculate test R-squared
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
p = model.predict(sm.add_constant(test[["SPY"]]))
y = test["NVDA"]
print(round(1 - ((y - p) ** 2).sum() / ((y - y.mean()) ** 2).sum(), 4))Expected output
0.4387The denominator uses test outcomes around their own mean for retrospective scoring.
5. Read prediction scope
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(
    "The test uses realised market returns. A future prediction needs supplied or forecast market inputs."
)Expected output
The test uses realised market returns. A future prediction needs supplied or forecast market inputs.Known coefficients do not make future inputs known.
6. Compare training and test fit
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
import numpy as np
p = model.predict(sm.add_constant(test[["SPY"]]))
y = test["NVDA"]
n, k = len(test), 1
sse = ((y - p) ** 2).sum()
sst = ((y - y.mean()) ** 2).sum()
adj_test = 1 - (sse / (n - k - 1)) / (sst / (n - 1))
rmse_test = np.sqrt(sse / (n - k - 1))
print(round(model.rsquared_adj, 4), round(adj_test, 4))
print(round(np.sqrt(model.mse_resid) * 100, 4), round(rmse_test * 100, 4))Expected output
0.3295 0.433
2.6693 2.1504Higher adjusted R-squared and lower RMSE indicate better scores. Use the sample size of each set, with k=1, and never refit the test outcomes.
7. Check time separation
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(train.index.max() < test.index.min())Expected output
TrueChronological separation prevents future rows entering this fitted model.
8. Check the fitted sample
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(int(model.nobs), len(train))Expected output
400 400The model must only use training outcomes.
9. Reconstruct RMSE s
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
import numpy as np
n = len(train)
sse = (model.resid ** 2).sum()
print(round(np.sqrt(sse / (n - 2)), 6))
print(round(np.sqrt(model.mse_resid), 6))Expected output
0.026693
0.026693RMSE and residual standard error are the same s in this course.
10. Interpret negative test R-squared
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(
    "The predictions have larger squared error than the retrospective test-mean reference. The test mean was not an available forecast."
)Expected output
The predictions have larger squared error than the retrospective test-mean reference. The test mean was not an available forecast.A training OLS fit with an intercept does not guarantee nonnegative test R-squared.
Extension: Pharmacy Profit and Model Comparison
Compare demographic models on identical cities, select with training and validation, and evaluate the frozen choice once on held-out cities.
One Predictor or Six Demographic Inputs?
Could Income alone predict annual pharmacy profit well enough, or do the other demographics add useful information? Use the original 110 observed-profit cities. Shuffle once with a fixed random seed, then allocate 60% to training, 20% to validation and 20% to the final test.
These are cross-sectional cities, so random allocation is appropriate for this exercise. random_state=42 reproduces the allocation. The 66, 22 and 22 cities are disjoint. The proposed Kansas City row has no observed Profit and is kept outside all three sets.
Fit the Six-Predictor Pharmacy Model
Fit only the 66 training cities. Keep an intercept and all six demographic columns. The validation and test profits do not enter estimation.
This training-only fit has different coefficients from Section 3.7’s all-observed-city explanatory fit. Different estimation samples produce different estimates; neither output should be substituted silently for the other.
Compare Models on Identical Validation Cities
Fit Income-only and six-predictor models on the same training cities. Evaluate both on the same 22 validation cities. The model with the better training fit need not have the better validation score.
The course comparison uses validation adjusted R² and RMSE s with n−k−1, where n is the number of validation cities and k is the candidate’s predictor count. Profit stays in US dollars. This is distinct from the unadjusted square root of average squared prediction errors.
Plot Coefficient Intervals for Stated Input Differences
Raw slopes have different units. Instead of comparing them as if the inputs shared a scale, specify the input difference: US$1,000 income, one birth per 1,000, ten recipients per 1,000, ten CV deaths per 100,000, or one percentage point aged 65+.
These are conventional coefficient intervals conditional on the regression assumptions, not confidence intervals for causal interventions. Multiplying by a stated positive input difference converts both the slope and its confidence limits into annual Profit dollars.
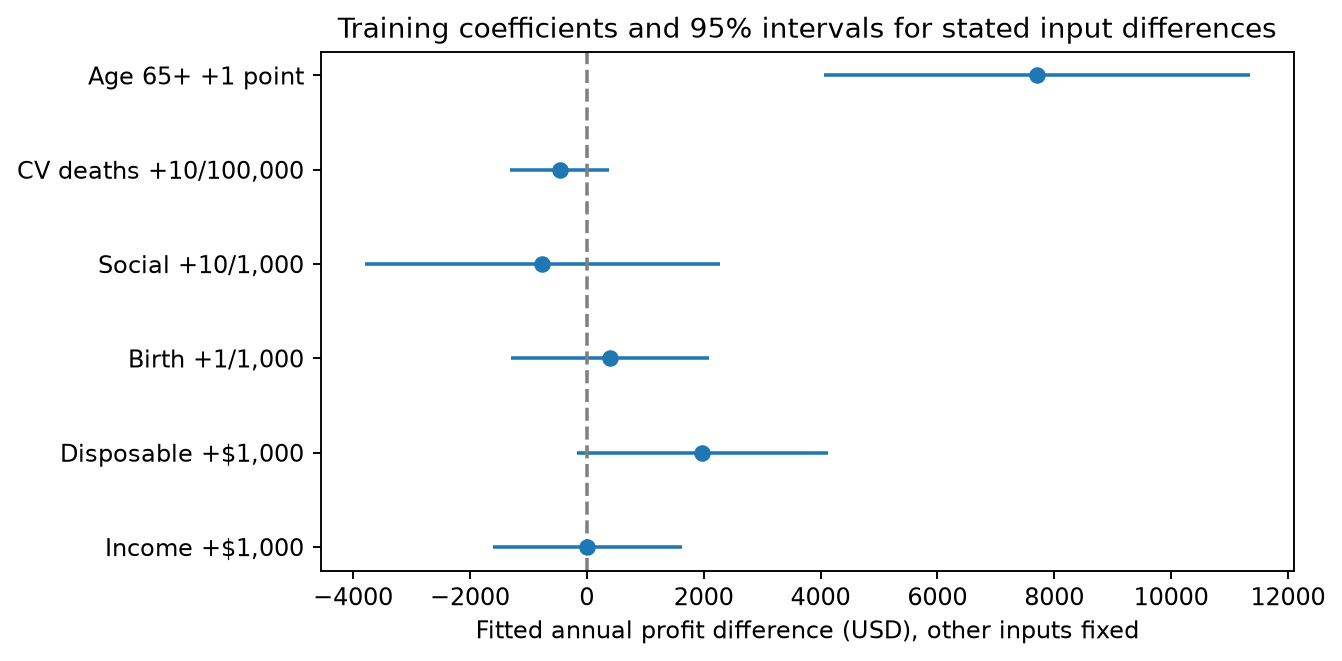
Check Dependence in the Training Design
Measure predictor dependence using only the training cities. Each VIF regresses one demographic input on the other five. Do not include Profit or use the held-out cities to fit these auxiliary models.
Model Search Uses Training and Validation
Training: 66 cities → estimate candidate coefficients.
Validation: 22 cities → compare candidates and choose the predictor list.
Final test: 22 cities → evaluate the frozen choice once.
The Kansas City proposal has no observed profit and is not an accuracy check.
Keep the allocation fixed while comparing models. Do not choose variables repeatedly after seeing final-test results. Section 3.7 used the full observed dataset to explain coefficients; this section demonstrates the separate split-and-select procedure explicitly.
Best Subset: Compare Every Candidate Model
There are six possible inputs. Try every nonempty subset: 6 one-input models, 15 two-input models, 20 three-input models, 15 four-input models, 6 five-input models and 1 six-input model: 63 candidates. Every candidate includes an intercept.
Train every candidate on the same 66 cities; rank it using the same 22 validation cities. This small exhaustive search is feasible for six inputs. A smaller validation error can still reflect noise after many comparisons, so keep the final test untouched until the procedure is fixed.
Interactive Best Subset: Compare Validation Scores
Each dot is one candidate fitted on the training cities and scored on validation cities. Select a criterion and inspect the five leading candidates. Disposable + Birth + Age 65+ is preferred here. Income, Disposable, Birth, Social, CV deaths and Age 65+ abbreviate the six source columns.
For the same validation outcomes and the course n−k−1 convention, adjusted R² and RMSE s rank these candidates identically: one rescales the other. Switching the scoring rule changes the units and direction, not the selected model. No final-test outcome is used by this widget.
Run All 63 Pharmacy Subsets
combinations(features, k) produces every k-input list. Fit each model on training data, then store its validation adjusted R² and RMSE s. Sort once to inspect the candidates.
The loop changes the candidate predictor list while the training and validation rows remain fixed. The final test is not accessed. An explicit three-column list is easier to read in later prediction code than copying a fitted output table by hand.
Read Large p-Values Before Proposing a Shorter List
The training-only full fit gives Income the largest individual p-value. Its separate association is imprecise after the other inputs are included. This is a reason to examine alternatives, not proof that Income has no relationship with profit.
The original pharmacy case uses Disposable Income, Birth Rate and the age-65+ share as a shorter candidate. Evaluate such a declared candidate using validation scores. Do not drop every p>0.05 automatically or judge prediction quality solely from significance.
Refit with an Explicit Shorter Predictor List
Write the proposed shorter list explicitly: Disposable Income, Birth Rate and the age-65+ share. Fit it on training cities and compare it with the six-input model on the same validation cities. The final test remains untouched.
The three-input candidate has validation adjusted R²≈0.452 and RMSE s≈US$15,187, versus ≈0.306 and US$17,092 for the full model. The exhaustive search also selects this list. This decision uses validation rather than final-test scores.
A Large p-Value Does Not Prove a Variable Is Useless
A coefficient test measures evidence about a partial association. It does not directly measure held-out accuracy or business relevance. A large p-value can arise from predictor overlap, limited sample size or a small conditional association.
Use the model’s purpose, sensible inputs and validation performance together.
Selecting variables changes the specification and can change the remaining coefficients. Conventional p-values and coefficient intervals for a model chosen through many searches do not automatically account for that search. Interpret them cautiously rather than treating the selected model as if its specification had never been examined.
Evaluate the Frozen Models on Held-Out Cities
The predictor choice is now fixed. Use the 22 test cities to report final held-out performance, without refitting on their profits. Show Income-only, all six inputs and the selected three-input model as a final comparison.
The chosen model remains fitted on the 66 training cities here. Do not use the final-test table to restart variable selection. The data are a historical teaching case, so these scores describe this supplied split rather than guarantee performance for new cities.
Interpret the Pharmacy Holdout Results
On these test cities, the selected three-input model has adjusted R²≈0.810 and RMSE s≈US$15,870. The full model gives ≈0.761 and US$17,782; Income-only gives ≈−0.145 and US$38,910.
The selected model’s test score is better than its validation score. That alone is not a definition of underfitting. Different small samples can have different difficulty.
Underfitting means an overly restrictive model misses useful structure, often performing poorly on both training and unseen data. Overfitting means a model captures training noise and generalises poorly. Neither diagnosis follows automatically from the sign of one train/test score difference.
In-Class Practice: Predict with the Selected Inputs
Predict annual profit for the proposed Kansas City store using the selected three-input training model. Supply disposable income US$22,642, birth rate 14.4 per 1,000 and age-65+ share 11.4%. Then increase the age share by one percentage point while holding the other two inputs fixed.
The proposed row has no observed Profit. A conditional prediction is possible, but an accuracy score is not. This uses the training-only model, so it differs from the original all-110-city selected-model prediction of approximately US$185,819.
Section 9 Practice — Extension: Pharmacy Profit and Model Comparison
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Check the allocation
Warm-up. Print the numbers of training, validation and test cities, and whether all three index sets are disjoint.
Write your answer, then run it.
2. Count candidate subsets
Warm-up. Use combinations to count all nonempty subsets of the six inputs.
Write your answer, then run it.
3. Compare validation scores
Warm-up. Print full-model and selected-model validation adjusted R-squared and course RMSE s in USD.
Write your answer, then run it.
4. Inspect the training p-values
Build your skills. Print the name and p-value of the full model’s largest slope p-value.
Write your answer, then run it.
5. Read the explicit selected list
Build your skills. Print the selected predictor list and its training residual degrees of freedom.
Write your answer, then run it.
6. Rank every candidate
Build your skills. Enumerate all 63 subsets, score validation RMSE s, and print the best predictor list.
Write your answer, then run it.
7. Predict the proposed store
Build your skills. Print the selected training model’s predicted Profit for the supplied Kansas City inputs.
Write your answer, then run it.
8. Calculate test RMSE s
Challenge. Freeze the selected training model and calculate course RMSE s on the 22 test cities.
Write your answer, then run it.
9. Calculate test adjusted R-squared
Challenge. Calculate adjusted R-squared for the selected model’s held-out predictions.
Write your answer, then run it.
10. Compare an input while holding others fixed
Challenge. Print the fitted Profit difference for a one-percentage-point higher age-65+ share under the selected model.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Check the allocation
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
print(len(train), len(validation), len(test))
print(
    not (
        set(train.index) & set(validation.index)
        or set(train.index) & set(test.index)
        or set(validation.index) & set(test.index)
    )
)Expected output
66 22 22
TrueThe fixed cross-sectional allocation is 66/22/22; the proposed row is outside all three sets.
2. Count candidate subsets
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
from itertools import combinations
print(sum(len(list(combinations(features, k))) for k in range(1, 7)))Expected output
63Six possible inputs give 2**6−1=63 nonempty candidates, each with an intercept.
3. Compare validation scores
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
def score(fitted, rows, columns):
    prediction = fitted.predict(sm.add_constant(rows[columns]))
    errors = rows["Profit"] - prediction
    n, k = len(rows), len(columns)
    sse = (errors ** 2).sum()
    sst = ((rows["Profit"] - rows["Profit"].mean()) ** 2).sum()
    adjusted = 1 - (sse / (n - k - 1)) / (sst / (n - 1))
    rmse_s = (sse / (n - k - 1)) ** 0.5
    return adjusted, rmse_s
print(score(full, validation, features))
print(score(reduced, validation, short_features))Expected output
(0.30583892745886343, 17092.43347999681)
(0.45197458688865944, 15187.074372108971)Use the same validation cities and the correct k for each model.
4. Inspect the training p-values
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
slopes = full.pvalues.loc[features]
print(slopes.idxmax(), slopes.max())Expected output
Income 0.9936295235625769The intercept is excluded when identifying a slope. A large p-value is not proof of no relationship.
5. Read the explicit selected list
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
print(short_features)
print(int(reduced.df_resid))Expected output
['Disposable Income', 'Birth Rate (per 1,000)', '% 65 or Older']
62Three predictors plus an intercept leave 66−3−1=62 training residual degrees of freedom.
6. Rank every candidate
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
def score(fitted, rows, columns):
    prediction = fitted.predict(sm.add_constant(rows[columns]))
    errors = rows["Profit"] - prediction
    n, k = len(rows), len(columns)
    sse = (errors ** 2).sum()
    sst = ((rows["Profit"] - rows["Profit"].mean()) ** 2).sum()
    adjusted = 1 - (sse / (n - k - 1)) / (sst / (n - 1))
    rmse_s = (sse / (n - k - 1)) ** 0.5
    return adjusted, rmse_s
from itertools import combinations
rows = []
for k in range(1, len(features) + 1):
    for subset in combinations(features, k):
        columns = list(subset)
        fitted = sm.OLS(train["Profit"], sm.add_constant(train[columns])).fit()
        adjusted, rmse_s = score(fitted, validation, columns)
        rows.append({"columns": columns, "k": k,
                     "Validation_adj_R2": adjusted,
                     "Validation_RMSE_s_USD": rmse_s})
results = pd.DataFrame(rows)
best = results.sort_values("Validation_RMSE_s_USD").iloc[0]
print(best["columns"])Expected output
['Disposable Income', 'Birth Rate (per 1,000)', '% 65 or Older']The validation ranking selects Disposable Income, Birth Rate and the age-65+ share without using final-test profits.
7. Predict the proposed store
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
new = pd.DataFrame(
    {
        "const": [1.0],
        "Disposable Income": [22642],
        "Birth Rate (per 1,000)": [14.4],
        "% 65 or Older": [11.4],
    }
)
print(reduced.predict(new).iloc[0])Expected output
184278.61459528247The supplied demographics allow a conditional prediction even though Profit is missing for this proposed store.
8. Calculate test RMSE s
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
prediction = reduced.predict(sm.add_constant(test[short_features]))
errors = test["Profit"] - prediction
n, k = len(test), len(short_features)
print(((errors ** 2).sum() / (n - k - 1)) ** 0.5)Expected output
15869.873570210166Use test outcomes only for this final evaluation, not to refit coefficients.
9. Calculate test adjusted R-squared
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
prediction = reduced.predict(sm.add_constant(test[short_features]))
sse = ((test["Profit"] - prediction) ** 2).sum()
sst = ((test["Profit"] - test["Profit"].mean()) ** 2).sum()
n, k = len(test), len(short_features)
print(1 - (sse / (n - k - 1)) / (sst / (n - 1)))Expected output
0.8095173911787292The score uses the mean and size of the same 22-city test sample and three predictors.
10. Compare an input while holding others fixed
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
# These are different cities, not a time series.
shuffled = observed.sample(frac=1, random_state=42)
n = len(shuffled)
train = shuffled.iloc[:int(n * 0.6)].copy()
validation = shuffled.iloc[int(n * 0.6):int(n * 0.8)].copy()
test = shuffled.iloc[int(n * 0.8):].copy()
full = sm.OLS(train["Profit"], sm.add_constant(train[features])).fit()
short_features = ["Disposable Income", "Birth Rate (per 1,000)", "% 65 or Older"]
reduced = sm.OLS(train["Profit"], sm.add_constant(train[short_features])).fit()
print(reduced.params["% 65 or Older"])Expected output
5983.114243125648A slope applies to a one-unit increase in its own input unit. Here one unit is one percentage point.
Appendix A — Statistical Foundations
Optional theory background: variables, samples, normal distributions, estimation and testing. High-school algebra is enough.
A.1 — Why We Need Statistics
A delivery company wants to know its average delivery time. Measuring every delivery may be impossible. We use a smaller set of deliveries to learn about the whole group.
Our route: data → sample → estimate → uncertainty → interval → test. No calculus or programming is needed.
A.2 — Variables and Data
A variable is a characteristic that can take different values. Data are the values we actually record.
| Delivery | Time (minutes) | Area | Late? |
|---|---|---|---|
| 001 | 26 | East | No |
| 002 | 34 | West | Yes |
| 003 | 30 | East | No |
Time, Area and Late? are variables. The recorded entries are data. Delivery is an identifier.
A.3 — Numerical and Categorical Variables
| Type | Example | Meaningful calculation |
|---|---|---|
| Numerical | Delivery time: 26, 34, 30 | Mean time |
| Categorical | Area: East, West | Number in each area |
A category coded 1 or 2 is still a label. Averaging area codes does not produce an average location.
If Late? is coded 1 for Yes and 0 for No, what does its mean measure?
The fraction of deliveries that are late. This works because the coding was explicitly defined as a 0/1 indicator.
A.4 — Population: The Whole Group
A population is the complete group we want to understand. Here it is all deliveries made by this company during the target month.
Define the group and time period before calculating. Next month may have a different population.
A.5 — Sample: The Observations We Use
A sample is the set of observations selected from the population. Its size is \(n\).
If we randomly choose 36 deliveries from the target month, \(n=36\). Their average helps us estimate the population average. A sample is one set of observations, not a probability curve.
A.6 — A Large Sample Can Still Be Biased
Suppose we record only deliveries near the warehouse. Their average may be too low for all deliveries. More nearby deliveries do not fix this selection problem.
A simple random sample gives every delivery an equal chance of selection. The formulas below assume independent observations from the same population; a small sampling fraction makes sampling without replacement approximately independent.
The interactive experiments use independent draws from an imagined population. If a finite population is sampled without replacement at a substantial sampling fraction, the standard-error formula needs a finite-population correction. Consecutive delivery times can also be related; randomness and independence are separate issues.
A.7 — Population Parameters and Sample Statistics
| Quantity | Population: usually unknown | Sample: calculated |
|---|---|---|
| Mean | \(\mu\) (mu) | \(\bar{x}\) (x-bar) |
| Standard deviation | \(\sigma\) (sigma) | \(s_x\) |
A parameter describes the population. A statistic is calculated from a sample. Different samples can give different statistics.
A.8 — The Sample Mean
\[ \bar{x}=\frac{x_1+x_2+\cdots+x_n}{n} \]
- \(x_i\): the recorded value for observation \(i\); \(i\) is just a row number.
- \(n\): sample size.
- \(\bar{x}\): add the values and divide by their count.
For 26, 30 and 34 minutes: \(\bar{x}=90/3=30\) minutes.
A.9 — Standard Deviation Measures Spread
Two samples can have the same mean and different spreads. A deviation is \(x_i-\bar{x}\). Squaring prevents positive and negative deviations cancelling.
A.10 — Sample Variance and Standard Deviation
\[ s_x^2=\frac{\sum_{i=1}^{n}(x_i-\bar{x})^2}{n-1},\qquad s_x=\sqrt{s_x^2} \]
The symbol \(\sum\) means “add these terms”. Variance has squared units; SD returns to minutes.
For 26, 30, 34: \(s_x^2=32/2=16\) minutes² and \(s_x=4\) minutes. We use \(n-1\) because the sample was also used to estimate its mean.
A.11 — A Random Variable
Before a delivery is selected, let \(X\) be its delivery time. We do not know its value yet. A random variable assigns a number to an uncertain outcome.
After observing it, we might record \(x=34\). Uppercase \(X\) describes the uncertain quantity; lowercase \(x\) is one realised value.
A.12 — A Probability Distribution
A probability distribution describes which values a random variable can take and how likely they are.
For a continuous quantity, probability is area under a curve over an interval. The entire area is 1, or 100%. Curve height is density, not the probability of exactly one value.
For a continuous delivery-time model, what is the probability of exactly 30.000… minutes?
Zero. A single point has no area. A range such as 29.5 to 30.5 minutes can have positive probability.
A.13 — A Normal Random Variable
\[ X\sim N(\mu,\sigma^2) \]
This means \(X\) follows a normal distribution: a symmetric bell-shaped curve.
- \(\mu\) is its centre (mean).
- \(\sigma>0\) is its standard deviation (spread).
- The second entry, \(\sigma^2\), is variance.
We use \(N(30,6^2)\) as an imagined delivery-time model. Real delivery times need not be normal.
A.14 — Interactive Normal Curve
Move the mean: the bell shifts. Increase SD: the bell spreads and becomes lower. The shaded area within one SD of the mean stays about 68.27%.
Predict the change before moving a slider.
Sources: Further reading
A.15 — Standardise with a Z-Score
\[ Z=\frac{X-\mu}{\sigma}\sim N(0,1) \]
A z-score says how many population SDs a value lies above or below the mean. With \(\mu=30\) and \(\sigma=6\):
- \(x=36\) gives \(z=1\): one SD above the mean.
- \(x=18\) gives \(z=-2\): two SDs below the mean.
About 95% of a normal distribution lies between \(z=-1.96\) and \(z=1.96\).
A.16 — Different Samples Give Different Means
Imagine choosing three deliveries, recording their mean, then starting again with a new sample. The population stays the same, but the selected values change.
A.17 — A Sampling Distribution
Take a sample of size \(n\) → calculate one sample mean → repeat with fresh samples.
The distribution of those means is the sampling distribution of \(\bar{X}\). Each value represents a whole sample, rather than one delivery.
Sources: Further reading
A.18 — Animate Repeated Samples
Click Draw sample or Play / pause. Dots show the current deliveries; the histogram collects one mean per sample. Increase \(n\) and restart: the distribution of means becomes narrower.
Samples are independent normal draws with μ=30 and σ=6. The histogram is a simulation and will not match a smooth curve exactly. Changing n clears the means because a sampling distribution is defined for one fixed sample size.
A.19 — Standard Error of the Mean
\[ SE(\bar{X})=\frac{\sigma}{\sqrt{n}} \]
Standard error (SE) is the SD of a statistic across repeated samples. It measures sampling uncertainty in the estimate.
If \(\sigma=6\): \(n=9\) gives SE=2 minutes; \(n=36\) gives SE=1 minute. Quadrupling the sample size halves the SE.
A.20 — SD and SE Describe Different Things
| Quantity | Variation of what? | In our imagined population |
|---|---|---|
| Population SD \(\sigma\) | Individual delivery times | 6 minutes |
| SE of \(\bar{X}\) | Means across samples of 36 | 1 minute |
A precise estimated average does not mean individual deliveries are all alike.
Does sampling more deliveries make the population SD shrink?
No. It reduces uncertainty in the sample mean. It does not make individual delivery times less variable.
A.21 — When Is the Mean Approximately Normal?
If the population is normal, the mean of independent observations is normal for any \(n\).
For a non-normal population with finite variance, the Central Limit Theorem often makes the mean approximately normal when \(n\) is sufficiently large. Strong skewness or outliers may require much larger samples. There is no universal “\(n=30\) fixes everything” rule.
A.22 — A Confidence Interval for the Mean
One estimate is not enough: add a margin of error on each side. When population SD \(\sigma\) is known and the sample mean is normal or approximately normal:
\[ \text{95% CI for }\mu:\quad \bar{x}\ \pm\ 1.96\frac{\sigma}{\sqrt{n}} \]
“\(\pm\)” means calculate a lower and an upper endpoint.
Sources: Further reading
A.23 — A Confidence Interval in Minutes
For \(n=36\), \(\bar{x}=32\) and known \(\sigma=6\):
\[ SE=6/\sqrt{36}=1,\qquad CI=32\pm1.96=[30.04,33.96] \]
The target is population mean delivery time \(\mu\), not the time of one new delivery.
A.24 — Unknown Population SD: Use Student’s t
Usually \(\sigma\) is unknown. Estimate it by the sample SD \(s_x\). This adds uncertainty, so use a t multiplier:
\[ \bar{x}\ \pm\ t^*\frac{s_x}{\sqrt{n}},\qquad df=n-1 \]
\(t^*\) is a positive cutoff determined by confidence level and degrees of freedom \(df\). For \(n=36\), a 95% t interval uses \(t^*\approx2.030\) instead of 1.96. Exact for independent normal observations; approximate under suitable large-sample conditions.
A.25 — Animate 95% Confidence
Repeat the sampling-and-interval procedure. The vertical line is the fixed population mean; each horizontal interval comes from a new sample.
About 95% of intervals cover the true mean over many repetitions—not necessarily exactly 95 out of every 100.
This simulation uses the known population SD and normal observations, so 1.96 gives approximately 95% coverage. Blue intervals cover μ; orange intervals miss it. The count reflects all samples drawn; only the latest 18 intervals are shown.
A.26 — What 95% Confidence Means
The method captures the true parameter in 95% of repeated samples under its assumptions. After a particular interval is calculated, the fixed parameter is either inside it or outside it.
A 95% CI does not contain 95% of individual deliveries and does not assign a 95% probability to the fixed parameter being in this realised interval.
Sources: Further reading
A.27 — Hypothesis Testing
Question: is population mean delivery time different from 30 minutes?
\[ H_0:\mu=30\qquad H_1:\mu\ne30 \]
- Null hypothesis \(H_0\): the reference claim we test.
- Alternative \(H_1\): the difference we are looking for.
Assume the null and the sampling model, then ask how unusual our sample result would be.
A.28 — The Test Statistic
\[ z_{\mathrm{obs}}=\frac{\bar{x}-\mu_0}{\sigma/\sqrt{n}}=\frac{32-30}{1}=2 \]
- \(\mu_0=30\): the mean specified by the null.
- \(z_{\mathrm{obs}}\): observed distance from the null, measured in SEs.
The sample mean is two SEs above the null mean. We compare it with a standard normal curve under \(H_0\).
A.29 — What a P-Value Means
For a two-sided test, count outcomes at least as far from the null in either direction. For \(z_{\mathrm{obs}}=2\):
\[ p=P(Z\le-2)+P(Z\ge2)\approx0.0455 \]
If \(H_0\) and the model are correct, about 4.55% of repeated samples would give a test statistic at least this extreme. This is not the probability that \(H_0\) is true.
Sources: Further reading
A.30 — Significance and Decisions
Choose significance level \(\alpha_{\mathrm{sig}}\) before inspecting the result. At \(\alpha_{\mathrm{sig}}=0.05\), \(p=0.0455<0.05\), so reject \(H_0\) in this example.
- \(p\le\alpha_{\mathrm{sig}}\): reject the null.
- \(p>\alpha_{\mathrm{sig}}\): do not reject; this does not prove the null.
The significance level is a long-run false-rejection rate under \(H_0\), not the chance our particular conclusion is wrong. A small p-value alone does not show a large business effect.
A.31 — One-Sided and Two-Sided Questions
| Question chosen in advance | Null | Alternative | Count which tail? |
|---|---|---|---|
| Different from 30? | \(\mu=30\) | \(\mu\ne30\) | Both |
| Greater than 30? | \(\mu\le30\) | \(\mu>30\) | Right |
| Less than 30? | \(\mu\ge30\) | \(\mu<30\) | Left |
For one-sided tests, calculate the reference distribution at the boundary \(\mu=30\).
A.32 — Interactive P-Value Tails
Choose the research question, then move the observed z-statistic. The shaded probability is the p-value. At \(z=2\): two-sided \(p\approx0.0455\), greater-than \(p\approx0.0228\), less-than \(p\approx0.9772\).
A.33 — Choose the Direction Before Seeing the Data
Use a one-sided test only when the question was directional before observing the data. Do not switch sides or switch to one-sided testing to obtain a smaller p-value.
With a preselected “less than 30” alternative, a mean far above 30 is not evidence for that alternative. A one-sided p-value is not always half the two-sided one.
A.34 — A Confidence Interval and a Test
For the same two-sided procedure, a 95% CI and a test at 5% agree:
- Null value outside the CI → reject.
- Null value inside the CI → do not reject.
Our CI \([30.04,33.96]\) excludes 30 and our two-sided p-value is 0.0455. They are two ways to describe the same evidence.
Can we compare a 95% two-sided interval with any one-sided test and expect the same decision?
No. The confidence level, sidedness and statistical procedure must match.
A.35 — Statistical Foundations: Check Your Understanding
| Term | What it describes |
|---|---|
| Population / sample | Target group / selected observations |
| Parameter / statistic | Population quantity / calculated estimate |
| SD / SE | Spread of observations / sampling spread of an estimate |
| Confidence interval | Uncertainty about a parameter |
| P-value | Tail probability under the null model |
Next: the same ideas applied to a regression slope and predicted revenue.
Appendix B — Linear Regression Theory
Optional theory background: fitted lines, coefficient uncertainty, confidence intervals and prediction intervals. Read Appendix A first if these terms are new.
B.1 — Regression Uses the Same Statistical Ideas
A sample mean estimates one average. A regression estimates an average at each input value.
In this example, advertising spending \(x\) and weekly revenue \(Y\) are both in HKD thousands. We will fit a line, describe coefficient uncertainty, then distinguish average revenue from one new week.
B.2 — The Population Model
\[ Y=\beta_0+\beta_1x+\varepsilon \]
- \(x\): advertising input.
- \(Y\): uncertain revenue at that input.
- \(\beta_0\): population intercept.
- \(\beta_1\): population slope.
- \(\varepsilon\) (epsilon): individual deviation from the average; \(E(\varepsilon\mid x)=0\).
Thus the population mean is \(E(Y\mid x)=\beta_0+\beta_1x\). “\(\mid x\)” means at the given input \(x\).
B.3 — One Input, Several Possible Outcomes
At the same advertising input, revenue can differ because of weather, customer demand and other unobserved influences.
The straight line describes average revenue, while noise describes the spread around it.
B.4 — The Fitted Line
\[ \hat{y}(x)=\hat{\beta}_0+\hat{\beta}_1x \]
A hat means “estimated from our sample”.
- \(\hat{\beta}_0,\hat{\beta}_1\): estimated intercept and slope.
- \(\hat{y}(x)\): estimated average of \(Y\) at input \(x\).
For this sample, \(\hat y(x)\approx9.6429+2.1905x\). Displayed coefficients are rounded; calculations use full precision. An extra HKD1,000 of Ads is associated with HKD2,190.5 higher fitted revenue. Association alone does not establish causation.
B.5 — Observations and the Fitted Line
Each dot is one observed week. The line supplies a fitted value at that week’s input. The vertical gaps are residuals: observed minus fitted.
B.6 — Residuals and Squared Error
\[ e_i=y_i-\hat y(x_i),\qquad SSE=\sum_{i=1}^{n}e_i^2 \]
- \(e_i\): residual for observed week \(i\).
- \(SSE\): sum of squared residuals; it is never negative.
A residual above the line is positive; below is negative. Squaring stops the signs cancelling. Fitting by ordinary least squares (OLS) means choosing the line with the smallest SSE.
B.7 — Animate the Least-Squares Fit
Move the intercept and slope. Watch the residual segments and SSE change. Click Animate OLS fit to move to the least-squares line.
The minimum is for the total squared error, not for each residual separately.
B.8 — Population Noise and Sample Residuals
\[ \varepsilon_i=y_i-(\beta_0+\beta_1x_i),\qquad e_i=y_i-(\hat\beta_0+\hat\beta_1x_i) \]
The true population line is unknown, so we cannot observe its noise values directly. Residuals use the estimated line. They help us estimate the noise spread and examine assumptions.
B.9 — Assumptions Behind the Formulas
| Assumption | Plain-language meaning |
|---|---|
| Linear mean | The population average follows a straight line |
| Independent errors | One observation’s error does not determine another’s |
| Constant variance | Noise has the same SD \(\sigma\) at every input |
| Normal errors | At a fixed input, errors follow a normal distribution |
These give exact small-sample t tests and intervals. The predictor \(x\) itself need not be normal; \(x\) must vary. Normality concerns errors conditional on \(x\).
Sources: Further reading
B.10 — RMSE Estimates the Noise SD
\[ s=\mathrm{RMSE}=\sqrt{\frac{SSE}{n-2}} \]
This course uses RMSE for the residual standard error. It estimates the unknown noise SD \(\sigma\), in revenue units. We use \(n-2\) because simple linear regression estimates an intercept and a slope.
In our eight-week sample: \(SSE=12.4762\), so \(s=\sqrt{12.4762/6}=1.4420\) HKD thousands.
B.11 — A Slope Also Has a Sampling Distribution
Take a new sample of weeks and refit: the fitted slope changes. The population slope stays fixed.
\(SE(\hat\beta_1)\) estimates the SD of slope estimates across repeated samples. It measures the precision of the estimated slope, not the spread of individual revenues.
B.12 — Standard Error of the Slope
\[ S_{xx}=\sum_{i=1}^{n}(x_i-\bar x)^2,\qquad SE(\hat\beta_1)=\frac{s}{\sqrt{S_{xx}}} \]
- \(S_{xx}\): total squared spread of the observed inputs.
- \(s\): RMSE, the estimated noise SD.
Our sample has \(S_{xx}=42\), so \(SE(\hat\beta_1)=1.4420/\sqrt{42}=0.2225\). Across repeated comparable samples, estimated slopes typically vary around the true slope on a scale of about 0.2225 revenue units per Ads unit.
B.13 — Standard Error of the Intercept
\[ SE(\hat\beta_0)=s\sqrt{\frac1n+\frac{\bar x^2}{S_{xx}}} \]
The intercept is the estimated mean at \(x=0\). If the observed inputs are far from zero, it is harder to estimate reliably.
Here \(n=8\), \(\bar x=4.5\), \(S_{xx}=42\), giving \(SE(\hat\beta_0)=1.1236\). Do not give a business interpretation at zero if zero is outside the meaningful range.
B.14 — A Confidence Interval for a Coefficient
\[ \hat\beta_j\ \pm\ t^*SE(\hat\beta_j),\qquad df=n-2 \]
\(j=0\) means intercept; \(j=1\) means slope. For our sample, \(df=6\) and a 95% interval uses \(t^*=2.4469\).
Slope CI: \(2.1905\pm2.4469(0.2225)=[1.6460,2.7349]\).
This estimates the population slope: the association is roughly HKD1,646 to HKD2,735 per extra HKD1,000 in Ads under the model.
Sources: Further reading
B.15 — A Two-Sided Test for a Coefficient
\[ H_0:\beta_j=0,\qquad H_1:\beta_j\ne0 \]
\[ t_{\mathrm{obs}}=\frac{\hat\beta_j-0}{SE(\hat\beta_j)},\qquad df=n-2 \]
For the slope: \(t=2.1905/0.2225\approx9.8446\), with two-sided \(p\approx0.0000633\). Under a zero population slope and our model assumptions, such a large absolute t-statistic is very rare. Reject at 5%; this alone does not prove causation.
B.16 — Interactive Coefficient Test and Interval
Keep \(df=6\) and adjust the estimated slope or its SE. Compare the two-sided p-value, 95% CI and the null value zero. A larger SE means less precise estimation.
These controls illustrate hypothetical regression outputs; they do not refit the eight observed weeks.
B.17 — A Coefficient CI and Its Test Agree
For a matching two-sided 5% t test and 95% t interval:
- CI excludes zero → coefficient differs significantly from zero.
- CI includes zero → insufficient evidence of a nonzero coefficient.
An interval shows both uncertainty and plausible effect sizes.
B.18 — Multiple Linear Regression
\(Y=b_0+b_1x_1+\cdots+b_kx_k+e\). The pharmacy model predicts annual Profit from six demographic inputs, so k=6. Each fitted slope compares profiles with the other five inputs held fixed. The intercept is estimated but is not counted in k.
The full observed-city case has n=110 and six predictors: Income, Disposable Income, Birth Rate (per 1,000), Soc Security (per 1,000), CV Death (per 100,000) and % 65 or Older. Profit is annual US dollars; Location identifies the city and is excluded from the numerical design. Residual degrees of freedom are n−k−1=103. The final Kansas City row has missing Profit and is a proposed prediction case, not a fitted observation. A two-sided individual t-test asks whether a partial coefficient differs from zero given the other inputs.
B.19 — RMSE and Degrees of Freedom in Multiple Linear Regression
\[ s=\mathrm{RMSE}=\sqrt{\frac{SSE}{n-k-1}},\qquad df=n-k-1 \]
We estimate \(k\) slopes plus one intercept. With \(n=20\) observations and \(k=2\) predictors, \(df=17\).
For coefficient \(j\): CI is \(\hat\beta_j\pm t^*SE(\hat\beta_j)\) and the test uses \((\hat\beta_j-0)/SE(\hat\beta_j)\) with the same df. Software calculates the SEs; the simple-linear-regression slope SE formula does not apply unchanged.
B.20 — Individual t Tests and the Overall F Test
| Test | Null | Alternative |
|---|---|---|
| Individual t | \(\beta_j=0\) | \(\beta_j\ne0\) |
| Overall F | \(\beta_1=\cdots=\beta_k=0\) | At least one slope is nonzero |
An individual t test asks about one predictor with the others included. The overall F test asks whether the predictor set helps explain the mean at all. A significant F test does not say that every coefficient is significant.
Under the classical model, F = (SSR/k)/(SSE/(n-k-1)), with numerator df=k and denominator df=n-k-1; SSR is explained sum of squares. The intercept is not included in the overall null. For simple linear regression, F=t² and the overall p-value equals the two-sided slope-test p-value.
B.21 — A New Input and a Fitted Mean
\[ x_0=4,\qquad\hat y_0=\hat y(4)\approx18.4048 \]
The subscript 0 labels the prediction case; it does not mean \(x_0=0\). Here the input is Ads=HKD4,000.
\(\hat y_0\) estimates average revenue at this input: HKD18,404.8. It is also our point prediction for one new week, but that week has extra uncertainty.
B.22 — Standard Error of the Fitted Mean
\[ SE(\hat y_0)=s\sqrt{\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}} \]
This measures how much our estimated average at \(x_0\) varies across repeated training samples. It is smallest near the average observed input \(\bar x\).
At \(x_0=4\): \(SE(\hat y_0)=0.5218\) HKD thousands. This is smaller than \(s=1.4420\), which measures individual noise.
Sources: Further reading
B.23 — Confidence Interval for Average Revenue
\[ \hat y_0\ \pm\ t^*SE(\hat y_0) \]
For whom? The population average of all comparable weeks with Ads fixed at HKD4,000.
\(18.4048\pm2.4469(0.5218)=[17.1279,19.6816]\) HKD thousands.
This interval measures uncertainty about the mean response, not the variability of one future week.
B.24 — One New Week Has Extra Uncertainty
A prediction for one future week has two sources of uncertainty:
- We estimated the population mean line using a sample.
- The future week has its own unpredictable noise.
A prediction interval includes both, so it is wider than a confidence interval for the average at the same input and confidence level.
B.25 — Prediction Interval for One New Week
\[ SE_{\mathrm{pred}}=s\sqrt{1+\frac1n+\frac{(x_0-\bar x)^2}{S_{xx}}} \]
\[ \text{95% PI}:\quad \hat y_0\ \pm\ t^*SE_{\mathrm{pred}} \]
The extra 1 accounts for the new week’s noise. At \(x_0=4\), the PI is \([14.6524,22.1571]\) HKD thousands. It targets one independent new response at the specified input, under the model assumptions.
B.26 — Interactive Confidence and Prediction Intervals
Move \(x_0\) and change the confidence level. Compare the narrow mean CI with the wider individual PI. Both widen away from \(\bar x=4.5\).
Click Animate new weeks: dots vary around the fitted mean. This is a teaching simulation treating the fitted line and RMSE as the generating model.
Intervals are calculated from the same eight-week data using n−2 degrees of freedom. Animated new outcomes are illustrative normal draws using the fitted line and estimated noise SD; they are not observed business data or a validation of interval coverage. The inputs outside the observed range [1,8] are marked as extrapolation.
B.27 — Three Different Interval Targets
| Interval | Target | Units |
|---|---|---|
| Coefficient CI | A population slope or intercept | Coefficient units |
| Fitted mean CI | Average revenue at given \(x_0\) | Revenue units |
| Prediction interval | One new week’s revenue at \(x_0\) | Revenue units |
All three involve estimation uncertainty. Only the prediction interval adds the new observation’s individual noise.
B.28 — What the Intervals Cannot Fix
Intervals rely on the regression model and sampling assumptions. They do not repair a biased sample, a curved mean fitted as a straight line, dependent errors, or a changed business relationship.
Extrapolation: predicting outside the observed input range can fail even when the displayed formula produces a narrow-looking interval.
More data can reduce estimation uncertainty; it does not eliminate individual noise.
B.29 — Regression Theory: Check Your Understanding
- The fitted line estimates the average of \(Y\) at an input.
- OLS chooses coefficients that minimise SSE.
- RMSE \(s\) estimates underlying noise SD.
- Coefficient SEs, CIs and t tests describe estimation uncertainty.
- A mean CI concerns an average; a PI concerns one new outcome.
Return to Sections 2, 4 and 5 to connect these ideas with the Python results.
Chapter Summary
| Task | Python pattern | Interpretation check |
|---|---|---|
| Inspect association | .corr(), scatterplot |
Pair rows, inspect curvature; zero r does not rule out association |
| Fit a line | sm.OLS(y, sm.add_constant(X)).fit() |
Intercept, slope, residual |
| Quantify coefficient uncertainty | .bse, .pvalues, .conf_int() |
Specify null and assumptions |
| Predict | .predict(), .get_prediction() |
Mean CI versus individual PI |
| Diagnose | .resid, .get_influence() |
LINE, leverage, influence |
| Add predictors | Multiple-column X, VIF | Holding others fixed; dependence |
| Evaluate later records | Test adjusted R² and RMSE | Frozen fit, known inputs |
| Compare models | Adjusted R² and RMSE | Same outcome and rows; preserve final test |
Before recommending a decision: state the outcome, units, observation period, prediction inputs, error measure, uncertainty, and limitations.
Quiz Review
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
Question 1
Print the correlation between LocationOffset and TravelCost. Compare it with correlation between squared LocationOffset and TravelCost. Explain whether the first result justifies ignoring location.
Write your answer, then run it.
Question 2
Fit Revenue on Ads with an intercept and print coefficients.
Write your answer, then run it.
Question 3
Print the first week’s observed, fitted, and residual revenues.
Write your answer, then run it.
Question 4
Print the SPY slope and its 95% confidence interval for NVDA return.
Write your answer, then run it.
Question 5
Test whether the SPY slope equals 1 against a two-sided alternative. Print its p-value.
Write your answer, then run it.
Question 6
At retail Ads=5, print a mean CI and individual PI.
Write your answer, then run it.
Question 7
Print the retail record with the largest absolute residual.
Write your answer, then run it.
Question 8
For the full pharmacy model, print the fitted annual-profit difference for US$1,000 higher disposable income while holding the other five inputs fixed.
Write your answer, then run it.
Question 9
For the retail SLR, print SST, SSR, SSE, R-squared and regression RMSE using n-2; state one limitation of using training fit to select predictors.
Write your answer, then run it.
Question 10
Predict NVDA returns, as percentages, for supplied SPY returns of -1% and +1%. State the required prediction input.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
Question 1
import pandas as pd
visits = pd.DataFrame({"LocationOffset": [-3, -2, -1, 0, 1, 2, 3]})
visits["TravelCost"] = 5 + visits["LocationOffset"] ** 2
print(round(visits["LocationOffset"].corr(visits["TravelCost"]), 3))
print(round((visits["LocationOffset"] ** 2).corr(visits["TravelCost"]), 3))
print(
    "Location matters through a U-shaped cost relationship even though its Pearson correlation is zero."
)Expected output
0.0
1.0
Location matters through a U-shaped cost relationship even though its Pearson correlation is zero.A single correlation summarises linear association and can miss a curved relationship.
Question 2
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(model.params.round(3))Expected output
const    9.643
Ads      2.190
dtype: float64The intercept is explicitly included.
Question 3
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(
    round(sales.loc[0, "Revenue"], 3),
    round(model.fittedvalues.loc[0], 3),
    round(model.resid.loc[0], 3),
)Expected output
12 11.833 0.167Residual is observed minus fitted.
Question 4
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
print(model.params["SPY"])
print(model.conf_int().loc["SPY"])Expected output
2.3320290464037203
0    2.005432
1    2.658626
Name: SPY, dtype: float64The slope describes a change in fitted NVDA return for a change in SPY return.
Question 5
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
from scipy import stats
t_stat = (model.params["SPY"] - 1) / model.bse["SPY"]
print(2 * stats.t.sf(abs(t_stat), model.df_resid))Expected output
1.208846915869949e-14Subtract the null slope of 1 and count both tails.
Question 6
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
new = pd.DataFrame({"const": [1], "Ads": [5]})
p = model.get_prediction(new).summary_frame()
print(p[["mean_ci_lower", "mean_ci_upper", "obs_ci_lower", "obs_ci_upper"]].round(3))Expected output
   mean_ci_lower  mean_ci_upper  obs_ci_lower  obs_ci_upper
0 19.318 21.872 16.843 24.348The individual interval includes additional outcome variation.
Question 7
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
print(sales.loc[model.resid.abs().idxmax()])Expected output
Ads         3
Revenue    14
Price      10
Name: 2, dtype: int64Investigate context before excluding an observation.
Question 8
import pandas as pd
import statsmodels.api as sm
raw = pd.read_csv("https://busanalytics-book.pages.dev/data/profit.csv")
features = [
    "Income", "Disposable Income", "Birth Rate (per 1,000)",
    "Soc Security (per 1,000)", "CV Death (per 100,000)", "% 65 or Older"
]
# The proposed Kansas City location has no observed Profit.
observed = raw.dropna(subset=["Profit"]).copy()
X = sm.add_constant(observed[features])
model = sm.OLS(observed["Profit"], X).fit()
print(model.params["Disposable Income"] * 1000)Expected output
2535.0336858778187The partial slope multiplied by 1,000 gives the fitted annual Profit-dollar difference. This is conditional association rather than a causal claim.
Question 9
import pandas as pd
sales = pd.DataFrame({
    "Ads": [1, 2, 3, 4, 5, 6, 7, 8],
    "Revenue": [12, 15, 14, 20, 19, 24, 25, 27],
    "Price": [9, 8, 10, 7, 9, 6, 7, 6]
})
import statsmodels.api as sm
X = sm.add_constant(sales[["Ads"]])
model = sm.OLS(sales["Revenue"], X).fit()
import numpy as np

y = sales["Revenue"]
sst = ((y - y.mean()) ** 2).sum()
ssr = ((model.fittedvalues - y.mean()) ** 2).sum()
sse = (model.resid**2).sum()
print(round(sst, 3), round(ssr, 3), round(sse, 3))
print(round(1 - sse / sst, 4), round(np.sqrt(sse / (len(y) - 2)), 3))
print(
    "Extra predictors can improve training fit while worsening prediction on new records."
)Expected output
214.0 201.524 12.476
0.9417 1.442
Extra predictors can improve training fit while worsening prediction on new records.The decomposition uses OLS with an intercept. Held-out error is needed to judge transfer to new records.
Question 10
import pandas as pd
prices = pd.read_csv(
    "https://busanalytics-book.pages.dev/data/nvda_spy_daily_2023_2024.csv",
    index_col="Date", parse_dates=True).sort_index()
data = prices[["SPY", "NVDA"]].pct_change().dropna()
cut = int(len(data) * 0.8)
train = data.iloc[:cut].copy()
test = data.iloc[cut:].copy()
import statsmodels.api as sm
X = sm.add_constant(train[["SPY"]])
Y = train["NVDA"]
model = sm.OLS(Y, X).fit()
new = pd.DataFrame({"const": [1, 1], "SPY": [-0.01, 0.01]})
print(model.predict(new) * 100)
print("The SPY return must be supplied for each scenario.")Expected output
0   -1.996343
1    2.667715
dtype: float64
The SPY return must be supplied for each scenario.The model gives a conditional stock-return prediction, given the SPY return.