Chapter 2 — Working with DataFrames in Pandas
What This Chapter Covers
A DataFrame holds a business table. We will select records, handle missing data, create business measures, explore patterns, and calculate rolling and cumulative results.
This chapter follows the Fall 2026 syllabus: missing data, data slicing, feature engineering, exploratory data analysis, and rolling and cumulative methods. You should be able to read existing Python code, explain its output, and connect a calculation to a business question. The larger group project will be a separate Colab notebook.
Chapter Roadmap
| Section | Business task |
|---|---|
| 1 | Read a table and its columns |
| 2 | Select relevant records |
| 3 | Handle incomplete information |
| 4 | Create measures, sort results, and read method chains |
| 5 | Count categories and describe distributions and relationships |
| 6 | Compare groups and choose charts |
| 7 | Organise dates and measure changes |
| 8 | Follow recent trends and accumulated results |
Our Retail Orders
A small gift retailer wants to understand its first week of November orders in Central and Kowloon. One row is one order line. Quantity is recorded in units; UnitPrice and UnitCost are HKD per unit. These are classroom records, not a sample used to make claims about a named company.
The eight records are deliberately small enough to check by hand. A recorded quantity of zero is retained as a zero-sales record. Later missing-data examples deliberately remove a few entries to illustrate incomplete information. We derive daily sales from the same order table before introducing time-series methods. Each Python box includes its own input data, so you can visit the lessons in any order.
Read O101: 2 units sold at HK$120 per unit, with product cost HK$70 per unit. Predict its revenue before running a calculation.
DataFrames and the First Look
Identify what a row represents, load a table, and inspect its structure before analysing it.
Cross-sectional Data versus Time Series
First ask: what does one row represent?
| Cross-sectional data | Time-series data | |
|---|---|---|
| Compare | Different entities in the same period | The same entity or measure over time |
| Example | One row per customer this month | One row per day of a store’s sales |
| Row order | Usually no natural time sequence | Chronological order matters |
| Missing values | Consider comparable entities and the variable’s distribution | Respect time and what was known then |
| Train/test split | Random split can suit independent entities | For forecasting: earlier train, later test |
Our order-line table contains transactions. Aggregating sales by day creates a time series.
An entity is the person, store, product, or other unit being studied. Cross-sectional observations refer to a common point or period; time-series observations repeatedly measure a unit or aggregate through time. Multiple stores repeatedly observed over time form panel data, combining entity and time structure. A date column alone does not make arbitrary rows a single time series. Random splitting is not justified merely because a table looks cross-sectional: related records, repeated customers, and the intended prediction target matter.
Cross-sectional rows compare entities, while time-series rows follow a unit or measure through time. This changes which observations provide a defensible fill and which observations can be used for training without revealing future information.
A Column Is a Series
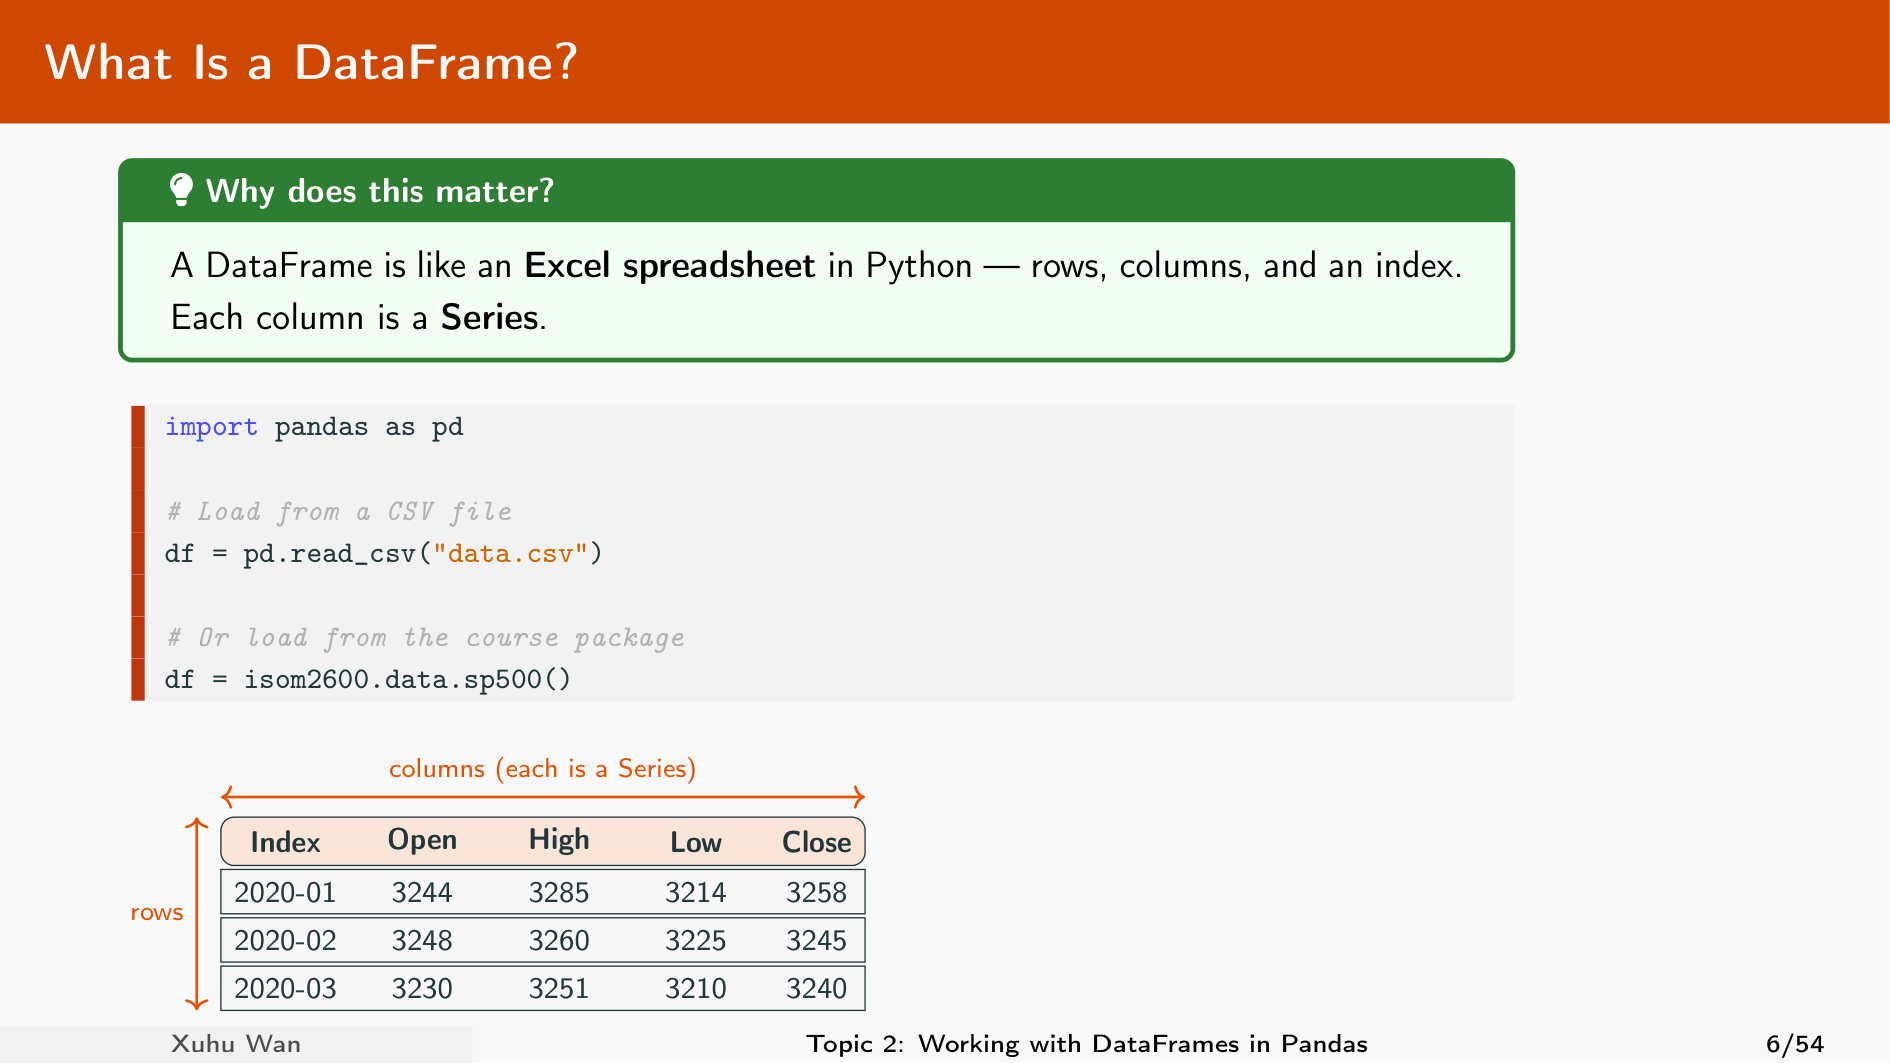
A Series is one labelled variable. A DataFrame places related Series in columns and gives them a shared row index.
A Series with the DataFrame’s row labels.
Rows, Columns, and the Index
Read across a row for one observation. Read down a column for one variable. Index labels identify rows; numerical positions count from 0.
In the original financial diagram, each row is a dated observation and each column is an Open, High, Low, or Close value. In our retail table, each row is an order line. The label O101 identifies an order line, while position 0 identifies the first displayed row. A label can be text, a number, or a date.
Create a Small DataFrame
pd.DataFrame({...}) uses dictionary keys as column names and lists as column values. Supply an index= when meaningful row labels are available.
Change one price, then run the box again. Check which cell changes.
Load a CSV File
A CSV stores a table as text separated by commas. pd.read_csv() returns a DataFrame. The first line normally supplies column names.
The file contains the eight classroom records shown in the briefing. The named OrderID column becomes the index because we pass index_col=“OrderID”. In Colab, the same function can read an uploaded local filename. The browser examples use an HTTPS link. Installing a library and loading a CSV are different operations: read_csv reads data; it does not install pandas.
DataFrame Attributes
Attributes describe the table and have no parentheses. .shape is (rows, columns); .columns and .index contain labels; .dtypes gives one data type per column.
A DataFrame has several columns, which may have different data types.
DataFrame Methods
Methods perform a task and use parentheses. .head(2) returns the first two rows. .tail(2) returns the last two. .info() prints a structural summary.
.info() prints its report; avoid wrapping it in print(...), which would also print its return value, None.
Column Types and Business Meaning
Quantity is numerical, Store is categorical, and Date initially contains text. A number-like code may still be an identifier. Data type and business meaning both matter.
Converting SalesText enables numerical calculations. Adding customer identifiers produces a number but rarely a useful business measure. If conversion fails, inspect the original text rather than silently treating invalid entries as zeros. Dates receive their own conversion in Section 7.
In-Class Practice: Inspect an Order Table
Print the row count, return the final two records, and name the column containing unit prices. Explain whether the index identifies stores or orders.
Hint: .shape[0], .tail(2), and .columns. Expected: four rows, last labels C and D, prices in Price.
Section 1 Practice — DataFrames and the First Look
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Table dimensions
Warm-up. Print the number of rows and columns separately.
Write your answer, then run it.
2. Column labels
Warm-up. Print the column labels as a Python list.
Write your answer, then run it.
3. First observations
Warm-up. Print the first two rows.
Write your answer, then run it.
4. Last observation
Build your skills. Print the final row.
Write your answer, then run it.
5. A column type
Build your skills. Print the dtype of the Units column.
Write your answer, then run it.
6. Series or table
Build your skills. Print the type names of df[“Units”] and df[[“Units”]].
Write your answer, then run it.
7. Named row labels
Build your skills. Print the index labels as a list. Explain how they differ from positions 0–3.
Write your answer, then run it.
8. Numeric text
Challenge. Convert SalesText into a numerical column and print its total.
Write your answer, then run it.
9. Load the course CSV
Challenge. Load the retail CSV using OrderID as its index. Print its shape and first index label.
Write your answer, then run it.
10. Inspect before calculating
Challenge. Create a two-row DataFrame with Store and Sales columns. Print its dimensions and total sales. Use stores Central/Kowloon and sales 120/80.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Table dimensions
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df.shape[0])
print(df.shape[1])Expected output
4
3The table contains four observations and three variables.
2. Column labels
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(list(df.columns))Expected output
['Store', 'Units', 'Price']The keys used to create the DataFrame become its column names.
3. First observations
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df.head(2))Expected output
     Store  Units  Price
A  Central      2    120
B Kowloon 1 80head(2) returns two rows without changing df.
4. Last observation
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df.tail(1))Expected output
     Store  Units  Price
D Kowloon 3 60tail(1) is useful for checking the end of a file.
5. A column type
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df["Units"].dtype)Expected output
int64A selected Series has one dtype.
6. Series or table
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(type(df["Units"]).__name__)
print(type(df[["Units"]]).__name__)Expected output
Series
DataFrameA list of column names preserves a DataFrame, even for one column.
7. Named row labels
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(list(df.index))Expected output
['A', 'B', 'C', 'D']A, B, C, and D are labels; numerical positions describe ordering.
8. Numeric text
import pandas as pd
df = pd.DataFrame({"SalesText": ["120", "80", "35"]})
df["Sales"] = pd.to_numeric(df["SalesText"])
print(df["Sales"].sum())Expected output
235Text containing digits should be converted before numerical analysis.
9. Load the course CSV
import pandas as pd
url = "https://busanalytics-book.pages.dev/data/chapter2-retail-orders.csv"
df = pd.read_csv(url, index_col="OrderID")
print(df.shape)
print(df.index[0])Expected output
(8, 6)
O101The eight order lines have six remaining columns after OrderID becomes the index.
10. Inspect before calculating
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon"], "Sales": [120, 80]})
print(df.shape)
print(df["Sales"].sum())Expected output
(2, 2)
200You should establish what the columns represent before calculating a total.
Selecting Columns, Rows, and Cells
Select records by label, position, or conditions; update cells; and split independent customers or time-ordered observations into training and test sets.
One Column or a Smaller Table
df["Units"] returns a Series. df[["Units", "Price"]] returns a DataFrame. The inner brackets form a list of column names.
Select Rows with iloc and Row Positions
.iloc[0] selects the first row. .iloc[1:3] selects positions 1 and 2. The stop position 3 is excluded, just as in list slicing.
Positions 1 and 2.
Select Rows with loc and Index Values
.loc["B"] selects the row whose index value is B. .loc["B":"D"] includes both index values B and D in this ordered example. Index values and row positions may select different rows.
Select Rows and Columns Together
The selection before the comma chooses rows; the selection after it chooses columns.
| Selection | Select rows using | Select columns using |
|---|---|---|
df.loc[rows, columns] |
Index values | Column names |
df.iloc[rows, columns] |
Row positions | Column positions |
Positions start at 0 for iloc. A colon : means all rows or all columns in that slot.
Predict the scalar in the last line: row C, column Price gives 35.
Select Data with Condition
Compare a column with a threshold to get one True/False value per row. df.loc[mask] selects the rows where the condition is True. Display the mask before using it.
Change the threshold from 3 to 4. Predict which labels remain.
Interactive Filter: Change the Threshold
Move the threshold and watch which order lines remain. Then reproduce that selection in the Python box below.
The highlighted rows satisfy Units >= threshold. The visual demonstration and the Python calculation use exactly the same four values. A threshold changes the population being summarised, so an average calculated after filtering describes only the retained records.
| Label | Store | Units | Keep? |
|---|---|---|---|
| A | Central | 2 | False |
| B | Kowloon | 1 | False |
| C | Central | 4 | True |
| D | Kowloon | 3 | True |
Retained labels: C, D
Combine Conditions with Parentheses
Use & for AND and | for OR. Put each comparison in parentheses. Python and and or do not combine whole Boolean Series this way.
Membership, Ranges, and Negation
.isin([...]) checks membership. .between(2, 3) includes both endpoints by default. ~ reverses a Boolean mask.
A missing comparison can behave differently from an ordinary observed value. When the question requires observed values, include notna() explicitly. Section 3 shows why negating “greater than” is unsafe as a substitute for “less than or equal” when missing values are present.
Update Selected Cells with loc
Use .loc[rows, column] = value to update the intended cells directly. If you need a separate result table, create a .copy() and edit that table.
Train/Test Splitting Depends on the Data
Training data develop a model. Test data check it on held-out observations.
| Prediction task | Defensible starting split | Why? |
|---|---|---|
| New independent customers from the same population | Randomly assign customers to train or test | Row position has no natural time meaning |
| Future sales from a time series | Sort dates; train on earlier dates, test on later dates | Future records are unavailable when training |
Repeated records from a customer require attention to groups. Predicting future behaviour also requires attention to time.
Split first, then learn cleaning values from training data only.
The split should mimic how the model will be used. For assessing performance on new customers, keep all records for each customer on one side of the split. If the target is future outcomes, respect the time cutoff even when the rows contain different customers. In panel data both entity and time constraints may matter. Computing an imputation value from the full dataset lets held-out observations influence the training process. Fit preprocessing on training data; do not estimate a separate test-set mean, median, or mode.
No. Independent cross-sectional observations may support a random split; forecasting requires earlier training and later test observations. Repeated entities may need group separation. Estimate preprocessing values from training data only.
Cross-sectional Example: Split Customers Randomly
Assume one row per independent customer in the same month. frac=0.75 selects 75% (six of eight) for training; the remaining customers form the test set.
Why use random_state=42? Computers make pseudo-random choices using an algorithm. A seed is the starting value for that algorithm.
- Same seed + same data and row order: in the same Python setup, the same customers are selected each time. This is reproducible random sampling.
- Different seed: the selected customers may change.
42is arbitrary; it is not a special or better number. - No fixed seed: repeated runs may select different customers.
Fixing the split lets classmates reproduce your results and lets you compare models on the same training/test customers.
An integer random_state restarts the pseudo-random sampling algorithm from the same seed for each call. Reproducibility assumes the same input rows in the same order, the same sampling arguments, and the same software setup; it is not a promise of identical samples after changing those conditions. A different seed may give a different sample, but two different seeds can also happen to select the same rows. Fix the split before comparing models so that a change in the test customers does not confuse the comparison. The seed makes the demonstration repeatable; it does not make the split statistically valid by itself. The example uses unique customer identifiers and assumes independent observations from the relevant population. If customers had repeated records, sampling individual rows could put the same customer on both sides.
Run the box twice: both seed-42 training lists match. Changing to 7 selects a different set in this example. Six customers train; two test; no customer appears in both. This same-month example does not evaluate a forecast of future months.
Time-series Example: Train Earlier, Test Later
Sort rows by date. Use the first 75% for training and the last 25% for testing.
cut is an ordinary variable that stores where to split the rows. It is the number of training rows and the row position where the test set begins.
len(sales)counts the rows: 8.0.75 * len(sales)calculates 75% of them: 6.0.int(...)converts that result to the integer 6, socut = 6.
| Selection | Row positions when cut = 6 |
Dates |
|---|---|---|
sales.iloc[:cut] |
0–5: the first six rows; stop before position 6 | 1–6 November |
sales.iloc[cut:] |
6–7: start at position 6 and continue to the end | 7–8 November |
Positions start at 0, so position 6 is the seventh row. cut is a position, not a date or an index value.
The name cut is chosen by the programmer; it is not a Python keyword or a pandas method. For a positive row count, int discards any fractional part rather than rounding to the nearest integer: for example, int(0.75 * 9) is int(6.75), which gives 6. The training slice excludes the stop position, and the test slice includes its starting position, so the two slices have no overlapping rows and together contain the complete sorted table. These date labels use the fixed YYYY-MM-DD format, so sorting the labels also sorts the dates. Section 7 introduces conversion to datetime values for general date operations. This example selects records; it does not fit a prediction model. Fit cleaning values on training data only, and never fill earlier predictors with future observations.
1–6 November: train → 7–8 November: test. Six earlier days train; two later days test. Do not shuffle a future-forecast evaluation.
In-Class Practice: A Purchasing List
Select Central orders with at least two units. Return only Units and Price. Predict the row labels before running your code.
Expected labels: A and C. Hint: combine two conditions, then use .loc[mask, [...]].
Section 2 Practice — Selecting Columns, Rows, and Cells
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Select a Series
Warm-up. Print the Units column as a Series.
Write your answer, then run it.
2. Select two columns
Warm-up. Print a DataFrame containing Store and Price.
Write your answer, then run it.
3. A positional slice
Warm-up. Print labels selected by positions 1:3.
Write your answer, then run it.
4. A label slice
Build your skills. Print labels selected by B:D.
Write your answer, then run it.
5. A single cell
Build your skills. Print the price of row C using loc.
Write your answer, then run it.
6. Quantity threshold
Build your skills. Print the labels of orders with at least three units.
Write your answer, then run it.
7. Two conditions
Build your skills. Print Units and Price for Central orders with at least two units.
Write your answer, then run it.
8. Either condition
Challenge. Print the labels of orders with Price >= 100 OR Units >= 4.
Write your answer, then run it.
9. Membership and ranges
Challenge. Keep Central rows whose Units lie between 2 and 4 inclusive. Print their labels.
Write your answer, then run it.
10. Update a separate result
Challenge. Copy df, reduce prices by 10 for Kowloon rows, then print the new prices and the original prices as lists.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Select a Series
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df["Units"])Expected output
A    2
B    1
C    4
D    3
Name: Units, dtype: int64Single-column selection gives a Series.
2. Select two columns
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df[["Store", "Price"]])Expected output
     Store  Price
A  Central    120
B  Kowloon     80
C  Central     35
D Kowloon 60A list of names selects a smaller DataFrame.
3. A positional slice
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(list(df.iloc[1:3].index))Expected output
['B', 'C']The stop position is excluded.
4. A label slice
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(list(df.loc["B":"D"].index))Expected output
['B', 'C', 'D']Both endpoints are included in this ordered label slice.
5. A single cell
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df.loc["C", "Price"])Expected output
35The row label and column name identify one value.
6. Quantity threshold
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(list(df.loc[df["Units"] >= 3].index))Expected output
['C', 'D']A Boolean condition retains C and D.
7. Two conditions
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
mask = (df["Store"] == "Central") & (df["Units"] >= 2)
print(df.loc[mask, ["Units", "Price"]])Expected output
   Units  Price
A      2    120
C 4 35Both comparisons must hold, and parentheses make the mask unambiguous.
8. Either condition
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
mask = (df["Price"] >= 100) | (df["Units"] >= 4)
print(list(df.loc[mask].index))Expected output
['A', 'C']The union keeps A and C.
9. Membership and ranges
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
mask = df["Store"].isin(["Central"]) & df["Units"].between(2, 4)
print(list(df.loc[mask].index))Expected output
['A', 'C']Both isin and between return Boolean Series.
10. Update a separate result
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
changed = df.copy()
mask = changed["Store"] == "Kowloon"
changed.loc[mask, "Price"] = changed.loc[mask, "Price"] - 10
print(list(changed["Price"]))
print(list(df["Price"]))Expected output
[120, 70, 35, 50]
[120, 80, 35, 60]The explicit copy preserves the original table.
Missing Data and Cleaning Decisions
Identify incomplete information and explain how a cleaning decision changes the records used in an analysis.
Missing Sales and Zero Sales
An unknown sales value does not establish zero sales. A recorded zero is an observed value. Pandas uses missing-value markers such as NaN, None, and pd.NA, depending on the column type.
Order B has unknown sales; order C has recorded sales of zero. Keeping this distinction matters for totals, averages, and operational follow-up. Filling B with zero would assert something that the original record does not tell us.
Detect and Count Missing Values
.isna() returns a Boolean table. Summing it counts True entries. .notna() identifies available observations.
True counts as 1 and False as 0, so the sum counts matching entries.
Find Incomplete Records
Select records whose Sales value is missing, then investigate the original record. A missing-value report should identify affected observations.
Missing Values Change the Denominator
The Sales mean uses three observed values: (100 + 0 + 300) / 3. len(df) counts rows; .count() counts non-missing values.
An all-missing sum can be misleading: use .sum(min_count=1) when an unknown total should remain missing.
Drop Rows: All Columns or a Subset
dropna() removes rows with any missing entry. dropna(subset=["Sales"]) checks Sales only. Explain why the retained sets differ.
dropna: Rows versus Columns
axis=0 drops affected rows. axis=1 drops affected columns. Removing a column can remove information from every record, so inspect the result.
The default is axis=0. In this example, axis=1 would remove both Sales and Rating because each has at least one missing value. The result does not become more useful merely because every remaining entry is complete.
Compare Filling Assumptions
A zero, mean, or median fill makes a different assumption. Compare the resulting means before deciding which, if any, is defensible.
The observed mean is 133.33. Filling the unknown sales with zero produces 100; filling with the observed mean preserves 133.33; filling with the observed median produces 125. A preserved mean does not prove that imputation is correct. The choice depends on how the value became missing and which business question is being answered.
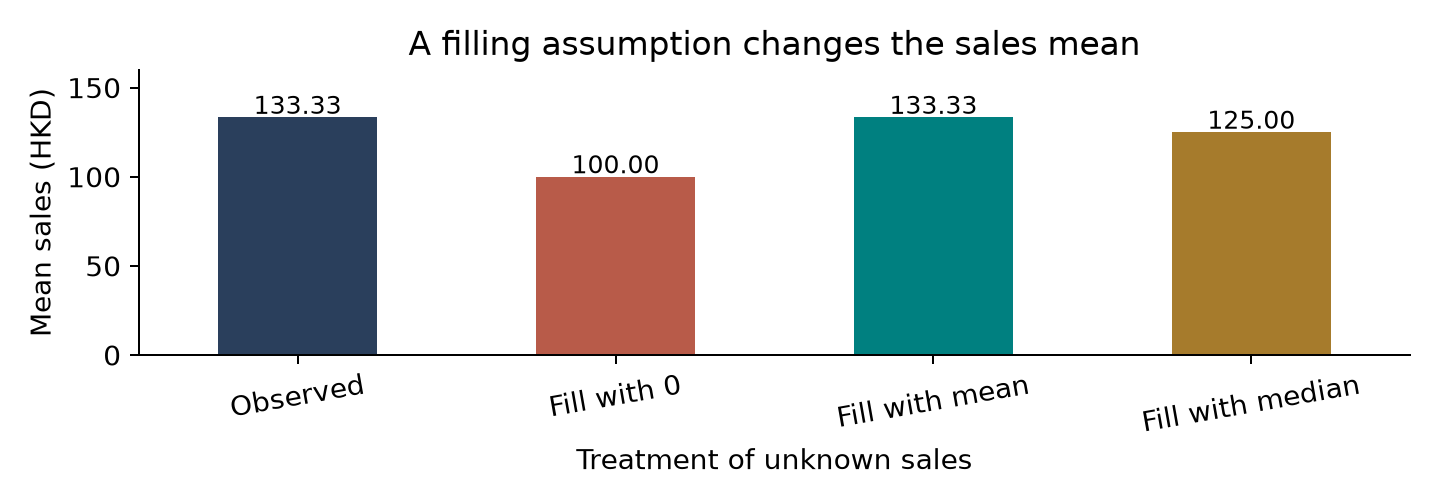
Does comparing these results tell us which filling assumption is justified? Explain what else we need to know.
Cross-sectional Data: Mean, Median, or Mode?
Cross-sectional data compare different customers, stores, or products in the same period. If filling is justified, choose by the variable and its observed distribution.
| Fill with | When to consider it | Example |
|---|---|---|
| Mean (average) | Numeric; roughly symmetric, without influential outliers | Delivery days near a typical value |
| Median (middle value) | Numeric; skewed or with extreme values | Customer spending with a few large purchases |
| Mode (most frequent value) | Categorical; a common category is a defensible guess | Payment method: Card or Cash |
These are starting rules, not proof. Investigate why data are missing. Do not forward-fill from an unrelated customer.
Use comparable observations: mixing very different customer or product groups can make a single fill value misleading. Mean filling preserves the observed mean but reduces the measured spread. Median filling is less sensitive to extremes, but neither method recovers the unknown value or its uncertainty. Mode filling increases the most common category and can distort proportions; an explicit Unknown category or follow-up may be preferable. Missingness related to the unreported value can bias all three methods. For predictive work, estimate the fill values from training data only and reuse them on the test set.
Mean: a roughly symmetric numeric variable without influential outliers. Median: a skewed numeric variable or one with extremes. Mode: a categorical variable when a common-category guess is defensible. First investigate missingness; none of these choices recovers the true value.
Apply Mean, Median, and Mode to Different Columns
Each row is a different customer in the same month. Predict the three fills for row D. .mode() returns a Series; .iloc[0] selects its first value.
The observed delivery times 2, 3, and 4 are symmetric around 3. Spending has a large value of HK$1,000, so its mean is about HK$403.33 while its median is HK$110. Card occurs twice and Cash once, giving a unique mode. The example demonstrates syntax with a tiny constructed sample; three observed customers are not evidence that these guesses suit a real business dataset. The original df remains unchanged. If multiple modes tie, iloc[0] mechanically takes the first one; this does not justify choosing it. If all entries are missing, mode() is empty and iloc[0] fails, while mean and median cannot supply a data-based value.
Expected fills: 3 days, HK$110, Card. These are assumptions, not observations. If modes tie or a column is entirely missing, investigate before choosing a fill.
There may be multiple tied modes or no observed values. The first returned category is not automatically a justified business choice.
Time Series: Why Forward, Not Backward?
In this course, use forward fill only for time series of the same entity, sorted by time, when the last value remains applicable.
A service fee stays valid until a new fee is announced. Read this timeline left to right:
| Fee (HKD) | Mon 2 Nov | Tue 3 Nov | Wed 4 Nov | Thu 5 Nov |
|---|---|---|---|---|
| Recorded update | 10 | Missing | 12 | Missing |
| Forward fill: earlier → later | 10 | 10 ← Monday | 12 | 12 ← Wednesday |
| Backward fill: earlier ← later | 10 | 12 ← Wednesday | 12 | Missing |
On Tuesday, 10 is already known; Wednesday’s 12 is still in the future. Backward fill leaks future information into a forecast made on Tuesday.
Here a blank means there is no newly recorded fee update, and the business rule says the most recently announced fee is still valid. Forward fill is therefore defensible. It is not a general cure for missing time-series observations: an unknown daily sales amount does not mean yesterday’s sales occurred again. Backward fill can have justified retrospective uses when later information is allowed, but not when the filled value is supposed to represent knowledge at an earlier forecast time. Pandas itself does not enforce a time-series restriction; sorting customers alphabetically and calling ffill would still execute, but would not supply a meaningful earlier observation.
Wednesday’s update was unavailable on Tuesday. Forward fill uses Monday’s known fee, provided it remains valid until a new announcement.
Forward Fill Uses a Previous Value
For this fee time series, .ffill() carries an earlier value forward; .bfill() brings a later value backward. Sort dates first and compare Tuesday in both columns.
The forward-filled path is 10, 10, 12, 12; the backward-filled path is 10, 12, 12, missing. Change the first input to None and run again: forward fill cannot invent an earlier observation. Forecast-time filling must use only information already available at that time. Even forward fill can be inappropriate when a value becomes stale or the quantity changes daily.
A leading gap stays missing with forward fill. A trailing gap stays missing with backward fill. Do not carry values between unrelated customers or stores.
Negation with Missing Values
For this float Series, ~(x > 3) also keeps the missing entry. If the question asks for observed values no greater than 3, include .notna() explicitly.
The missing entry is not evidence that its value is small.
In-Class Practice: A Cleaning Recommendation
Keep records with observed Sales even if Rating is missing. Print the before/after row counts and total observed sales. Explain why you have retained the zero-sales record.
Expected: 4 rows before, 3 after, observed total HK$400. The missing rating does not prevent a sales calculation.
Section 3 Practice — Missing Data and Cleaning Decisions
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Count missing sales
Warm-up. Print the number of missing Sales entries.
Write your answer, then run it.
2. Keep a recorded zero
Warm-up. Print Order labels for observed Sales equal to zero.
Write your answer, then run it.
3. Missing counts by column
Warm-up. Print the missing count for every column.
Write your answer, then run it.
4. Drop incomplete records
Build your skills. Drop rows with any missing entry and print retained Order labels.
Write your answer, then run it.
5. Check only Sales
Build your skills. Drop rows only when Sales is missing. Print retained Order labels.
Write your answer, then run it.
6. Mean denominator
Build your skills. Print the row count, observed Sales count, and Sales mean rounded to two decimals.
Write your answer, then run it.
7. Median fill in a copy
Build your skills. Copy df and fill missing Sales with its observed median. Print the filled list and show that df still has one missing Sale.
Write your answer, then run it.
8. Column deletion
Challenge. Drop columns containing any missing entry and print the remaining column names.
Write your answer, then run it.
9. Carry a valid fee forward
Challenge. Forward-fill these recorded fees and print the resulting list. Explain why the first entry stays missing.
Write your answer, then run it.
10. Observed values and a threshold
Challenge. Select only non-missing values <= 3 and print them as a list.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Count missing sales
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
print(df["Sales"].isna().sum())Expected output
1There is one unknown sales record.
2. Keep a recorded zero
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
print(list(df.loc[df["Sales"].notna() & (df["Sales"] == 0), "Order"]))Expected output
['C']Recorded zero is available information.
3. Missing counts by column
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
print(df.isna().sum())Expected output
Order     0
Sales     1
Rating    1
dtype: int64The Sales and Rating columns each have one missing entry.
4. Drop incomplete records
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
print(list(df.dropna()["Order"]))Expected output
['A', 'D']Both Sales and Rating are required by this broad rule.
5. Check only Sales
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
print(list(df.dropna(subset=["Sales"])["Order"]))Expected output
['A', 'C', 'D']An unknown rating does not remove an observed sales value.
6. Mean denominator
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
print(len(df))
print(df["Sales"].count())
print(round(df["Sales"].mean(), 2))Expected output
4
3
133.33The observed mean uses three entries, not four.
7. Median fill in a copy
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
clean = df.copy()
clean["Sales"] = clean["Sales"].fillna(clean["Sales"].median())
print(list(clean["Sales"]))
print(df["Sales"].isna().sum())Expected output
[100.0, 100.0, 0.0, 300.0]
1The median is 100, and an explicit copy preserves the input.
8. Column deletion
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
print(list(df.dropna(axis=1).columns))Expected output
['Order']Deleting columns removes Sales and Rating information from all rows.
9. Carry a valid fee forward
import pandas as pd
fees = pd.Series([None, 10.0, None, 12.0])
print(list(fees.ffill()))Expected output
[nan, 10.0, 10.0, 12.0]There is no prior fee for the first observation.
10. Observed values and a threshold
import pandas as pd
x = pd.Series([2.0, None, 4.0, 3.0])
print(list(x[x.notna() & (x <= 3)]))Expected output
[2.0, 3.0]Explicit availability avoids interpreting unknown observations as small.
Feature Engineering and Modifying Tables
Create business measures whose formulas, units, and handling of missing values you can explain.
A Feature Is a Variable Used in Analysis
An existing column can be a feature. We can also derive a new variable from existing columns. Revenue, gross profit, and order-size labels answer different business questions.
Units × HKD per unit gives revenue in HKD.
Revenue: Multiply Corresponding Rows
Columns are Series, so arithmetic acts element by element and aligns row labels. An explicit loop is unnecessary for this calculation.
Change O101’s Quantity from 2 to 3. Predict its new Revenue before running.
Product Cost and Gross Profit
ProductCost = Quantity × UnitCost. GrossProfit = Revenue − ProductCost. This excludes rent, salaries, and other operating expenses.
Gross Margin and a Zero Denominator
Gross margin is GrossProfit / Revenue. A zero-revenue record has an undefined margin. Copy Revenue, then use .loc to replace non-positive denominators with None before dividing. Pandas displays these missing numerical values as NaN.
The zero-quantity order has zero revenue and zero gross profit, but 0/0 does not define a margin. The copy retains every order index value. Setting the non-positive denominators to None makes them missing, without changing the original Revenue column. Dividing by a missing denominator leaves Margin missing for that order. The column stores a fraction: 0.40 represents 40%.
loc: Select Rows or Update Selected Values
Use .loc in two ways:
- Select:
orders.loc[positive, "Revenue"]returns only the positive-revenue rows A and C. - Assign:
denominator.loc[denominator <= 0] = Nonechanges the zero value to missing in a copied Series. All three index values remain.
A loc selection returns the matching rows. A loc assignment updates selected positions in the existing object. Here selected is a shorter Series with index values A and C; denominator retains A, B, and C, and B becomes NaN. The original orders table keeps its zero because denominator is a separate copy. Retaining the index lets us divide gross profit by the corresponding denominator for every order.
Selection returns 2 rows; assignment keeps 3: B is absent from selected but remains as NaN in denominator. The original Revenue column still contains zero for B.
Selection returns matching rows. Assignment changes selected values in an existing object while keeping its index. Use copy() first to preserve the original values.
Labels with a Short Comprehension
Revisit Chapter 1: label observed orders as Large when Revenue >= 200, and Standard otherwise. This example has complete revenue values.
A two-branch label is only appropriate when its branches cover all intended cases.
Labels That Preserve Missing and Zero Values
Initialise a clear label, then use .loc for observed positive, zero, and negative values. An unknown return should remain Unknown.
A two-branch expression sends every value failing r > 0 into its else branch, including zero and a float NaN. These explicit masks preserve four different cases. Direction labels describe the observations; an investment recommendation requires additional evidence.
Change Column Names and Drop Columns
Use the .columns attribute to assign a list of column names in their current order. Use .copy() first to preserve the original table. .drop(columns=[...]) returns a table without the specified columns.
The table has three columns in the order Store, Units, Price. Assigning [“Store”, “Quantity”, “Price”] to the copied table’s columns changes only the second name because the other two names are repeated unchanged. The list must contain one name for every column, in the same order. Dropping Price from this copy produces compact, while df retains its original column names and values.
Sort Rows: Ascending or Descending
by="Price" chooses the sorting column. axis=0 reorders whole rows. ascending=True means smallest first; ascending=False means largest first. There is no descending= argument.
axis=0 and ascending=True are the defaults. Sorting returns a reordered table; assigning it to high_first does not reorder df. Pick the business variable deliberately: a high unit price does not necessarily mean high order revenue or gross profit.
Predict the descending labels: A, B, D, C. Store and Price move together; the original row labels stay attached.
df.sort_values(by=“Price”, axis=0, ascending=False). The complete rows move together.
Sorting axis: Reorder Rows or Columns
| Argument | Default when omitted | What it controls |
|---|---|---|
axis |
axis=0 |
Reorder whole rows using values in a named column. Use axis=1 to reorder columns using a named row. |
ascending |
ascending=True |
Put smaller values first. Use ascending=False to put larger values first. |
With neither argument supplied, .sort_values(by="Monday") sorts rows by Monday from smallest to largest.
For a DataFrame, sort_values defaults to axis=0 and ascending=True. Thus wide.sort_values(by=“Monday”) gives the same result as wide.sort_values(by=“Monday”, axis=0, ascending=True). axis identifies what is reordered, while ascending independently sets the direction. Sorting columns using the Central row applies one common column order to the whole table: Kowloon values move with their column names. For sum and mean, axis identifies the dimension being reduced; do not memorise one result-shape rule for every pandas operation.
Default row order: Central, Kowloon. Descending row order: Kowloon, Central. Descending column order using Central: Tuesday, Monday.
The defaults are axis=0 and ascending=True: sort rows by the named column, smallest values first.
Sort a Series and Place Missing Values
A selected column is a Series: use .sort_values() without by. Its labels stay attached. Missing values go last by default, even for descending order; na_position="first" moves them first.
A Series has only its index axis; axis=1 is not available. Series.sort_values sorts its values, whereas sort_index sorts its labels. Neither ordering supplies a value for an unknown observation.
Descending observed values are A = 120, D = 60, C = 35. Moving B does not fill its missing value.
Method Chaining: Pass the Result On
A chain passes each returned object to the next method. First sort the table, then take its first two rows. Read left to right; in a multiline chain, read top to bottom.
Method chaining saves intermediate variable names; it does not change the meaning of the operations. The result of sort_values is the receiver of head, so head works on the sorted table. Use intermediate variables when you need to inspect or reuse a step. The equals method checks that the two results have matching values and labels.
df → sorted DataFrame → first two rows. Both versions return A and B. The dot calls the next method on the previous result.
The DataFrame returned by sort_values, rather than the original unsorted df.
Build a Readable Three-Step Chain
Task: find the two largest observed revenues. Step 1 removes unknown revenues (4 → 3 rows). Step 2 sorts those 3 rows. Step 3 keeps the first 2. Write the three calls as one expression and read from left to right.
Each method receives the DataFrame returned by the previous method. The chain returns a new result; the original df still has four rows. Removing unknown Revenue entries is part of this question because it explicitly asks for observed revenues. To inspect an intermediate result, first use named steps such as observed = df.dropna(…) and ranked = observed.sort_values(…), then combine them into a short chain.
Expected: C = 300, D = 200. All three methods return DataFrames. Change .head(2) to .head(1) and predict the result.
The Order of Methods Changes the Question
Sort → head: find the largest two orders in the whole table. Head → sort: rank only the first two recorded orders. The same method names can answer different questions.
Every step changes the object available to later steps. Sorting cannot recover rows that an earlier head or filter removed. For the largest eligible orders, first select eligible rows, then sort, then take head. In a forecasting task, retain the chronological train/test split before doing calculations on training data.
First result: B, C. Second result: B, A. Predict both before running; C is already excluded when .head(2) runs first.
No. The first ranks all records; the second ranks only the first two records.
Check the Returned Object Before Chaining
df["Revenue"] returns a Series; .dropna() returns another Series; .sum() returns one number. Stop when you have the answer. A next method must be supported by the returned object.
Common pitfalls: info() prints a report and returns None, so it cannot pass a table to head(). Sorting with inplace=True changes the original object and returns None; do not use it inside a chain. Keep the default inplace=False and assign the final result. A scalar total is not a table, so table methods such as head are unavailable. A dot alone does not guarantee a chain is meaningful; check the type and business meaning after each step.
Both totals are 600. Keep chains short; split them into named steps when the intermediate result needs checking.
Compare Two Ways to Rescale a Feature
Let x be one Sales value. Calculate the reference values from the same Sales Series.
| Comparison | Min-max scaling | Z-score standardisation |
|---|---|---|
| Formula | (x - min) / (max - min) |
(x - mean) / std |
| What it measures | Position within the observed range | Distance from the mean in standard-deviation units |
| A result of 0 means | The observed minimum | The observed mean |
| A result of 1 means | The observed maximum | One standard deviation above the mean |
| Range for these input values | 0 to 1 | No fixed bounds; values can be negative |
| Required denominator | max - min > 0 |
std > 0 |
Both methods rescale values; neither makes a distribution normal. Here std is the sample standard deviation returned by .std().
For the illustrated input values, min-max scaling sends 100 to 0 and 400 to 1. Z-scores centre these values at mean zero and sample standard deviation one. pandas Series.std uses ddof=1 by default. Both transformations preserve the ordering of a nonconstant numerical feature; neither makes a skewed distribution normal or removes extreme observations. The formulas require a nonzero denominator. For predictive modelling, estimate the minimum, maximum, mean, and standard deviation from the training data and reuse those values on later data. Later min-max values can fall outside 0 to 1.
In-Class Practice: A Margin Calculation
Calculate revenue and gross profit for each record. Then print the label of the order with the largest gross profit. Explain the units.
Expected gross profits: A = 100, B = 54, C = 40 HKD. A ranks first.
Section 4 Practice — Feature Engineering and Modifying Tables
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Calculate revenue
Warm-up. Create Revenue = Units × Price and print its values as a list.
Write your answer, then run it.
2. Total revenue
Warm-up. Calculate Revenue and print its total.
Write your answer, then run it.
3. Product cost
Warm-up. Add ProductCost to this table and print its list.
Write your answer, then run it.
4. Gross profit
Build your skills. Calculate GrossProfit from Revenue and ProductCost, then print its total.
Write your answer, then run it.
5. Order-size labels
Build your skills. Use a comprehension to label observed revenues >= 200 as Large and others as Standard. Print the list.
Write your answer, then run it.
6. Change a column name
Build your skills. Change Units to Quantity in a copy using the columns attribute, then print the column names.
Write your answer, then run it.
7. Keep a smaller table
Build your skills. Drop Price into a new table and print both new and original column labels.
Write your answer, then run it.
8. The two largest orders
Challenge. Calculate Revenue, sort descending, and print labels of the top two records.
Write your answer, then run it.
9. Undefined margins
Challenge. Calculate Margin using only positive Revenue denominators. Print rounded margins as a list.
Write your answer, then run it.
10. Four direction labels
Challenge. Use loc assignments to label positive returns Up, zero Flat, negative Down, and missing Unknown. Print the list.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Calculate revenue
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
df["Revenue"] = df["Units"] * df["Price"]
print(list(df["Revenue"]))Expected output
[240, 80, 140, 180]The products pair observations in the same row.
2. Total revenue
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
df["Revenue"] = df["Units"] * df["Price"]
print(df["Revenue"].sum())Expected output
640Summing order revenues gives the total for these four records.
3. Product cost
import pandas as pd
df = pd.DataFrame({"Units": [2, 3, 1], "UnitCost": [70, 22, 50]})
df["ProductCost"] = df["Units"] * df["UnitCost"]
print(list(df["ProductCost"]))Expected output
[140, 66, 50]Quantity times unit cost is the total product cost.
4. Gross profit
import pandas as pd
df = pd.DataFrame({"Revenue": [240, 120, 90], "ProductCost": [140, 66, 50]})
df["GrossProfit"] = df["Revenue"] - df["ProductCost"]
print(df["GrossProfit"].sum())Expected output
194The sum is gross profit before operating expenses.
5. Order-size labels
import pandas as pd
df = pd.DataFrame({"Revenue": [240, 80, 140, 300]})
df["Size"] = ["Large" if r >= 200 else "Standard" for r in df["Revenue"]]
print(list(df["Size"]))Expected output
['Large', 'Standard', 'Standard', 'Large']The threshold is inclusive and all revenues in this example are observed.
6. Change a column name
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
renamed = df.copy()
renamed.columns = ["Store", "Quantity", "Price"]
print(list(renamed.columns))Expected output
['Store', 'Quantity', 'Price']Assign one column name for each existing column, in order. The copied table protects the original column names.
7. Keep a smaller table
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
compact = df.drop(columns=["Price"])
print(list(compact.columns))
print(list(df.columns))Expected output
['Store', 'Units']
['Store', 'Units', 'Price']The returned result has fewer columns while df retains its original columns.
8. The two largest orders
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
df["Revenue"] = df["Units"] * df["Price"]
ranked = df.sort_values("Revenue", ascending=False)
print(list(ranked.head(2).index))Expected output
['A', 'D']The ranking is based on total order revenue, not unit price.
9. Undefined margins
import pandas as pd
df = pd.DataFrame({"Revenue": [100.0, 0.0, 200.0], "GrossProfit": [40.0, 0.0, 50.0]})
denominator = df["Revenue"].copy()
denominator.loc[denominator <= 0] = None
df["Margin"] = df["GrossProfit"] / denominator
print(list(df["Margin"].round(2)))Expected output
[0.4, nan, 0.25]An undefined zero-revenue margin stays missing.
10. Four direction labels
import pandas as pd
df = pd.DataFrame({"Return": [0.02, 0.0, -0.01, None]})
df["Direction"] = "Unknown"
df.loc[df["Return"] > 0, "Direction"] = "Up"
df.loc[df["Return"] == 0, "Direction"] = "Flat"
df.loc[df["Return"] < 0, "Direction"] = "Down"
print(list(df["Direction"]))Expected output
['Up', 'Flat', 'Down', 'Unknown']Explicit cases preserve the difference between zero and unknown.
Exploratory Data Analysis
Describe typical values, variation, unusual observations, and relationships using meaningful units and denominators.
Business Questions Before Statistics
How large is a typical order? How much do values vary? Are unusual orders driving the average? Which variables move together? State the question before choosing the method.
Read describe One Statistic at a Time
df.describe() calls a DataFrame method and returns a new DataFrame of summary statistics. For a table containing numbers and text, it summarises the numeric columns by default. Here, we select Revenue and GrossProfit, then summarise each column separately.
| Output row | What it tells us |
|---|---|
count |
Number of observed (non-missing) values |
mean |
Arithmetic average |
std |
Sample standard deviation: how spread out the values are |
min |
Smallest observed value |
25% |
First quartile: the 25th percentile |
50% |
Median: the 50th percentile |
75% |
Third quartile: the 75th percentile |
max |
Largest observed value |
Missing values are excluded separately for each column. A recorded zero is included. The original table is unchanged.
Read the output down one column at a time. Revenue and GrossProfit are the original variable names; count, mean, std and the other statistics are index values in the returned summary DataFrame. All eight orders have observed revenue and gross profit, including the zero-quantity order, so both counts are 8. A displayed count such as 8.0 still means eight observations. The mean revenues are in HKD per order. The 50% row equals the median; it is not half of total revenue. The sample standard deviation uses n - 1. Calling describe() after selecting or filtering data summarises only that selected table.
A new summary DataFrame. With numeric columns present, the default summary covers those columns. Missing values are excluded within each column; recorded zeros are included.
Mean, Median, and a Large Order
One large order can move the mean substantially. Compare the mean and median, then inspect the distribution rather than declaring a large observation an error.
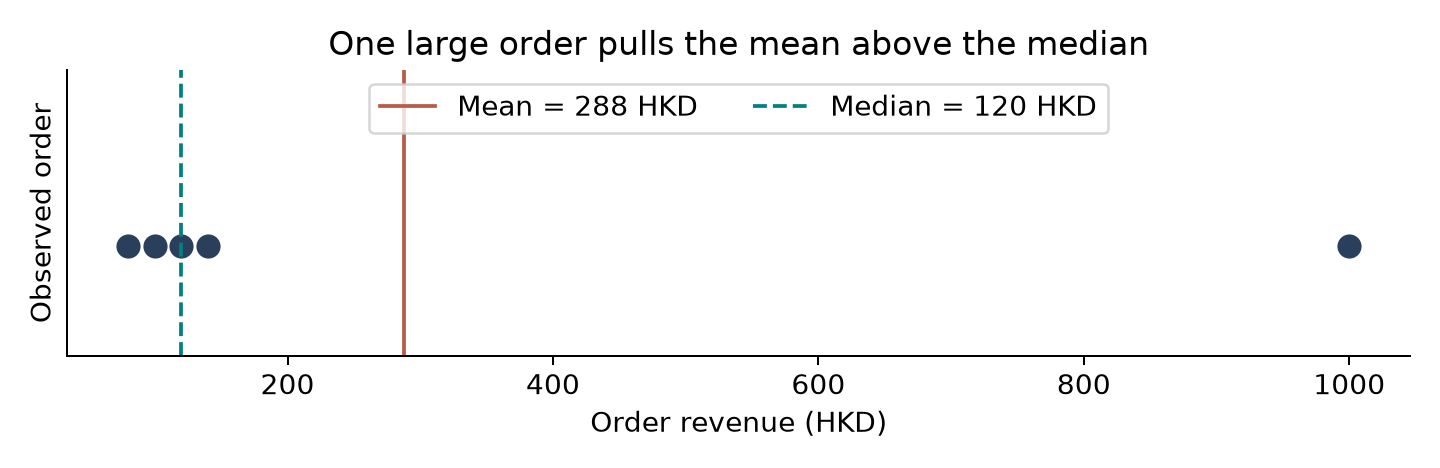
Change 1000 to 200. Predict which summary changes more.
Spread, Quantiles, and Extremes
Use .std() for spread, .quantile(0.75) for a quartile, and .min() / .max() for extremes. Pandas uses sample standard deviation (ddof=1) by default.
Understanding axis: Rows and Columns
For these reductions, axis=0 operates down rows and returns one result per column. axis=1 operates across columns and returns one result per row.
The axis identifies the dimension being reduced. A column mean collapses rows, leaving one value per column. A row mean collapses columns, leaving one value per row. This result-shape explanation is more useful than memorising “rows versus columns” without knowing the operation.
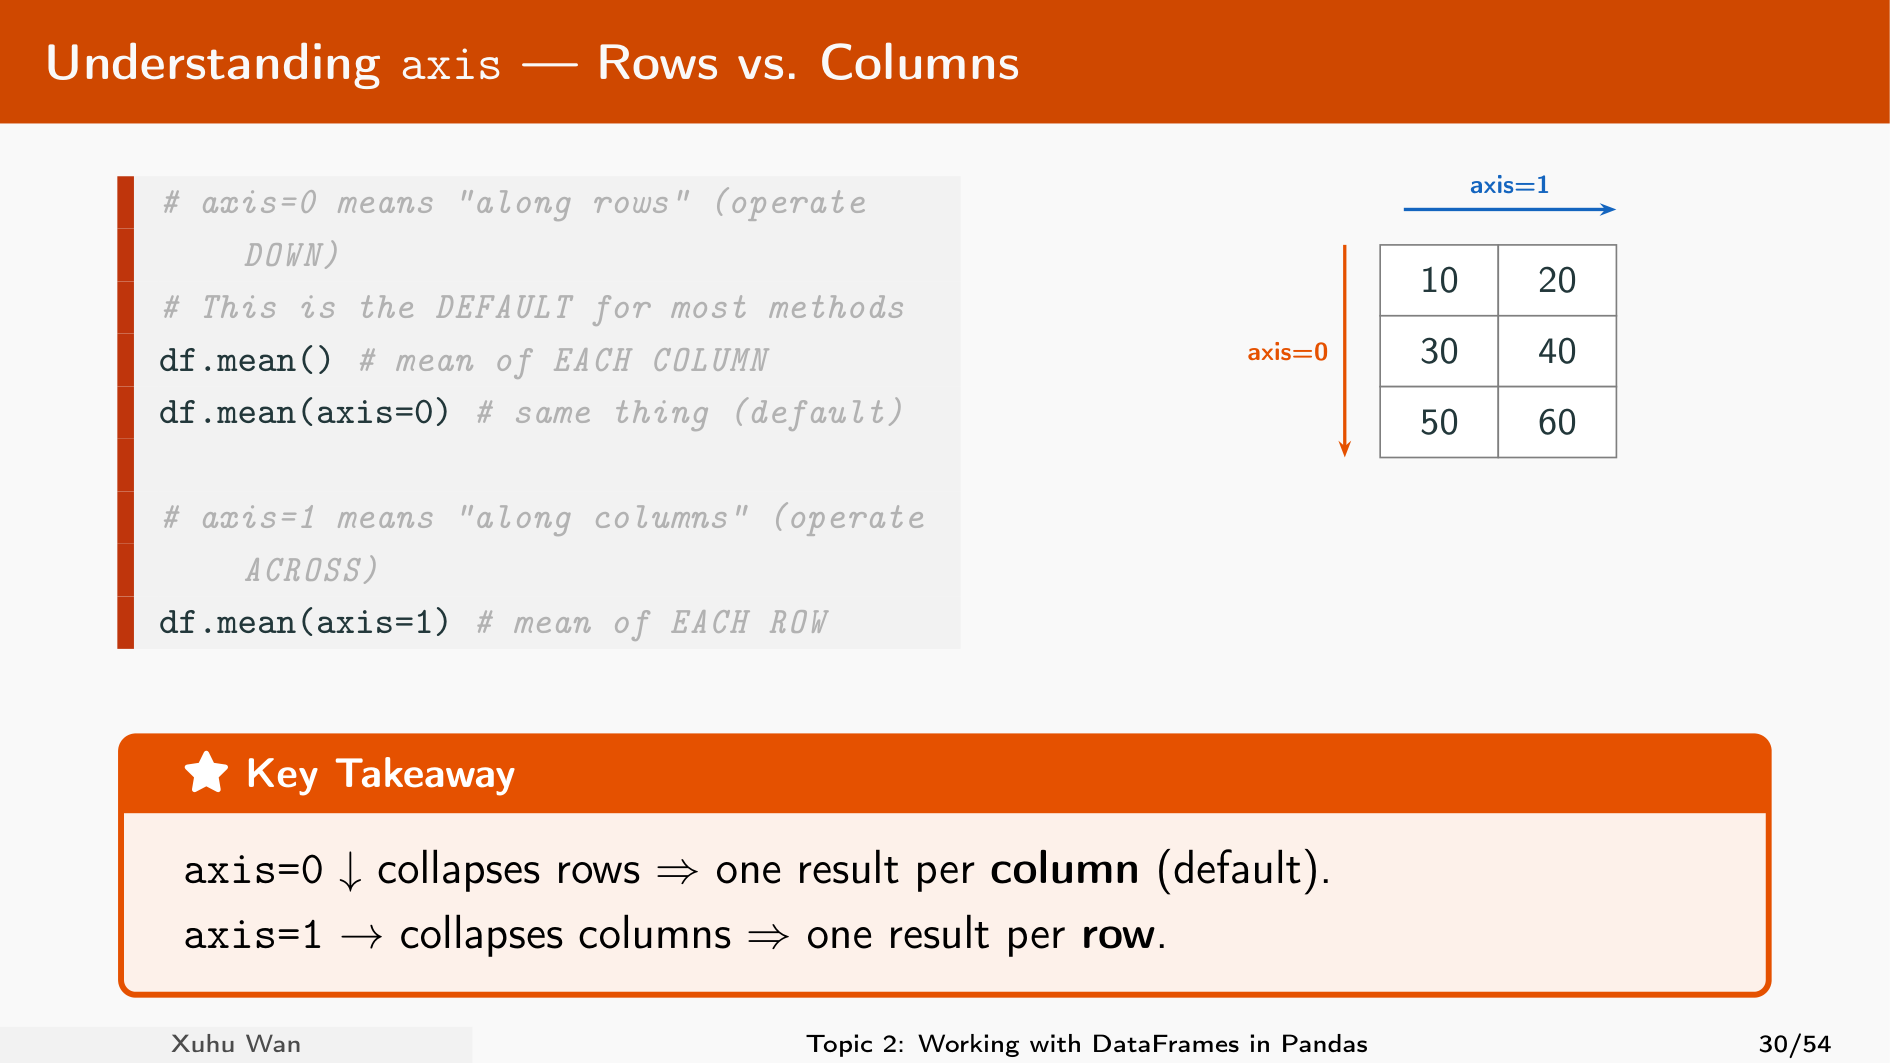
axis in a Table with Comparable Units
Both columns contain sales in HKD. Sum down rows to get totals by day; sum across columns to get totals by store. Combining prices and trading volumes in one mean or standard deviation would mix units.
| Store | Monday (HKD) | Tuesday (HKD) |
|---|---|---|
| Central | 100 | 150 |
| Kowloon | 200 | 250 |
Monday = 300 HKD; Tuesday = 400 HKD
value_counts: Count Each Category
.value_counts() returns a Series: its index contains category labels and its values contain frequencies. It counts records, not revenue. By default, the most frequent categories come first and missing entries are excluded.
For a table, select the category column first: orders[“Category”].value_counts(). This is a Series result, so counts.loc[“Gifts”] selects one frequency by its category label. Counting categories answers how often a label occurs; summing Revenue after a conditional selection answers a different question.
Gifts appears 3 times; Stationery and Accessories appear once each. Five categories are observed across six records.
The index lists categories; each value counts that category among the included observations.
value_counts: Include Missing Categories
value_counts() uses dropna=True by default, so missing values are not counted. categories.value_counts() and categories.value_counts(dropna=True) give the same result. Use dropna=False to include missing entries in the frequency counts.
A missing entry can display as None, NaN, or
Default total: 5. With dropna=False: 6, including one missing category. This option counts the gap; it does not fill it.
Chain Counts, Sorting, and Top Categories
Read this chain as categories → frequency Series → descending frequencies → top two. sort_values now sorts the counts, not the original category names.
The explicit sort_values call illustrates chaining but is redundant for this default value_counts result. value_counts(ascending=True) sorts frequencies from low to high. It does not alphabetise the category labels. If categories tie at a selection cutoff, decide and state how the tie should be handled rather than assigning a unique business rank without a rule.
Top two: Gifts = 3, Stationery = 2. value_counts() already sorts descending, so .value_counts().head(2) gives the same top two here.
Correlation Needs a Scatterplot
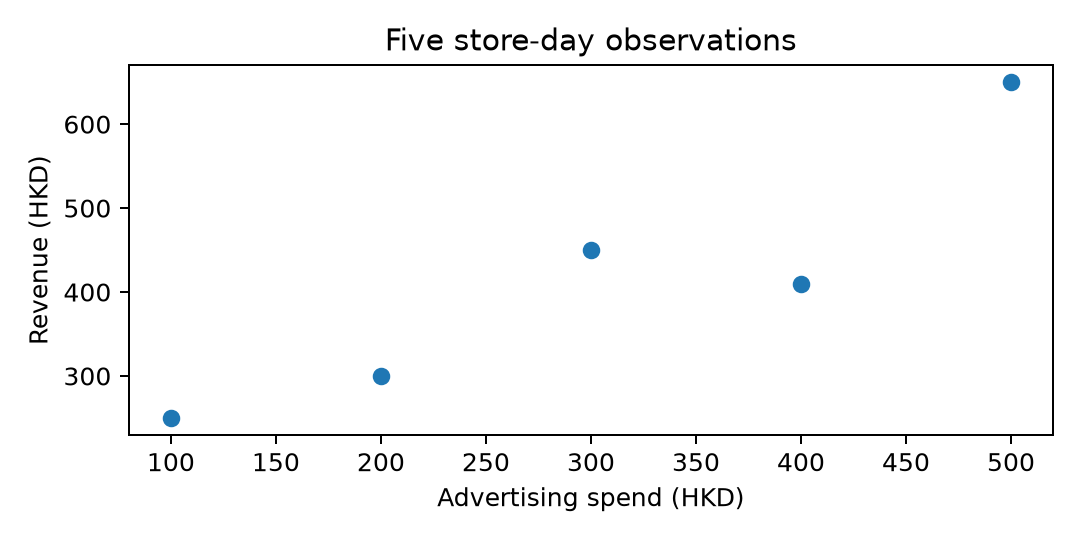
Correlation describes association. A high correlation alone does not establish causation. plt.scatter(x, y) plots one point for each paired observation: advertising spend on the horizontal axis and revenue on the vertical axis.
The five observations illustrate a descriptive relationship. Busy days could affect both advertising decisions and revenue. A causal claim about increasing advertising requires an appropriate design and additional information. Correlation also becomes unreliable or undefined when the paired data have little variation or very few usable observations. Pass the AdSpend Series first and the Revenue Series second to plt.scatter(). Use plt.title(), plt.xlabel(), and plt.ylabel() to label the chart and its units.
In-Class Practice: A Supported Finding
Calculate the mean, median, and largest order value. Write one sentence explaining why the mean alone could mislead a manager describing a typical order.
Expected: mean 288, median 120, maximum 1000 HKD. The largest order raises the mean substantially.
Section 5 Practice — Exploratory Data Analysis
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Typical order
Warm-up. Print the mean and median of these sales.
Write your answer, then run it.
2. Observed count
Warm-up. Print the count of observed values and the number of rows.
Write your answer, then run it.
3. A quartile
Warm-up. Print the 75th percentile of [100, 200, 300].
Write your answer, then run it.
4. Sample spread
Build your skills. Print the sample standard deviation of [100, 200, 300].
Write your answer, then run it.
5. Category counts
Build your skills. Print category counts for these orders.
Write your answer, then run it.
7. Reduce down rows
Build your skills. Print Monday and Tuesday totals as a list.
Write your answer, then run it.
8. Reduce across columns
Challenge. Print Central and Kowloon totals as a list.
Write your answer, then run it.
9. A large observation
Challenge. Compare the full mean with the mean after removing the 1000 order. Print both.
Write your answer, then run it.
10. Calculate and interpret correlation
Challenge. Print the correlation between AdSpend and Revenue, followed by a statement that it does not establish causation.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Typical order
import pandas as pd
sales = pd.Series([80, 100, 120, 140, 1000])
print(sales.mean())
print(sales.median())Expected output
288.0
120.0The mean is sensitive to the large order.
2. Observed count
import pandas as pd
sales = pd.Series([100.0, None, 0.0, 300.0])
print(sales.count())
print(len(sales))Expected output
3
4count excludes missing values, while len counts all entries.
3. A quartile
import pandas as pd
sales = pd.Series([100, 200, 300])
print(sales.quantile(0.75))Expected output
250.0With pandas default interpolation, the quartile lies between 200 and 300.
4. Sample spread
import pandas as pd
sales = pd.Series([100.0, 200.0, 300.0])
print(sales.std())Expected output
100.0The default sample denominator is n − 1.
5. Category counts
import pandas as pd
categories = pd.Series(["Gifts", "Gifts", "Stationery", "Gifts"])
print(categories.value_counts())Expected output
Gifts         3
Stationery    1
Name: count, dtype: int64Three of four entries belong to Gifts.
6. Category shares
import pandas as pd
categories = pd.Series(["Gifts", "Gifts", "Stationery", "Gifts"])
shares = categories.value_counts(normalize=True)
print(shares.loc["Gifts"])Expected output
0.75The denominator is the four counted observations.
7. Reduce down rows
import pandas as pd
df = pd.DataFrame({"Monday": [100, 200], "Tuesday": [150, 250]}, index=["Central", "Kowloon"])
print(list(df.sum(axis=0)))Expected output
[300, 400]Reducing rows leaves one total per day column.
8. Reduce across columns
import pandas as pd
df = pd.DataFrame({"Monday": [100, 200], "Tuesday": [150, 250]}, index=["Central", "Kowloon"])
print(list(df.sum(axis=1)))Expected output
[250, 450]Comparable HKD columns can be added across each store row.
9. A large observation
import pandas as pd
sales = pd.Series([80, 100, 120, 140, 1000])
print(sales.mean())
print(sales[sales < 1000].mean())Expected output
288.0
110.0The comparison measures sensitivity; it does not prove the large order is invalid.
10. Calculate and interpret correlation
import pandas as pd
df = pd.DataFrame({"AdSpend": [100, 200, 300, 400, 500], "Revenue": [250, 300, 450, 410, 650]})
print(df["AdSpend"].corr(df["Revenue"]))
print("This association does not establish causation.")Expected output
0.9245370658481828
This association does not establish causation.A numerical association and a causal effect answer different questions.
Business Charts
Select each store or category with a condition, calculate its summary, and choose a chart that answers the business question.
Individual Orders and Group Summaries
Work one store at a time: select its Revenue values with .loc, inspect the selected rows, then call .sum(). Repeat the same steps for the other store.
Group Totals and Group Averages
Total revenue measures contribution to sales. Mean revenue measures average order size. A group with more orders can rank differently on these measures.
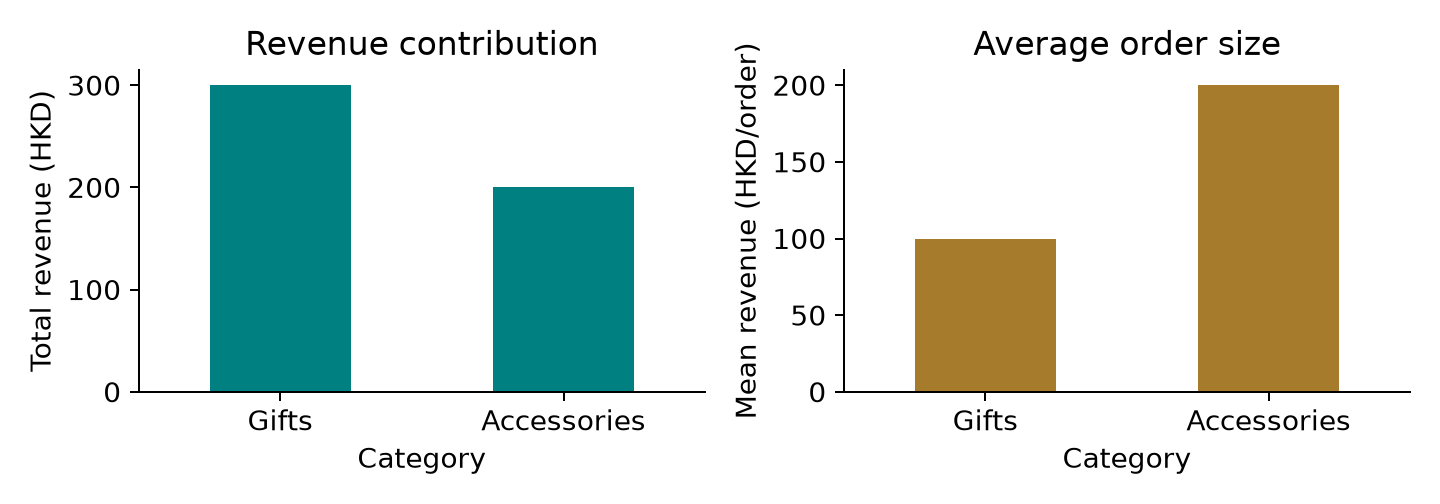
Gifts has total 300; Accessories has mean 200.
Group Size and Available Values
Select each store separately. len(central) counts all selected entries; central.count() counts observed values. The mean uses only observed values.
One Category, Three Simple Calculations
First select Gifts revenue. Then calculate the count, total, and average on separate lines. Change "Gifts" to "Stationery" and run again.
Plot as a Method of DataFrame and Series
In 1.5, plt.plot(x, y) and plt.scatter(x, y) are functions: we pass the data to Matplotlib. In 2.6, we call .plot() on the pandas Series or DataFrame that contains the data.
| Pandas call | What it draws |
|---|---|
series.plot() |
A line: Series index on x, values on y |
df.plot(kind="scatter", x="AdSpend", y="Revenue") |
A scatterplot using the two named columns |
Select → summarize → plot in one line. Here, count categories for Central only. kind="bar" chooses a bar chart; .plot.bar() is a shorthand for .plot(kind="bar").
A pandas plotting call uses Matplotlib by default. A DataFrame can plot named columns; a Series already has an index and values. Each step in this chain passes its result to the next: .loc selects Central and its Category column as a Series, value_counts() returns a frequency Series, and plot(kind=“bar”) draws those frequencies. Do the data selection and pandas calculations before plotting: .plot() returns a Matplotlib Axes, not another Series or DataFrame. The chart counts orders, not revenue. The example is self-contained and does not depend on code from another slide.
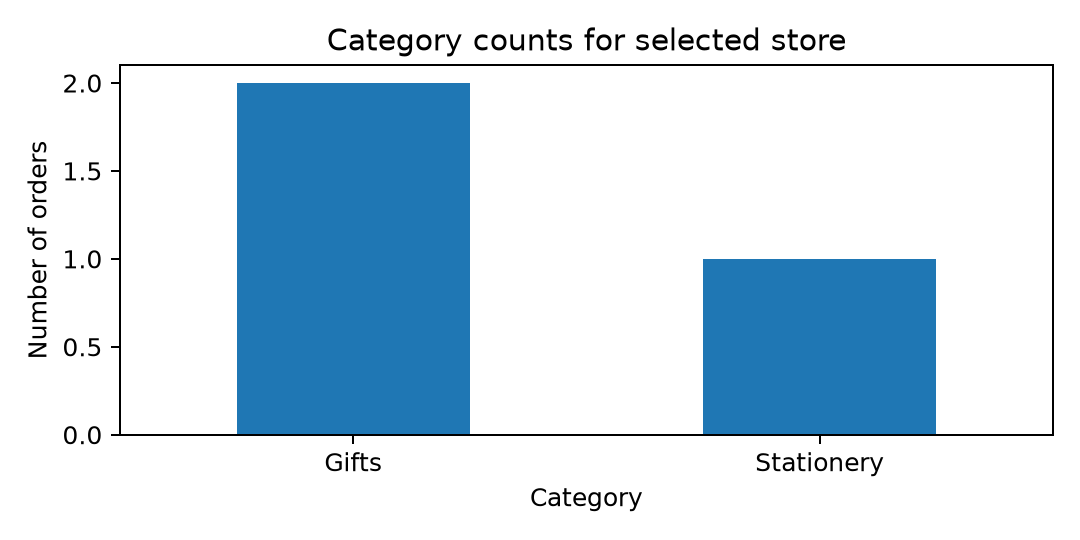
Read left to right: select Central’s Category Series → count each category → draw the counts. Result: Gifts = 2 orders; Stationery = 1. Change "Central" to "Kowloon" in the .loc condition and run again.
They return pandas objects that support the next data operation. The final .plot() draws the result and returns a Matplotlib Axes.
Bar Chart: Compare Category Totals
Calculate the totals first, then plot them. A bar chart compares distinct categories. Here, .plot.barh(...) draws horizontal bars and returns the chart’s Axes object, which we save as ax. It is the plotting area that contains the bars, title, and axes.
Horizontal or vertical? The h in barh means horizontal. Both charts compare the same category totals; only their orientation changes.
| Pandas method | Direction of bars | Category axis | Revenue axis |
|---|---|---|---|
.plot.barh() |
Horizontal: bar length shows revenue | y | x (HKD) |
.plot.bar() |
Vertical: bar height shows revenue | x | y (HKD) |
.plot(kind="barh") and .plot(kind="bar") are equivalent ways to choose these chart types. Horizontal bars often leave more room for long category names.
| Code | What it does in this example |
|---|---|
ax.set(title=..., xlabel=..., ylabel=...) |
A method of ax: sets the chart title and both axis labels together. Here, x shows Revenue (HKD); y shows Product category. |
plt.tight_layout() |
Adjusts spacing around the plot to help keep the title and labels from overlapping or being cut off. It does not change the data. |
plt.show() |
Displays the completed figure in the Python output. Call it after creating and formatting the chart. |
Order: create the chart and save ax → set title and labels → adjust spacing → display.
Axes is Matplotlib’s name for a plotting area; despite its plural spelling, one Axes object can hold this single bar chart. The assignment ax = totals.sort_values().plot.barh(…) stores the returned Axes so later methods can format that chart. ax.set() is a method of that object. Its title, xlabel and ylabel keyword arguments set three properties in one call; they serve the same labelling purposes as the plt.title(), plt.xlabel() and plt.ylabel() functions used earlier. The names title, xlabel and ylabel are parameters, not variables the student must define. plt.tight_layout() and plt.show() are pyplot functions. Tight layout adjusts subplot spacing; it is not a data-cleaning or scaling operation. Show displays the figure; it does not calculate the totals. Browser notebooks may also display figures automatically, but the explicit final show call makes the example clear and portable. Because these bars are horizontal, the numerical revenue scale is on x and categories are on y. For horizontal bars, the category labels are on y and revenue is measured along x; for vertical bars, the categories move to x and revenue is measured along y. Use matching xlabel and ylabel text when changing orientation. The code uses horizontal = True to run plot.barh(); changing this flag to False runs plot.bar() instead. Only one branch runs, so the cell produces one chart per run. rot=0 keeps the vertical chart’s category labels horizontal. The sorted totals remain Accessories 90, Stationery 520 and Gifts 620 HKD in both orientations.
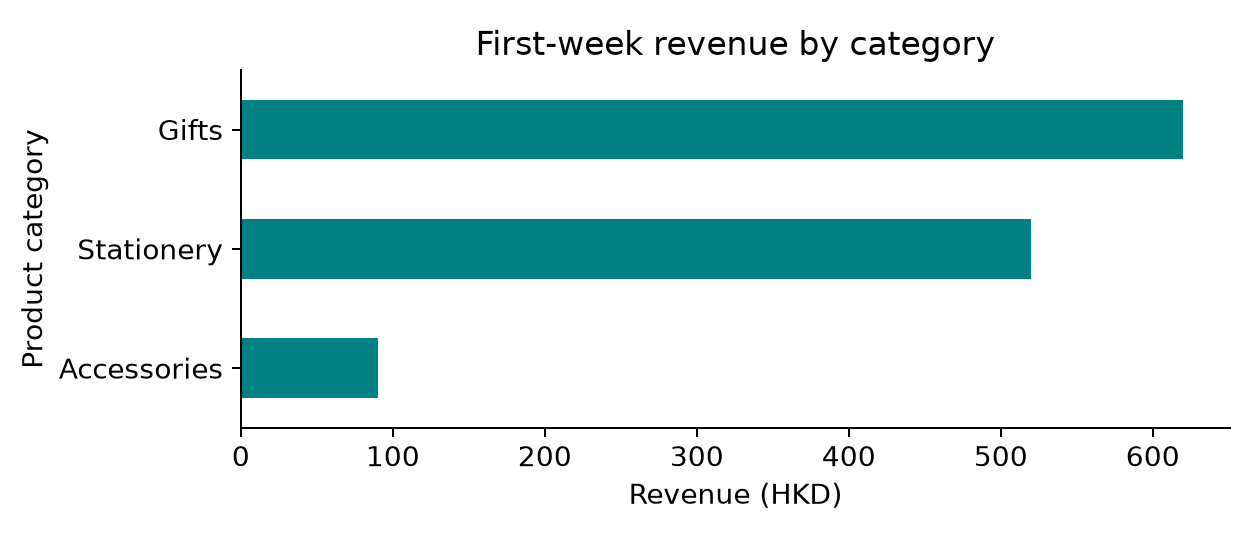
Try it: change horizontal = True to horizontal = False and run again. The bars become vertical and the axis labels swap. The totals stay the same: Accessories = 90, Stationery = 520, Gifts = 620 HKD.
.plot.barh() draws horizontal bars: categories on y and values on x. .plot.bar() draws vertical bars: categories on x and values on y. Change the axis labels to match; the underlying totals do not change.
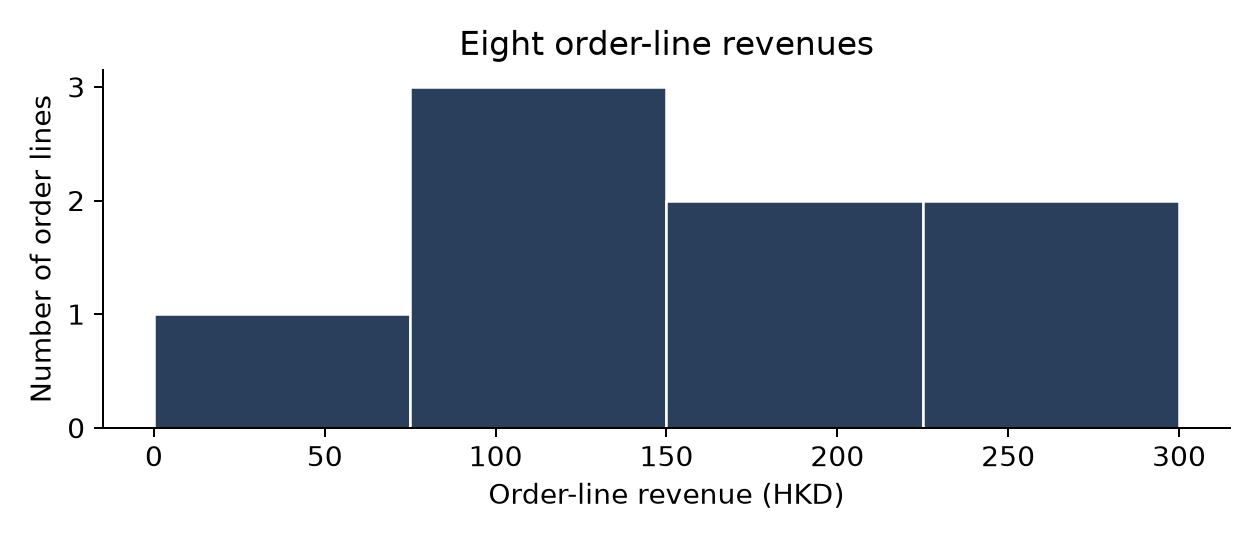
Histogram: Show the Order Distribution
A histogram groups numerical values into intervals. Change bins and see how the appearance changes. With only eight observations, avoid strong claims about distribution shape.
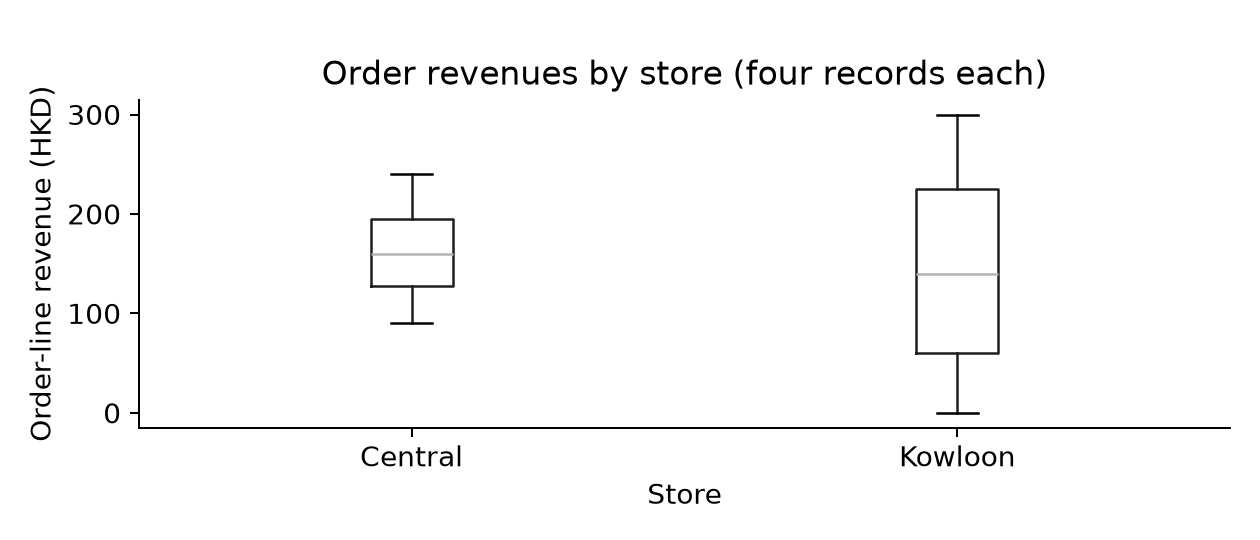
Box Plot: Compare Store Distributions
A box plot summarises a distribution with its median and quartiles. With small groups, inspect the original points as well. An unusual observation can be legitimate.
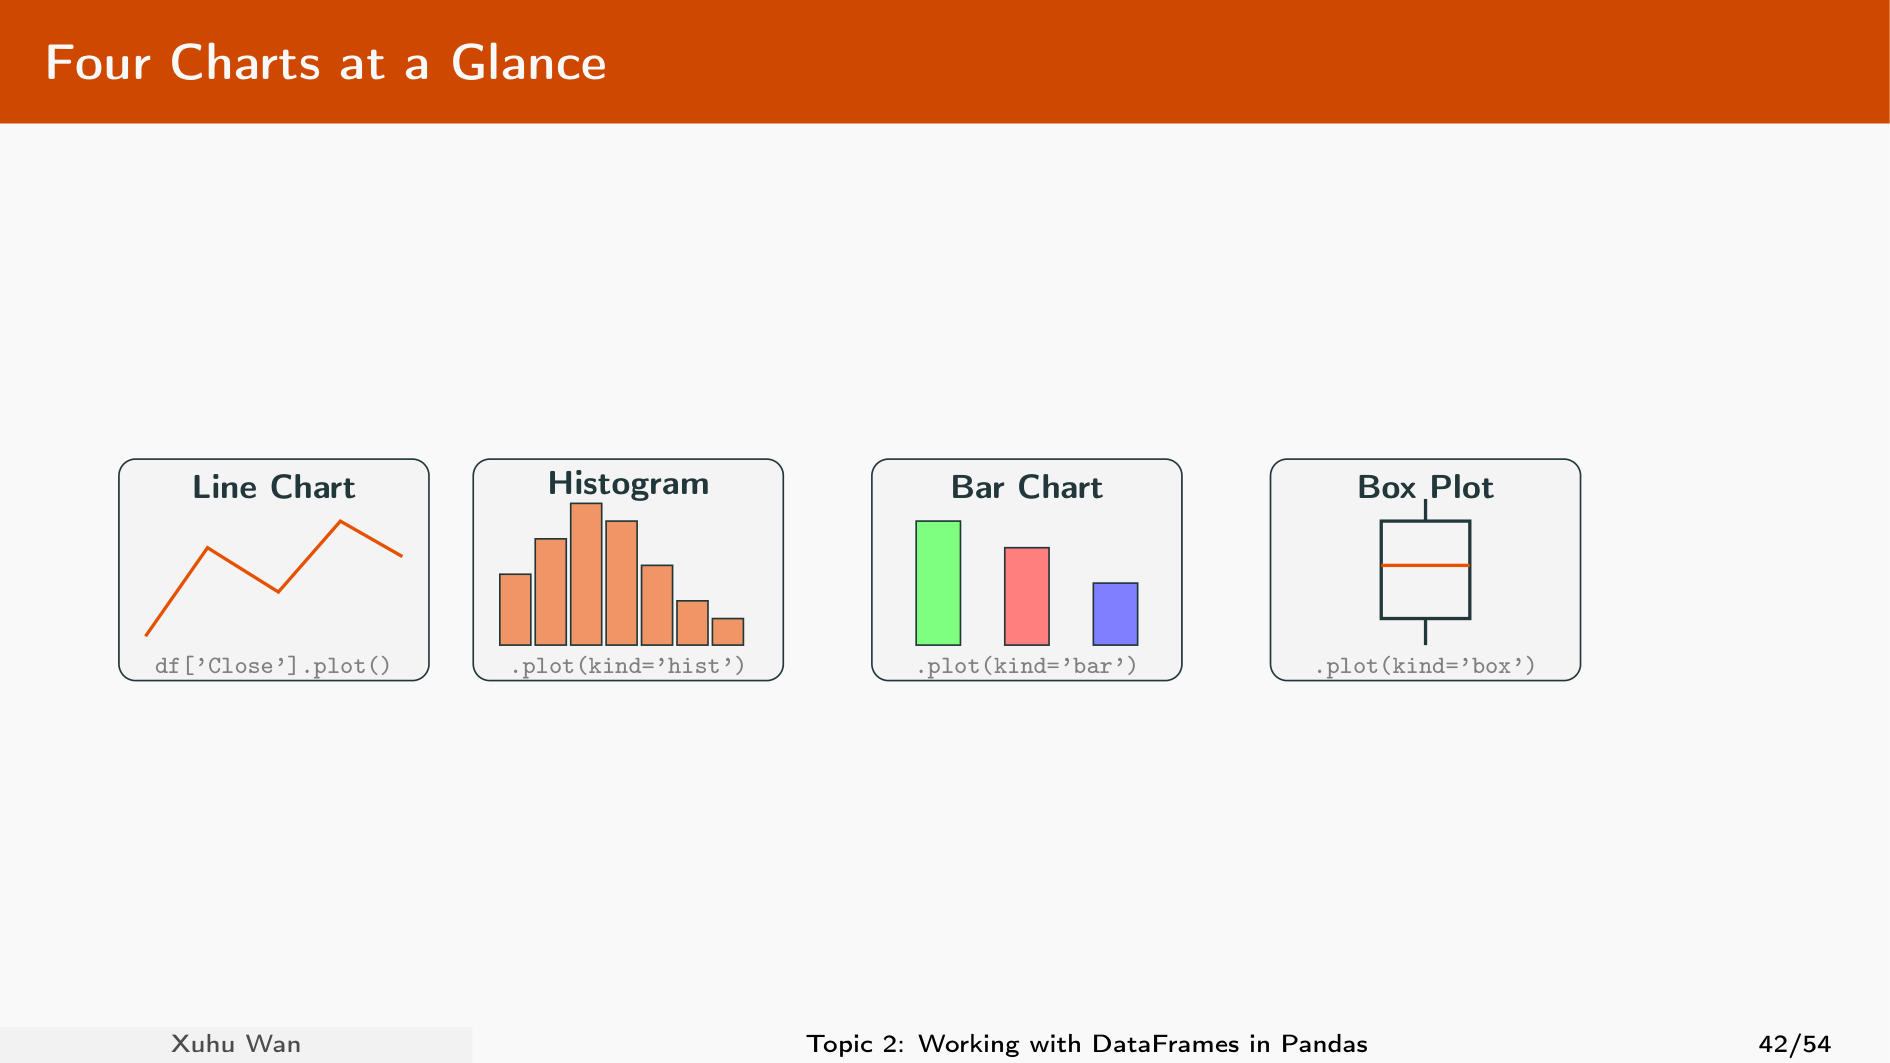
Four Chart Types at a Glance
Compare a line chart, histogram, bar chart, and box plot. Choose by the question: time order, numerical distribution, category comparison, or distribution summary.
A Conclusion Supported by the Table
In our eight classroom records, Gifts contributes HK$620 in revenue. This does not establish that its products are most profitable, that coupons caused larger orders, or that a particular budget transfer is optimal.
A defensible statement names the measure, records, and period. Repeat the selection for another category before making a comparison. Revenue and gross profit answer different questions. No coupon data appear in this table, so it cannot support a coupon-effect calculation. State what further information a manager would need before making a purchasing or marketing decision.
Work with ChatGPT: Check the Result
Ask ChatGPT to explain the code and its assumptions. Then run it, inspect row counts, and verify key numbers yourself. A fluent recommendation still needs evidence.
Useful prompt: “Explain which rows this code removes, how the denominator changes, and which business claims the output can support.”
In-Class Practice: Total or Average?
Use .loc to select Gifts revenue, then Accessories revenue. Print each count, sum, and mean separately. Put the two totals into a Series and draw a bar chart.
Expected: Gifts has 3 orders, total 300, mean 100. Accessories has 1 order, total 200, mean 200.
Section 6 Practice — Business Charts
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Totals by category
Warm-up. Use loc to select Gifts and Accessories separately; print total Revenue for each.
Write your answer, then run it.
2. Averages by category
Warm-up. Use loc to select each category separately; print its mean Revenue.
Write your answer, then run it.
3. Number of orders
Warm-up. Print the number of rows in each category.
Write your answer, then run it.
4. Available observations
Build your skills. Print group size and non-missing revenue counts.
Write your answer, then run it.
5. Several summaries
Build your skills. Select each category separately with loc. Print its revenue count, sum, and mean.
Write your answer, then run it.
6. Different rankings
Build your skills. Print the category with the largest total, then the one with the largest mean.
Write your answer, then run it.
7. A labelled bar chart
Build your skills. Plot total category revenue as a bar chart. Add a title and both axis labels.
Write your answer, then run it.
8. A labelled histogram
Challenge. Plot this order-revenue distribution using three bins. Add a title and both axis labels.
Write your answer, then run it.
9. Group profit as well as revenue
Challenge. Calculate profit and print group totals for both Revenue and Profit.
Write your answer, then run it.
10. A supported explanation
Challenge. Calculate total revenue and print a finding that names Gifts, its total, and this four-order sample. Avoid making a coupon claim.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Totals by category
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
accessories = df.loc[df["Category"] == "Accessories", "Revenue"]
print("Gifts:", gifts.sum())
print("Accessories:", accessories.sum())Expected output
Gifts: 300
Accessories: 200Select Gifts and Accessories separately with loc, then sum each selected Series.
2. Averages by category
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
accessories = df.loc[df["Category"] == "Accessories", "Revenue"]
print("Gifts:", gifts.mean())
print("Accessories:", accessories.mean())Expected output
Gifts: 100.0
Accessories: 200.0The mean uses observations within each group.
3. Number of orders
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
accessories = df.loc[df["Category"] == "Accessories", "Revenue"]
print("Gifts:", len(gifts))
print("Accessories:", len(accessories))Expected output
Gifts: 3
Accessories: 1len counts selected rows, not units sold.
4. Available observations
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Central", "Kowloon"], "Revenue": [100, None, 200]})
central = df.loc[df["Store"] == "Central", "Revenue"]
kowloon = df.loc[df["Store"] == "Kowloon", "Revenue"]
print("Central:", len(central), central.count())
print("Kowloon:", len(kowloon), kowloon.count())Expected output
Central: 2 1
Kowloon: 1 1Central has two rows but only one observed revenue.
5. Several summaries
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
accessories = df.loc[df["Category"] == "Accessories", "Revenue"]
print("Gifts:", gifts.count(), gifts.sum(), gifts.mean())
print("Accessories:", accessories.count(), accessories.sum(), accessories.mean())Expected output
Gifts: 3 300 100.0
Accessories: 1 200 200.0Select each category, then call count, sum, and mean separately.
6. Different rankings
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
accessories = df.loc[df["Category"] == "Accessories", "Revenue"]
totals = pd.Series({"Gifts": gifts.sum(), "Accessories": accessories.sum()})
means = pd.Series({"Gifts": gifts.mean(), "Accessories": accessories.mean()})
print(totals.idxmax())
print(means.idxmax())Expected output
Gifts
AccessoriesMore orders can outweigh a smaller average.
7. A labelled bar chart
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
import matplotlib.pyplot as plt

plt.rcParams.update({"font.size": 11})
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
accessories = df.loc[df["Category"] == "Accessories", "Revenue"]
totals = pd.Series({"Gifts": gifts.sum(), "Accessories": accessories.sum()})
ax = totals.plot.bar(color="#008080", rot=0, figsize=(6, 3))
ax.set(title="Revenue by category", xlabel="Category", ylabel="Revenue (HKD)")
print("Bar chart created.")
plt.tight_layout()
plt.show()Expected output
Bar chart created.Compare group totals with an explicitly labelled measure.
8. A labelled histogram
import pandas as pd
sales = pd.Series([80, 100, 120, 140, 300, 500])
import matplotlib.pyplot as plt
plt.rcParams.update({"font.size": 11})
ax = sales.plot.hist(bins=3, color="#2a3f5c", figsize=(6, 3))
ax.set(title="Order revenue distribution", xlabel="Revenue (HKD)", ylabel="Number of orders")
print("Histogram created.")
plt.tight_layout()
plt.show()Expected output
Histogram created.A histogram shows numerical intervals, rather than named groups.
9. Group profit as well as revenue
import pandas as pd

df = pd.DataFrame(
    {
        "Store": ["Central", "Central", "Kowloon"],
        "Revenue": [100, 200, 250],
        "Cost": [80, 150, 100],
    }
)
df["Profit"] = df["Revenue"] - df["Cost"]
central = df.loc[df["Store"] == "Central"]
kowloon = df.loc[df["Store"] == "Kowloon"]
print("Central:", central["Revenue"].sum(), central["Profit"].sum())
print("Kowloon:", kowloon["Revenue"].sum(), kowloon["Profit"].sum())Expected output
Central: 300 70
Kowloon: 250 150Central has greater revenue, while Kowloon has greater profit in these records.
10. A supported explanation
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
print(gifts.sum())
print("Gifts contributes HKD 300 in this four-order sample.")Expected output
300
Gifts contributes HKD 300 in this four-order sample.The statement is descriptive and limited to the available records.
Dates, Lags, and Changes over Time
Convert and organise dates, combine selected orders into daily totals, and distinguish previous values, next values, and changes.
A Date String and a Datetime Value
"2026-11-01" begins as text. pd.to_datetime() converts it to a datetime value. Convert dates before relying on date-specific operations.
pd.to_datetime() converts date text to datetime values. The first dtype describes the text column; the second describes the converted datetime column. The Sales values stay the same.
Set and Sort a Date Index
.set_index("Date") moves Date into the index. .sort_index() places records in chronological order. Neither step makes missing dates appear automatically.
Select Dates with loc
A sorted DatetimeIndex supports readable date ranges. Both endpoints are included. A partial date such as a month selects matching records.
Date Components: Column versus Index
For a datetime Series, use .dt.month or .dt.day_name(). For a DatetimeIndex, use .month or .day_name() directly. .dayofweek counts Monday as 0.
The dt accessor exposes date-specific operations on a Series. day_name() is a method with parentheses; month and dayofweek are attributes. The index already has datetime-specific attributes, so a DatetimeIndex does not use .dt.
Orders Become a Daily Sales Table
Two order lines on November 2 have revenues of HK$80 and HK$140. Use .loc to select that date and .sum() to calculate its daily total: HK$220. One order line and one day are different observation units.
The condition selects all order lines for one date. Selecting Revenue gives a Series; sum() adds its observed values. The first date has one order worth HK$240. The second has two orders worth HK$220 together. The final Series has one value per date. These records alone do not establish sales on unlisted dates.
Line Chart: Follow Time Order
Plot daily sales in chronological order. A line chart shows changes between consecutive dated observations; it does not establish a forecast.
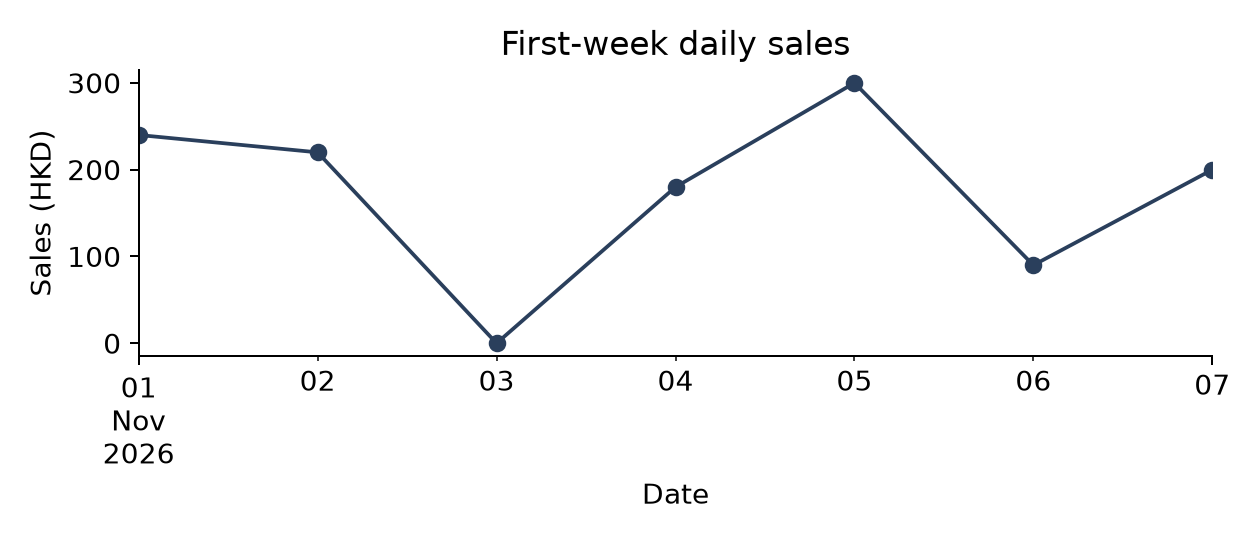
shift Moves Values Relative to Their Rows
.shift(1) moves values down one row, placing the previous observation beside the current one. The index stays unchanged. The first row shows NaN because it has no previous observation.
Read the row for November 2: Sales is 220 and Previous is 240, taken from November 1. The final sales value, 200, moves beyond the end and is absent from Previous. With gaps in the dates, the previous observation may be several calendar days earlier; shift(1) still moves by one row.
No. It moves values down one row. The first shifted value is missing because no earlier observation exists.
shift(-1): Bring the Next Observation to the Current Row
.shift(-1) moves values up one row. Each row receives the next observation; the index stays unchanged. The last row shows NaN because there is no next observation.
| Method | Direction | Value beside the current row | Missing boundary |
|---|---|---|---|
.shift(1) |
Down one row | Previous observation | First row |
.shift(-1) |
Up one row | Next observation | Last row |
At index 0, Next is 120, copied from index 1. At index 1, Next is 90. At index 2, Next is missing. The original Sales Series and its index remain unchanged. A negative argument chooses a later observation; it does not subtract one from a sales amount. This helps compare an observation with a later outcome, but that future value is not already known when forecasting at the current time.
From the next row, index 1. It moves values up one row, retains the index, and leaves the last row missing.
Absolute Change and Relative Change
Absolute change is current − previous. Relative change divides by the previous value. .pct_change() returns a fraction: 0.10 means 10%. Missing observations and zero denominators need attention.
The first relative change is missing. The second is 0.10 or 10%; the third is -0.10 or -10%. fill_method=None explicitly avoids implicitly filling unknown inputs in older pandas versions. If the previous value is zero, the relative change is undefined or infinite; a manager may need the absolute change instead.
Growth after Zero Sales
A move from HK$0 to HK$180 has an absolute increase of HK$180. It does not have a finite percentage increase. Retain only positive previous sales for this growth-rate denominator.
Start Growth with None to mark results not yet calculated. The Boolean condition keeps only rows whose previous sales are positive. Select current and previous sales from those same rows with loc, then calculate and assign their growth rates with loc. The first row and the row after zero remain missing: we never divide by their invalid denominators. On November 4 the dollar increase is 180, but the relative change from zero is undefined. A missing result can display as None or NaN, depending on dtype.
In-Class Practice: Yesterday and Today
Build a table with Sales, Previous, absolute change, and relative change for 100, 120, and 90 HKD. Show relative change as a percentage in a separate column.
Expected later changes: +20 HKD and +20%; −30 HKD and −25%. The initial changes are missing.
Section 7 Practice — Dates, Lags, and Changes over Time
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Convert date text
Warm-up. Convert Date to datetime and print the month numbers as a list.
Write your answer, then run it.
2. Chronological order
Warm-up. Set Date as the index, sort it, and print Sales values in chronological order.
Write your answer, then run it.
3. Inclusive date range
Warm-up. Print values from November 2 through November 4 inclusive.
Write your answer, then run it.
4. Weekday numbers
Build your skills. Print weekday numbers for Sunday 2026-11-01 and Monday 2026-11-02.
Write your answer, then run it.
5. Aggregate two orders
Build your skills. Aggregate revenue into daily totals and print them as a list.
Write your answer, then run it.
6. Previous observations
Build your skills. Print the previous values generated by shift(1).
Write your answer, then run it.
7. Absolute change
Build your skills. Print changes from the previous observation.
Write your answer, then run it.
8. Percentage change
Challenge. Print fractional changes multiplied by 100.
Write your answer, then run it.
9. Next observations
Challenge. Use shift(-1) to print the next Sales value at each row as a list.
Write your answer, then run it.
10. Avoid a zero denominator
Challenge. Calculate growth only when previous Sales > 0 and print the list.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Convert date text
import pandas as pd
df = pd.DataFrame({"Date": ["2026-11-01", "2026-12-01"]})
df["Date"] = pd.to_datetime(df["Date"])
print(list(df["Date"].dt.month))Expected output
[11, 12]Conversion enables date-specific attributes.
2. Chronological order
import pandas as pd
df = pd.DataFrame({"Date": ["2026-11-03", "2026-11-01", "2026-11-02"], "Sales": [0, 240, 220]})
df["Date"] = pd.to_datetime(df["Date"])
dated = df.set_index("Date").sort_index()
print(list(dated["Sales"]))Expected output
[240, 220, 0]The input row order is not necessarily chronological.
3. Inclusive date range
import pandas as pd
df = pd.DataFrame({
    "Date": ["2026-11-01", "2026-11-02", "2026-11-03", "2026-11-04",
             "2026-11-05", "2026-11-06", "2026-11-07"],
    "Sales": [240, 220, 0, 180, 300, 90, 200]
})
df["Date"] = pd.to_datetime(df["Date"])
daily = df.set_index("Date")["Sales"]
print(list(daily.loc["2026-11-02":"2026-11-04"]))Expected output
[220, 0, 180]Both dates are included in this label slice.
4. Weekday numbers
import pandas as pd
dates = pd.Series(pd.to_datetime(["2026-11-01", "2026-11-02"]))
print(list(dates.dt.dayofweek))Expected output
[6, 0]Monday is 0 and Sunday is 6.
5. Aggregate two orders
import pandas as pd
df = pd.DataFrame({"Date": pd.to_datetime(["2026-11-01", "2026-11-01", "2026-11-02"]), "Revenue": [100, 140, 220]})
nov1 = df.loc[df["Date"] == "2026-11-01", "Revenue"].sum()
nov2 = df.loc[df["Date"] == "2026-11-02", "Revenue"].sum()
print([nov1, nov2])Expected output
[240, 220]Both orders on November 1 contribute to its daily total.
6. Previous observations
import pandas as pd
sales = pd.Series([100.0, 120.0, 90.0])
print(list(sales.shift(1)))Expected output
[nan, 100.0, 120.0]A lag moves values, leaving the first entry without a predecessor.
7. Absolute change
import pandas as pd
sales = pd.Series([100.0, 120.0, 90.0])
print(list(sales - sales.shift(1)))Expected output
[nan, 20.0, -30.0]The change has the same HKD units as sales.
8. Percentage change
import pandas as pd
sales = pd.Series([100.0, 120.0, 90.0])
print(list((sales.pct_change(fill_method=None) * 100)))Expected output
[nan, 19.999999999999996, -25.0]The fractions 0.20 and -0.25 correspond to 20% and -25%.
9. Next observations
import pandas as pd
sales = pd.Series([100.0, 120.0, 90.0])
print(list(sales.shift(-1)))Expected output
[120.0, 90.0, nan]Values move up one row while the index stays fixed. The last row has no next observation.
10. Avoid a zero denominator
import pandas as pd
sales = pd.Series([100.0, 0.0, 180.0, 198.0])
comparison = pd.DataFrame({"Sales": sales, "Previous": sales.shift(1)})
comparison["Growth"] = None
valid = comparison["Previous"] > 0
current = comparison.loc[valid, "Sales"]
previous = comparison.loc[valid, "Previous"]
comparison.loc[valid, "Growth"] = (current - previous) / previous
print(list(comparison["Growth"]))Expected output
[None, -1.0, None, 0.1]Growth from zero is undefined; an absolute increase can still be reported.
Rolling and Cumulative Methods
Explain what a moving window includes and distinguish recent-period statistics from running totals and compounded growth.
A Three-Observation Moving Average
For sales 100, 200, 300, 400, 500, the first complete three-value window is [100, 200, 300], with mean 200. The next window drops 100 and adds 400.
The default three-observation window needs three observed values.
Interactive Window: Which Values Are Included?
Change the window size and ending observation. Highlighted values contribute to the mean. Reproduce the selected calculation in the Python box.
| Position | 0 | 1 | 2 | 3 | 4 |
|---|---|---|---|---|---|
| Sales (HKD) | 100 | 200 | 300 | 400 | 500 |
Window [100, 200, 300]: mean = 200.00 HKD
Chart: Sales and a Moving Average
A rolling mean smooths short-term variation. Change the window from 3 to 2 or 4, then compare the curve and the number of initial missing values.
Create the dates first: pd.date_range(start="2026-11-01", periods=7, freq="D") creates a DatetimeIndex containing seven consecutive calendar dates, November 1 through November 7.
| Argument | Meaning in this example |
|---|---|
start="2026-11-01" |
The first date is November 1, 2026. |
periods=7 |
Create seven dates, including the first date. |
freq="D" |
Move forward one calendar day each time; D means daily. |
Save these dates as dates. Using index=dates pairs each sales value with its date. This function creates dates; it does not create sales values or fill missing sales.
Pandas date_range() is a function that creates a regularly spaced sequence of datetime values, returned as a DatetimeIndex. With the start, periods and daily frequency used here, the sequence is November 1, 2, 3, 4, 5, 6 and 7. This avoids typing seven date strings separately. The seven sales values are supplied independently to pd.Series and aligned by position with the seven dates. The sequence represents calendar days, including weekends. Creating a date index is different from converting existing date text with pd.to_datetime().
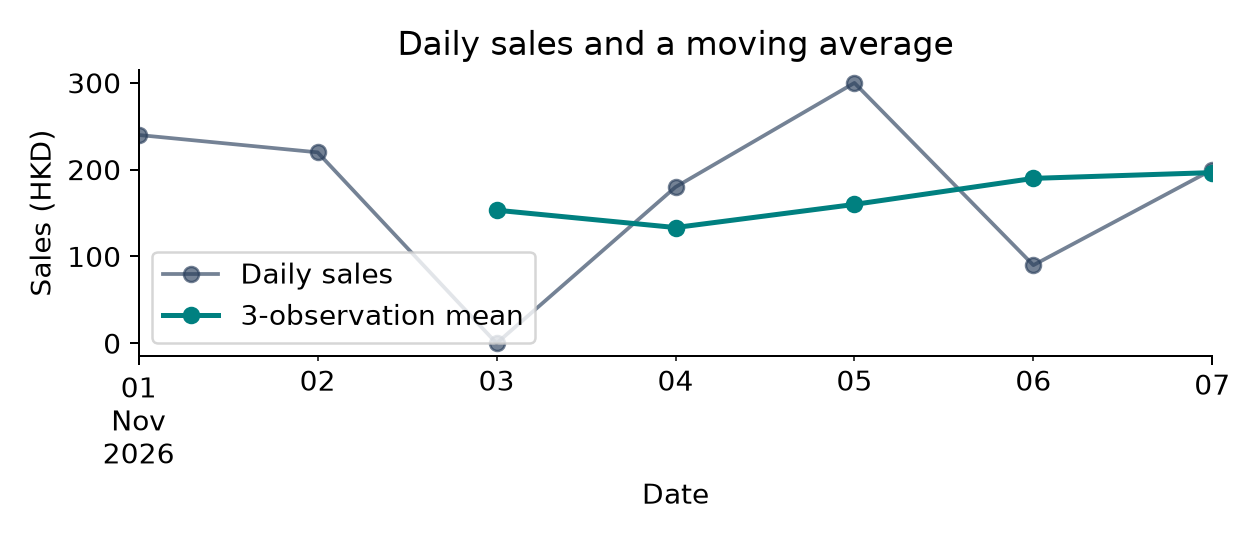
Rolling Sums and Standard Deviations
A rolling sum measures recent total sales. A rolling standard deviation describes recent variation. Both need a defined window and units.
Incomplete Windows and min_periods
min_periods=1 allows an early mean using the available values. That first output is a one-observation mean, even though the maximum window size is 3.
With an integer window, min_periods defaults to the window size. An internal missing entry can also stop a full-window calculation from meeting the required count. Allowing early values changes the amount of information behind each result; it does not create missing observations.
Three Observations versus Three Calendar Days
On irregular dates, .rolling(3) and .rolling("3D") use different windows. The default right-closed time window excludes an observation exactly at its left boundary.
At November 5, the last three rows are November 1, 2, and 5, giving mean 200. The default three-calendar-day window is (November 2, November 5], containing only November 5 here, giving mean 300. Time-based windows default to min_periods=1. An integer window of 20 stock-market observations usually represents 20 trading observations, not 20 calendar days.
Cumulative Sales: Keep Adding from the Start
.cumsum() retains all observations from the beginning through the current row. It answers “How much so far?” rather than “How much in the recent window?”
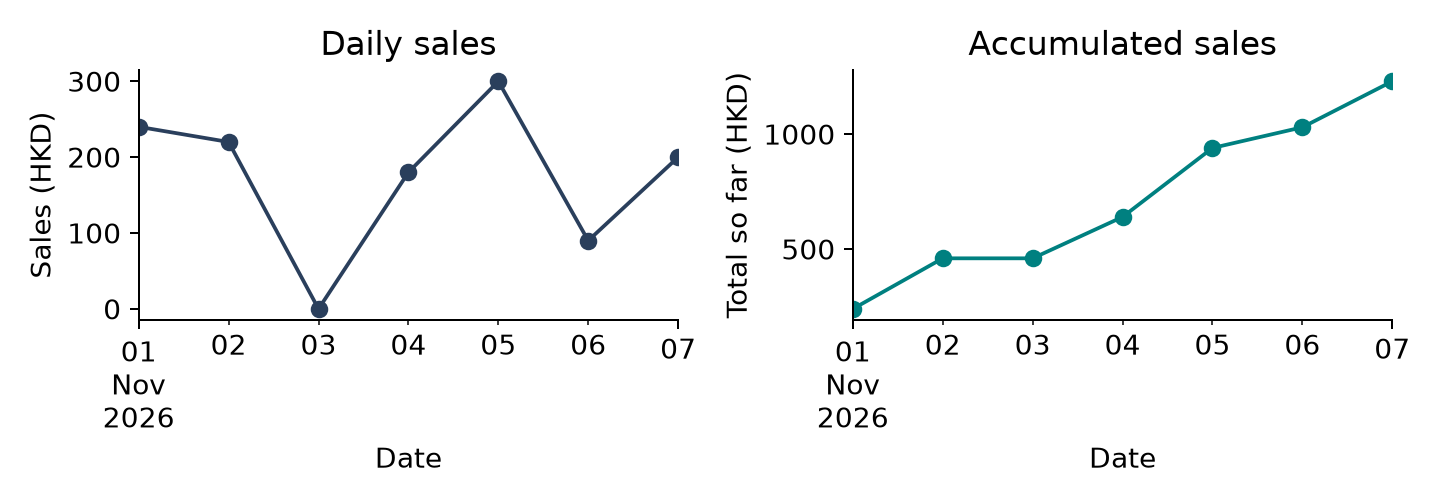
Chart: Daily and Accumulated Sales
Compare sales on each day with sales accumulated so far using two separate charts. Use the familiar Series methods .plot.bar() and .plot(), with plt.title(), plt.xlabel(), and plt.ylabel() to label each chart.
The seven short date strings are labels, listed in chronological order. The first chart plots the original daily values as bars. The second first uses cumsum() to calculate the running totals, then plots that Series as a line. A separate plt.figure() starts each chart. The pyplot title and axis-label functions, tight_layout(), and show() have the same roles as in Chapter 1. November 3 has zero sales, so its bar has zero height and the accumulated total stays at HK$460. The final running total is HK$1,230. These observations are nonnegative; with negative entries such as refunds, a cumulative total could fall.
Cumulative Maximum and Minimum
Cumulative means using every observation from the first row through the current row.
.cummax()gives the cumulative maximum: the highest value observed so far..cummin()gives the cumulative minimum: the lowest value observed so far.
A cumulative maximum can stay unchanged when the current sales value falls; a cumulative minimum can stay unchanged when the current sales value rises.
On November 2, sales is 220: the cumulative maximum is still 240, while the cumulative minimum becomes 220. On November 3, sales is zero: the cumulative maximum stays 240 and the cumulative minimum becomes zero. Later sales of 180 do not change either record. On November 5, sales of 300 raises the cumulative maximum to 300; the cumulative minimum remains zero. Each output uses all observations since the first row, rather than a recent rolling window.
Check November 4: Sales = 180, CumulativeMax = 240, CumulativeMin = 0.
Compounding Uses Growth Factors
.cumprod() means cumulative product: multiply all values from the first row through the current row. It returns one product for each row.
For [2, 3, 4], the cumulative products are [2, 2 × 3, 2 × 3 × 4] = [2, 6, 24].
For returns, first calculate each growth factor as 1 + return. Then use .cumprod() to multiply the factors. Subtract 1 from the product to obtain the cumulative return.
| Row | Return | Growth factor | Cumulative product | Cumulative return |
|---|---|---|---|---|
| 0 | +10% | 1.10 | 1.10 | 1.10 − 1 = +10% |
| 1 | −10% | 0.90 | 1.10 × 0.90 = 0.99 | 0.99 − 1 = −1% |
| 2 | +10% | 1.10 | 1.10 × 0.90 × 1.10 = 1.089 | 1.089 − 1 = +8.9% |
Multiply the growth factors; do not add the returns.
The cum part means cumulative, and prod means product: multiplication. Series.cumprod() includes the first value, then extends the product by one value at each subsequent row. In the code, returns contains fractions, so 0.10 means 10% and -0.10 means -10%. Adding 1 converts them to factors of 1.10, 0.90 and 1.10. cumulative_product stores the Series returned by factors.cumprod(). Each product describes the value of one starting dollar after the returns up to that row. The product 0.99 is a value ratio, not a 99% return: subtracting 1 gives -0.01, or -1%. The final product 1.089 gives a cumulative return of 0.089, or 8.9%. Both intermediate products and returns are printed so the two quantities are visible.
It multiplies growth factors cumulatively from the first row through each current row. The resulting product is a value ratio; subtract 1 to obtain the cumulative return. For +10% then −10%, 1.10 × 0.90 = 0.99, so the return is 0.99 − 1 = −0.01, or −1%.
From Prices to Cumulative Returns
The first price has no return from a previous observation. Set the known starting value to 100 for this complete-price example, then compound subsequent growth factors.
Setting the first growth factor to 1 establishes the starting level rather than imputing an unknown interior return. Do not blanket-fill missing returns with zero without a reason. For the complete price sequence, the compounded result must agree with price / starting price − 1, providing an independent check.
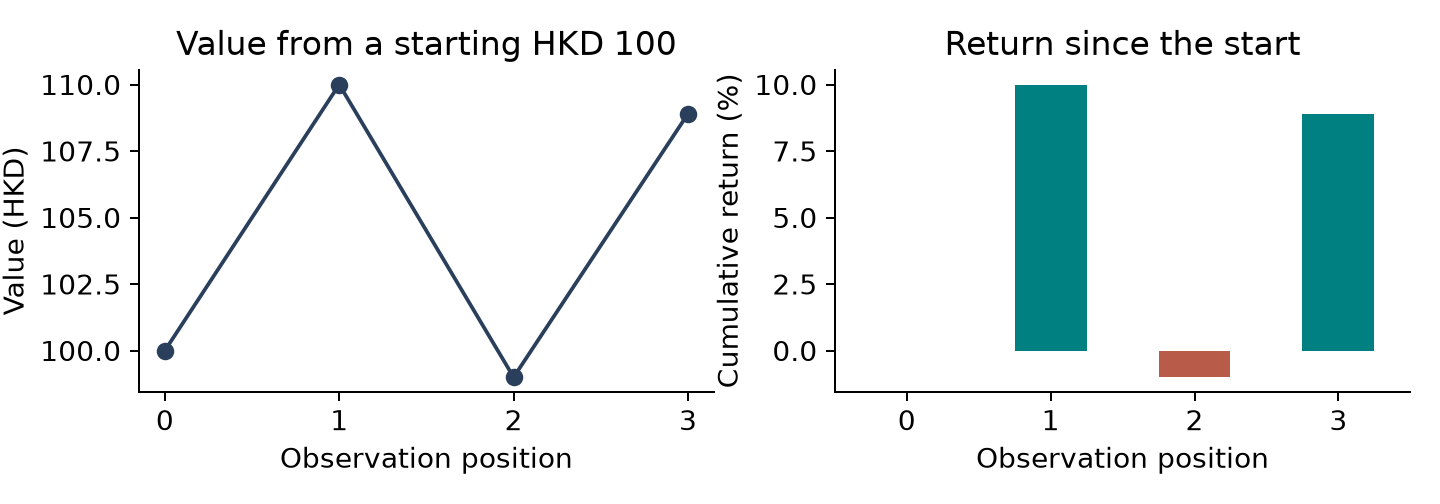
Financial Example: S&P 500 Data
Load the course’s 2020 S&P 500 snapshot. Select dates, calculate fractional returns, and compare a price moving average with a returns standard deviation.
This HTTPS file is the local course snapshot, so the browser does not need to install the isom2600 package or fetch live Yahoo Finance data. The values are index levels and share-volume units, not store sales. Keep the price moving average and returns standard deviation separate: price variation and return variation have different units and meanings.
Financial Chart: Prices and Return Variation
Read two separate charts made with the familiar .plot() method:
- Closing level and moving average: the blue line shows the S&P 500 closing level on each date. The teal line shows the mean of the most recent 20 observations. The vertical axis measures index level.
- Variation in daily returns: the red line shows the standard deviation of the most recent 20 returns. Multiplying by 100 displays it as a percentage. A higher value means the recent daily percentage changes varied more.
Change window = 20 to window = 10, then run again and compare both charts.
Calculate the Series before plotting them: moving_average = close.rolling(window).mean() summarizes index levels, while return_sd_percent = returns.rolling(window).std() * 100 summarizes variation in daily fractional returns. Each plt.figure() starts a separate chart. Two ordinary plot calls place the closing level and its moving average together on the first chart; their label arguments and plt.legend() identify the lines. The second chart contains only return_sd_percent. Titles and units identify what each picture measures. A higher closing level and a higher return standard deviation are different statements: the second does not say that prices are rising. The window counts recorded observations, not calendar days. The initial incomplete windows have missing results, so the summary lines begin later. Changing the window changes the calculation and the labels automatically; a shorter historical window is not evidence of a profitable trading rule.
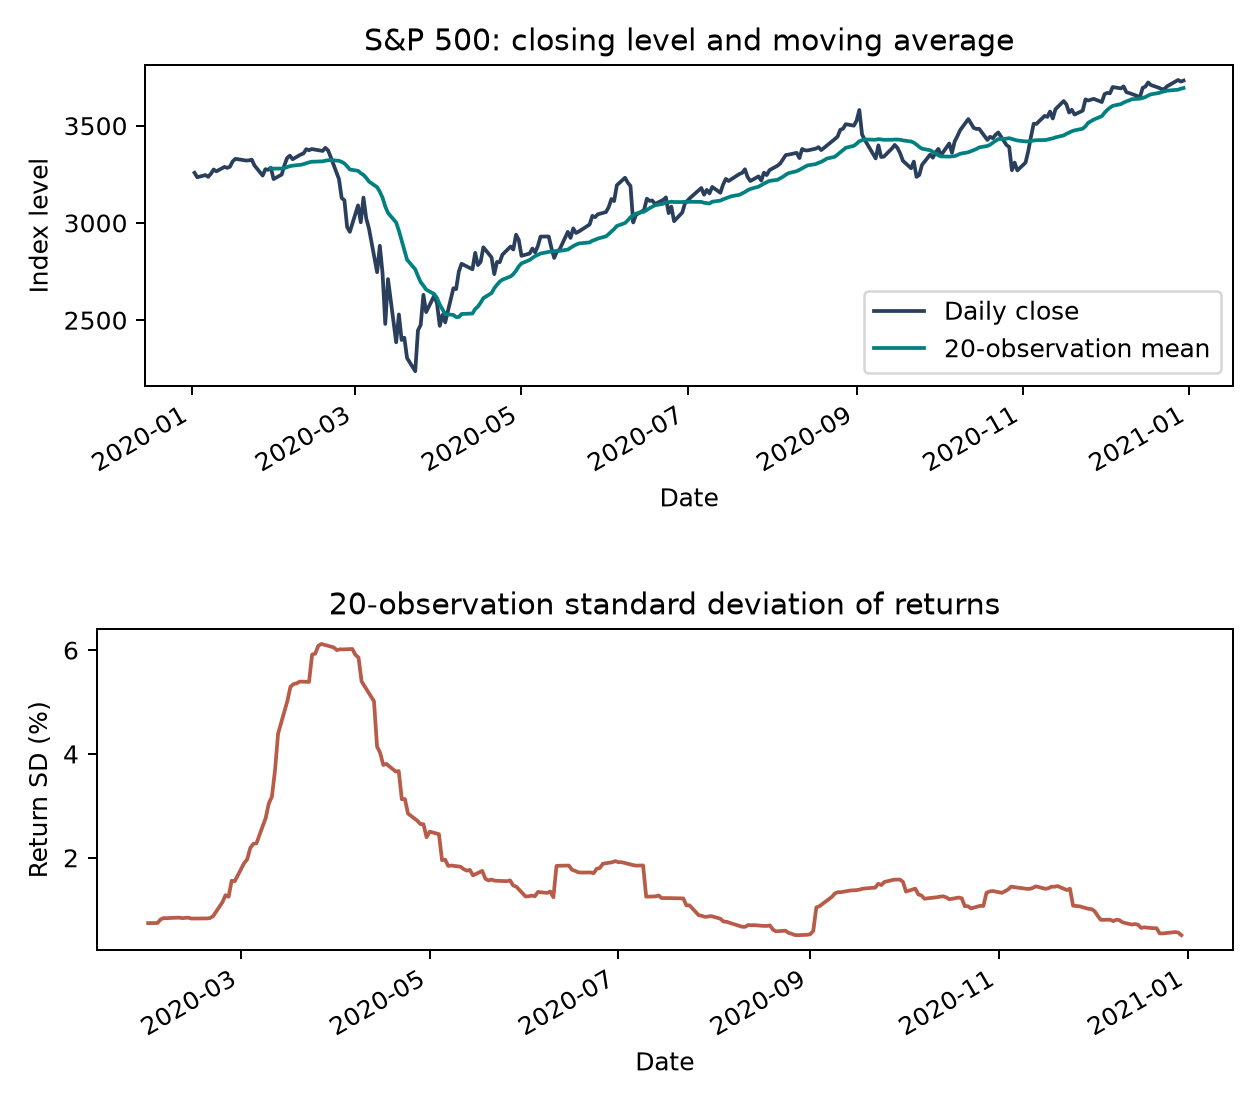
Extension: A Running Peak and Drawdown
Drawdown compares the current price with its highest value so far: price / running peak − 1. It is zero at a peak and negative below that peak.
At price 99 after a peak of 110, drawdown is -10%. The minimum drawdown in this example is -0.10; its magnitude is 10%. Keep the sign convention explicit. This optional finance application uses the same cummax concept as the highest daily sales so far.
Rolling and Cumulative Answer Different Questions
Compare the last three observations with all observations so far. Select a rolling sum for recent sales; select a cumulative sum for progress since the beginning.
In-Class Practice: Recent Sales and Total Sales
Compute the three-observation rolling mean and cumulative sales. Print the final values and explain why they answer different questions.
Expected final rolling mean: 400 HKD per observation. Expected cumulative total: 1500 HKD.
Section 8 Practice — Rolling and Cumulative Methods
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. A moving mean
Warm-up. Print the three-observation rolling means as a list.
Write your answer, then run it.
2. Recent total
Warm-up. Print the final three-observation rolling sum.
Write your answer, then run it.
3. Early windows
Warm-up. Print rolling means with window 3 and min_periods=1.
Write your answer, then run it.
4. Cumulative sales
Build your skills. Print cumulative sales as a list.
Write your answer, then run it.
5. Cumulative maximum
Build your skills. Print the cumulative maximum of these sales.
Write your answer, then run it.
6. Combined growth
Build your skills. Print the combined return of +10% and −10%.
Write your answer, then run it.
7. Rows or calendar days
Build your skills. For November 5, print the three-row mean and three-day mean.
Write your answer, then run it.
8. Plot a moving average
Challenge. Plot the original sales and their three-observation mean with a legend, title, and both axis labels.
Write your answer, then run it.
9. Growth from complete prices
Challenge. Calculate cumulative return from the first price and print the values. Use price / first price − 1.
Write your answer, then run it.
10. Choose the right accumulation
Challenge. Print the final three-observation sum, total since the start, and cumulative minimum.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. A moving mean
import pandas as pd
sales = pd.Series([100, 200, 300, 400, 500])
print(list(sales.rolling(3).mean()))Expected output
[nan, nan, 200.0, 300.0, 400.0]Two initial windows are incomplete.
2. Recent total
import pandas as pd
sales = pd.Series([100, 200, 300, 400, 500])
print(sales.rolling(3).sum().iloc[-1])Expected output
1200.0The final window includes 300, 400, and 500.
3. Early windows
import pandas as pd
sales = pd.Series([100, 200, 300, 400])
print(list(sales.rolling(3, min_periods=1).mean()))Expected output
[100.0, 150.0, 200.0, 300.0]Early averages use fewer than three observations.
4. Cumulative sales
import pandas as pd
sales = pd.Series([100, 200, 300, 400])
print(list(sales.cumsum()))Expected output
[100, 300, 600, 1000]Each result retains all observations from the start.
5. Cumulative maximum
import pandas as pd
sales = pd.Series([100, 80, 120, 90])
print(list(sales.cummax()))Expected output
[100, 100, 120, 120]The cumulative maximum remains 120 when the final observation falls to 90.
6. Combined growth
import pandas as pd
returns = pd.Series([0.10, -0.10])
combined = (1 + returns).cumprod() - 1
print(combined.iloc[-1])Expected output
-0.009999999999999898Compounding gives −1%, not zero. Python may display a value close to −0.01 because decimal fractions are stored as floating-point numbers.
7. Rows or calendar days
import pandas as pd

sales = pd.Series(
    [100.0, 200.0, 300.0, 400.0],
    index=pd.to_datetime(["2026-11-01", "2026-11-02", "2026-11-05", "2026-11-06"]),
)
print(sales.rolling(3).mean().loc["2026-11-05"])
print(sales.rolling("3D").mean().loc["2026-11-05"])Expected output
200.0
300.0The default three-day window excludes the observation exactly at its left boundary.
8. Plot a moving average
import pandas as pd
sales = pd.Series([100, 200, 300, 400, 500])
import matplotlib.pyplot as plt
plt.rcParams.update({"font.size": 11})
ax = sales.plot(marker="o", label="Sales", color="#2a3f5c", figsize=(6, 3))
sales.rolling(3).mean().plot(ax=ax, label="Mean3", color="#008080")
ax.set(title="Sales and recent average", xlabel="Observation position", ylabel="Sales (HKD)")
ax.legend()
print("Moving-average chart created.")
plt.tight_layout()
plt.show()Expected output
Moving-average chart created.The moving curve begins only when the full window is available.
9. Growth from complete prices
import pandas as pd
prices = pd.Series([100.0, 110.0, 99.0, 108.9], name="Price")
print(list((prices / prices.iloc[0] - 1)))Expected output
[0.0, 0.10000000000000009, -0.010000000000000009, 0.08899999999999997]This direct price-ratio calculation checks the compounded path. Small floating-point differences in the printed decimals do not change the calculation.
10. Choose the right accumulation
import pandas as pd
sales = pd.Series([100, 200, 300, 400, 500])
print(sales.rolling(3).sum().iloc[-1])
print(sales.cumsum().iloc[-1])
print(sales.cummin().iloc[-1])Expected output
1200.0
1500
100Recent total, accumulated total, and historical minimum are different measures.
Chapter Summary
| Business task | Main tools |
|---|---|
| Inspect a table | .shape, .dtypes, .head(), .info() |
| Select records | [], .loc[], .iloc[], Boolean masks |
| Handle missing entries | .isna(), .notna(), .dropna(), .fillna() |
| Create measures | column arithmetic, .copy(), .loc assignment |
| Rank and combine steps | .sort_values(), axis, ascending=False, short method chains |
| Explore and compare | .describe(), .value_counts(), .corr(), conditional .loc[] |
| Plot business results | .plot(), bar, histogram, box, scatter |
| Organise time | pd.to_datetime(), .shift(1), .shift(-1), .pct_change() |
| Track recent and running results | .rolling(), .cumsum(), .cummax(), .cummin(), .cumprod() |
Before trusting an output, name the observation, units, retained records, and denominator. Attributes use no parentheses; methods use parentheses; loc and iloc use square brackets. A selected column is a Series, while selecting a list of columns preserves a DataFrame. Missing values are different from recorded zeros. A rolling window uses a recent subset, while a cumulative operation begins at the start.
Check yourself: Can you explain the code, predict its output, and support a business conclusion with the actual numbers? Next: Chapter 3, Predicting with Linear Regression.
Quiz Review
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
Question 1
The manager needs the Price column as a two-dimensional table. Print its type name and shape.
Write your answer, then run it.
Question 2
Print the Price value in the third row by numerical position, then print rows B through D using their labels.
Write your answer, then run it.
Question 3
The purchasing manager needs Central records with at least three units. Print only Store and Units for those records.
Write your answer, then run it.
Question 4
Report the total observed Sales and the number of records used. Preserve the recorded zero and exclude unknown Sales.
Write your answer, then run it.
Question 5
Create Revenue and ProductCost, then report total gross profit for these records.
Write your answer, then run it.
Question 6
These orders include one large transaction. Print the mean and median, then state which better describes the middle observation.
Write your answer, then run it.
Question 7
Print category totals and category means. Identify the category contributing the larger total and the category with the larger average.
Write your answer, then run it.
Question 8
Arrange these records chronologically and print percentage changes from the previous observation.
Write your answer, then run it.
Question 9
A manager asks for the recent average and the total accumulated so far. Print the final three-observation mean and cumulative total.
Write your answer, then run it.
Question 10
An investment increases 10% and then decreases 10%. Starting at HKD 100, calculate and print the ending value and total percentage return. Explain why adding the two rates fails.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
Question 1
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
result = df[["Price"]]
print(type(result).__name__)
print(result.shape)Expected output
DataFrame
(4, 1)A list of column names preserves a DataFrame.
Question 2
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
print(df.iloc[2, 2])
print(df.loc["B":"D"])Expected output
35
     Store  Units  Price
B  Kowloon      1     80
C  Central      4     35
D Kowloon 3 60Positional counting starts at zero; the label slice includes both endpoints.
Question 3
import pandas as pd
df = pd.DataFrame({"Store": ["Central", "Kowloon", "Central", "Kowloon"],
                   "Units": [2, 1, 4, 3], "Price": [120, 80, 35, 60]},
                  index=["A", "B", "C", "D"])
mask = (df["Store"] == "Central") & (df["Units"] >= 3)
print(df.loc[mask, ["Store", "Units"]])Expected output
     Store  Units
C Central 4The row condition and requested output columns are separate selections.
Question 4
import pandas as pd
df = pd.DataFrame({"Order": ["A", "B", "C", "D"],
                   "Sales": [100, None, 0, 300],
                   "Rating": [4.0, 5.0, None, 3.0]})
observed = df.dropna(subset=["Sales"])
print(observed["Sales"].sum())
print(len(observed))Expected output
400.0
3Unknown ratings do not prevent an observed-sales calculation.
Question 5
import pandas as pd
df = pd.DataFrame({"Units": [2, 3, 1], "Price": [120, 40, 90], "UnitCost": [70, 22, 50]})
df["Revenue"] = df["Units"] * df["Price"]
df["ProductCost"] = df["Units"] * df["UnitCost"]
print((df["Revenue"] - df["ProductCost"]).sum())Expected output
194Gross profit subtracts product cost; other expenses remain outside this measure.
Question 6
import pandas as pd
sales = pd.Series([80, 100, 120, 140, 1000])
print(sales.mean())
print(sales.median())
print("The median describes the middle observation.")Expected output
288.0
120.0
The median describes the middle observation.The large transaction raises the mean.
Question 7
import pandas as pd

df = pd.DataFrame(
    {
        "Category": ["Gifts", "Gifts", "Gifts", "Accessories"],
        "Revenue": [100, 100, 100, 200],
    }
)
gifts = df.loc[df["Category"] == "Gifts", "Revenue"]
accessories = df.loc[df["Category"] == "Accessories", "Revenue"]
totals = pd.Series({"Gifts": gifts.sum(), "Accessories": accessories.sum()})
means = pd.Series({"Gifts": gifts.mean(), "Accessories": accessories.mean()})
print(totals)
print(means)
print(totals.idxmax(), means.idxmax())Expected output
Gifts          300
Accessories    200
dtype: int64
Gifts          100.0
Accessories    200.0
dtype: float64
Gifts AccessoriesGroup size explains why the rankings differ.
Question 8
import pandas as pd

df = pd.DataFrame(
    {"Date": ["2026-11-03", "2026-11-01", "2026-11-02"], "Sales": [90.0, 100.0, 120.0]}
)
df["Date"] = pd.to_datetime(df["Date"])
dated = df.set_index("Date").sort_index()
print(list((dated["Sales"].pct_change(fill_method=None) * 100)))Expected output
[nan, 19.999999999999996, -25.0]The dates must be ordered before a previous-observation calculation.
Question 9
import pandas as pd
sales = pd.Series([100, 200, 300, 400, 500])
print(sales.rolling(3).mean().iloc[-1])
print(sales.cumsum().iloc[-1])Expected output
400.0
1500Recent average is 400 per observation; the accumulated total is 1500.
Question 10
import pandas as pd
returns = pd.Series([0.10, -0.10])
factors = (1 + returns).cumprod()
print(100 * factors.iloc[-1])
print((factors.iloc[-1] - 1) * 100)
print("The second rate applies to the changed value.")Expected output
99.00000000000001
-0.9999999999999898
The second rate applies to the changed value.The ending value is 99 and combined return is -1%. Small floating-point differences in the printed decimals do not change these results.