Chapter 1 — Pandas Essentials for Business Data
What This Chapter Covers
Use Python tools to select business data, calculate summaries, draw charts, and interpret probabilities. The lecture emphasis is reading code and explaining results.
The course outline names List, Array, Pandas Series, and Matplotlib. We introduce modules before using the libraries, then retain a short SciPy probability application. Chapter 0 supplies variables, conditions, loops, and functions. A full Colab project will be developed separately.
Chapter Roadmap
| Section | What you will learn |
|---|---|
| 1. Lists | Select, transform, and filter values |
| 2. Modules and Imports | Packages, installation, aliases, import forms |
| 3. NumPy Arrays | Calculate with many numbers at once |
| 4. Pandas Series | Label and summarize business data |
| 5. Matplotlib | Create and explain charts |
| 6. SciPy Probability | Normal CDF and PPF |
Lists and Comprehensions
Select values, transform prices, filter records, and pair matching observations.
Lists: An Ordered Collection
A list stores several values under one name. Items keep their order. Square brackets create the list; commas separate items.
This is a short Chapter 0 recap. The order lets us refer to the first, second, or last dish. A list can contain strings, numbers, or other objects.
The number of items, not the number of letters in their names.
Indexing and Slicing
Indexing selects one item. Python starts at position 0; -1 selects the last item. A slice includes its start and excludes its stop.
Predict the slice first. Change it to dishes[:2] and explain the result.
No. dishes[1:3] includes positions 1 and 2.
List Methods: A Short Recap
A list is an object. A method is a function belonging to an object: write object.method(...). The dot looks up the method, and () calls it. append("Milk Tea") adds one item; count("Milk Tea") counts matching items; pop() removes and returns the last item when called without an argument.
In dishes.append(“Milk Tea”), dishes is the object, append is its method, and “Milk Tea” is an argument. Some methods change the object (append and pop), while others return information (count). append returns None, so do not replace dishes with dishes.append(…). len(dishes) is a separate built-in function; a normal list does not have a size or shape attribute. Later, NumPy arrays and Pandas Series provide descriptive attributes as well as methods.
Compare dishes.count("Milk Tea") with len(dishes): the first calls a list method to count one value; the second calls a built-in function to count all items.
A method belongs to the list and is called after a dot, as in dishes.count(“Milk Tea”). len(dishes) is a separate built-in function receiving the list as its argument.
A Loop Builds a New List
Every dish price rises by HK$2. Start with an empty list, visit each old price, and append the new price.
The original prices list is unchanged.
A Comprehension Transforms Values
A list comprehension builds a new list in one expression. Read [price + 2 for price in prices] as “for each price, calculate price + 2.”
Compare this with the preceding loop. The expression before for gives the new value; the part after in supplies the original items.
price + 2. The for part tells Python which items to visit.
A Comprehension Filters Values
An if after the for part keeps only matching items. The result may be shorter than the original list.
Change the cutoff from 50 to 40. Which items enter the result?
It keeps items whose condition is True and excludes the others.
A Comprehension Assigns a Label
An if ... else before the for part produces a value for every item. Each price receives a label; no item is removed.
Filtering selects some prices. A conditional expression classifies every price.
No. It produces one label per original item.
zip: Pair Corresponding Items
zip pairs items in the same positions. for count, bill in ... gives names to the two values in each pair. Inputs should describe matching dishes.
A pair such as (85, 42) is a tuple, an ordered group of values. Ordinary zip stops at its shortest input. Check equal lengths before combining records.
An unmatched record can disappear because ordinary zip stops at the shortest input.
In-Class Practice: Filter or Label?
Print (1) prices at least HK$50 and (2) one Premium/Regular label per price. Explain why the result lengths differ.
Checkpoint: two prices pass the filter; all four receive labels.
Section 1 Practice — Lists and Comprehensions
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Read the first item
Warm-up. Print the first dish and the number of dishes.
Write your answer, then run it.
2. Select a range
Warm-up. Print the last dish, then a list containing only Char Siu and Toast.
Write your answer, then run it.
3. Add and remove
Warm-up. Append Toast; pop the first item. Print the removed item and remaining list.
Write your answer, then run it.
4. Raise every price
Build your skills. Use a comprehension to add HK$3 to every price. Print the new list.
Write your answer, then run it.
5. Keep affordable dishes
Build your skills. Keep prices strictly below HK$50 using a comprehension.
Write your answer, then run it.
6. Classify prices
Build your skills. Print one Premium label for prices at least 50, otherwise Regular.
Write your answer, then run it.
7. Calculate paired revenues
Build your skills. Use zip to pair counts with bills. Print revenues and their total.
Write your answer, then run it.
8. Check unequal inputs
Challenge. Print whether lengths match, then list(zip(counts, bills)). Explain the missing record in a comment.
Write your answer, then run it.
9. Filter and transform
Challenge. Apply a HK$5 discount only to original prices at least 50. Print discounted prices; exclude all others.
Write your answer, then run it.
10. Explain a price policy
Challenge. Raise each price by HK$2, label updated prices Premium at 50 or above, and print both lists. Explain why updated prices must be used.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Read the first item
dishes = ["Wonton", "Char Siu", "Milk Tea"]
print(dishes[0])
print(len(dishes))Expected output
Wonton
3Position 0 selects the first item. len counts items.
2. Select a range
dishes = ["Wonton", "Char Siu", "Toast", "Milk Tea"]
print(dishes[-1])
print(dishes[1:3])Expected output
Milk Tea
['Char Siu', 'Toast']The slice excludes position 3.
3. Add and remove
dishes = ["Wonton", "Char Siu"]
dishes.append("Toast")
removed = dishes.pop(0)
print(removed)
print(dishes)Expected output
Wonton
['Char Siu', 'Toast']pop(0) removes and returns the first item.
4. Raise every price
prices = [42, 58, 28]
print([price + 3 for price in prices])Expected output
[45, 61, 31]A transformation keeps one new value per original price.
5. Keep affordable dishes
prices = [42, 58, 28, 50]
print([price for price in prices if price < 50])Expected output
[42, 28]Strictly below excludes a price equal to 50.
6. Classify prices
prices = [42, 58, 28, 50]
print(["Premium" if p >= 50 else "Regular" for p in prices])Expected output
['Regular', 'Premium', 'Regular', 'Premium']Every price receives a label.
7. Calculate paired revenues
counts = [85, 110, 140]
bills = [42, 58, 28]
revenue = [c * b for c, b in zip(counts, bills)]
print(revenue)
print(sum(revenue))Expected output
[3570, 6380, 3920]
13870Each pair refers to one dish. The total is HK$13,870.
8. Check unequal inputs
counts = [85, 110, 140]
bills = [42, 58]
print(len(counts) == len(bills))
print(list(zip(counts, bills)))
# The last count has no matching bill.Expected output
False
[(85, 42), (110, 58)]False warns of incomplete corresponding records.
9. Filter and transform
prices = [42, 58, 28, 65]
print([p - 5 for p in prices if p >= 50])Expected output
[53, 60]The filter selects eligible items before computing their new prices.
10. Explain a price policy
prices = [48, 58, 28]
updated = [p + 2 for p in prices]
labels = ["Premium" if p >= 50 else "Regular" for p in updated]
print(updated)
print(labels)
# Classify updated prices; 48 becomes 50.Expected output
[50, 60, 30]
['Premium', 'Premium', 'Regular']The price at the boundary changes category after the increase.
Modules and Imports
Explain installation versus import and recognize the common import forms.
What Is a Module?
A module is reusable Python code containing functions, variables, or other definitions. Often it is a .py file. import makes its names available in your running session.
math supplies a square-root function. The dot means “find sqrt inside math”; parentheses call it. Some modules are implemented in compiled code rather than a .py file.
Access sqrt inside math, then call it with 81.
Sources: Python modules
Module, Package, and Library
| Word | Meaning | Example |
|---|---|---|
| Module | Reusable unit of Python code | math, matplotlib.pyplot |
| Package | Organizes modules under a shared name | numpy, scipy, isom2600 |
| Library | General name for a collection of tools | The NumPy library |
An installable distribution can provide a package containing several modules. scipy.stats is SciPy’s statistics subpackage. You do not need to memorize the internal file structure.
Related modules and subpackages under a shared import name.
Sources: Python modules
Install versus Import
Install: add a package to a Python environment. Import: make its code accessible in the current running session. Installation does not automatically create the names used in your code.
An environment is Python plus its available packages. Installed packages can remain on your laptop across sessions. After restarting a runtime, rerun imports; a new temporary Colab runtime may also need installation again.
math comes with Python. Colab commonly supplies NumPy and SciPy. These websites supply their required browser packages.
No. import numpy as np creates that local name.
Sources: pip installation guide · Python modules
Install and Import: A Toolbox Metaphor
Install: place a toolbox in the environment. Import: make its tools accessible in your current session. The package remains installed when a session ends.
The cabinet represents the environment, and the desk represents the active session. A runtime restart clears the session names. The illustration is a metaphor: importing does not physically move or uninstall the package.
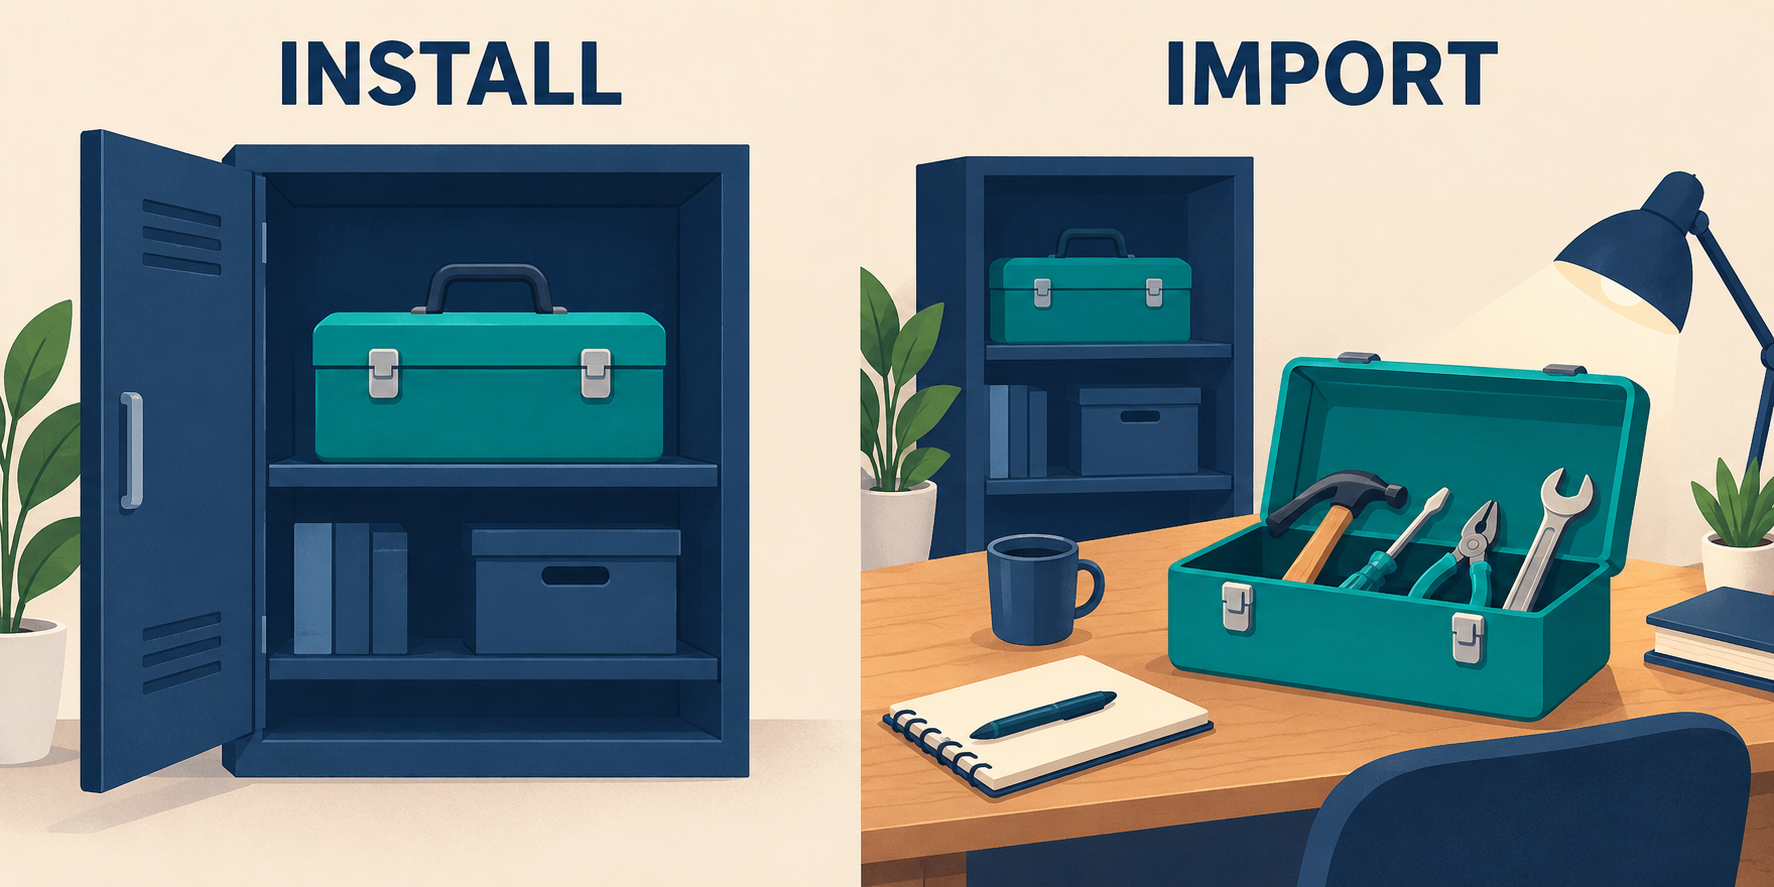
Rerun imports. Reinstall only if the new environment does not already contain the required package.
pip Commands: Where They Run
pip is Python’s package installer. These commands run in different environments; read them here as instructions, not code for a website Python box.
! and %pip are notebook features, not ordinary Python syntax. Never paste an installation command into these browser exercise editors.
Terminal:
python -m pip install isom2600Colab cell:
!pip install isom2600 --quiet! runs a shell command through the notebook. --quiet reduces messages. %pip install isom2600 is a notebook alternative targeting the current kernel.
Run a shell command through the notebook interface.
Sources: IPython pip magic
What Does pip install isom2600 Mean?
isom2600 is this course’s helper package. Installation downloads its Python code. It does not install Python or enroll you in the course.
The local package uses third-party libraries, which must also be available in its environment. The later Colab project will supply complete setup instructions. This is a reference example, not a browser exercise.
Colab reference for later work:
import isom2600
# data = isom2600.data.profit()
It supplies isom2600.data and isom2600.regression helpers. The websites use small supplied data directly; no installation is needed here.
The course helper distribution containing data and regression code; not Python.
Sources: Course package on PyPI
Import Form 1: The Module Name
import math introduces math. math.sqrt(...) identifies the module that provides the function.
A bare sqrt(64) is not defined by this import alone.
math.sqrt(value).
Import Form 2: An Alias
as gives a module a shorter local name. Its tools stay the same; the name you type changes.
np, pd, and plt are conventions, not reserved keywords. Do not overwrite an alias with a number or a list.
No. It binds a local name to the same imported module.
Import Form 3: A Selected Function
from math import sqrt introduces sqrt directly. Call it without the math. prefix.
This statement alone does not introduce the name math. Matching the call to the import prevents NameError.
sqrt, not math.
Import Form 4: A Function Alias
A selected function can also have an alias. Here, root refers to the square-root function.
The result is still 8.0. Use the chosen name consistently.
Import Form 5: A Submodule
A dotted import selects part of a package. matplotlib.pyplot contains chart functions; from scipy import stats selects statistics tools.
__name__ displays the actual module name. We teach plt.plot and stats.norm.cdf later; this cell only inspects module names.
Common Aliases in This Course
These names become available only after their corresponding imports run.
import numpy as np · import pandas as pd · import matplotlib.pyplot as plt · from scipy import stats
Wildcard Imports and Common Errors
from math import * is another form. It brings many public names into the session. Prefer explicit imports so the source of each name is clear.
Wildcard imports can hide existing names. Advanced import mechanisms are outside this chapter.
| Error | Check |
|---|---|
ModuleNotFoundError |
Package spelling and current environment |
NameError: np is not defined |
Whether import numpy as np ran |
AttributeError |
Function spelling; overwritten module name |
They make names traceable and reduce accidental name collisions.
Sources: Python modules
In-Class Practice: Match the Import
Calculate sqrt(144) in two ways: through math.sqrt and through a directly imported function. Print both results.
Checkpoint: both forms print 12.0. Explain why the calling styles differ.
Section 2 Practice — Modules and Imports
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Use a standard module
Warm-up. Import math and print sqrt(25) through the module prefix.
Write your answer, then run it.
2. Use an alias
Warm-up. Import math as m and print sqrt(36).
Write your answer, then run it.
3. Import one function
Warm-up. Import sqrt from math and print sqrt(49).
Write your answer, then run it.
4. Rename one function
Build your skills. Import sqrt as root and print sqrt(81).
Write your answer, then run it.
5. Fix the call
Build your skills. With alias m, write a matching call for sqrt(100). Explain the planned mismatch in a comment.
Write your answer, then run it.
6. Explain an installation command
Build your skills. Store !pip install isom2600 --quiet as a string and print it. Explain !, isom2600, and --quiet in comments. Do not install anything here.
Write your answer, then run it.
7. Recognize a submodule
Build your skills. Import matplotlib.pyplot as plt and SciPy stats as stats. Print their actual names using __name__.
Write your answer, then run it.
8. Compare three forms
Challenge. Calculate sqrt(121) using math.sqrt, alias m, and directly imported sqrt. Print each result on its own line.
Write your answer, then run it.
9. Inspect available names
Challenge. Use dir(m) to print whether math contains sqrt and median. Explain in a comment why a module does not supply every possible function.
Write your answer, then run it.
10. Choose setup steps
Challenge. A new Colab runtime lacks isom2600. Print its installation command and import statement as text, in order. Explain the order and why neither is needed in these website boxes.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Use a standard module
import math
print(math.sqrt(25))Expected output
5.0math requires no pip installation.
2. Use an alias
import math as m
print(m.sqrt(36))Expected output
6.0An alias changes the name, not the tools.
3. Import one function
from math import sqrt
print(sqrt(49))Expected output
7.0Call the directly imported name.
4. Rename one function
from math import sqrt as root
print(root(81))Expected output
9.0root refers to the imported function.
5. Fix the call
import math as m
print(m.sqrt(100))
# This import introduces m, not math.Expected output
10.0Match the call to the imported name.
6. Explain an installation command
command = "!pip install isom2600 --quiet"
print(command)
# ! runs a notebook shell command.
# isom2600 is the course helper package.
# --quiet reduces installation messages.Expected output
!pip install isom2600 --quietPrinting a command as text is ordinary Python. Executing !pip is notebook-specific.
7. Recognize a submodule
import matplotlib.pyplot as plt
from scipy import stats
print(plt.__name__)
print(stats.__name__)Expected output
matplotlib.pyplot
scipy.statsThe aliases refer to matplotlib.pyplot and scipy.stats.
8. Compare three forms
import math
import math as m
from math import sqrt
print(math.sqrt(121))
print(m.sqrt(121))
print(sqrt(121))Expected output
11.0
11.0
11.0All three forms access the same function.
9. Inspect available names
import math as m
print("sqrt" in dir(m))
print("median" in dir(m))
# Each module has its own tools; math has no median.Expected output
True
Falsedir lists names exposed by this module.
10. Choose setup steps
print("!pip install isom2600 --quiet")
print("import isom2600")
# Install makes code available; import creates the session name.
# Website examples use supplied packages and small data directly.Expected output
!pip install isom2600 --quiet
import isom2600The package must be available in the environment before importing it.
NumPy Arrays
Use arrays for calculations, masks, numerical summaries, and a reproducible simulation.
Create a NumPy Array
NumPy provides arrays for numerical calculations. np.array(...) converts a list into an array. Import NumPy before using np.
An ndarray stores a structured collection of values. This array is one-dimensional. Its printed form usually omits commas.
A NumPy array with those three values.
Sources: NumPy arrays
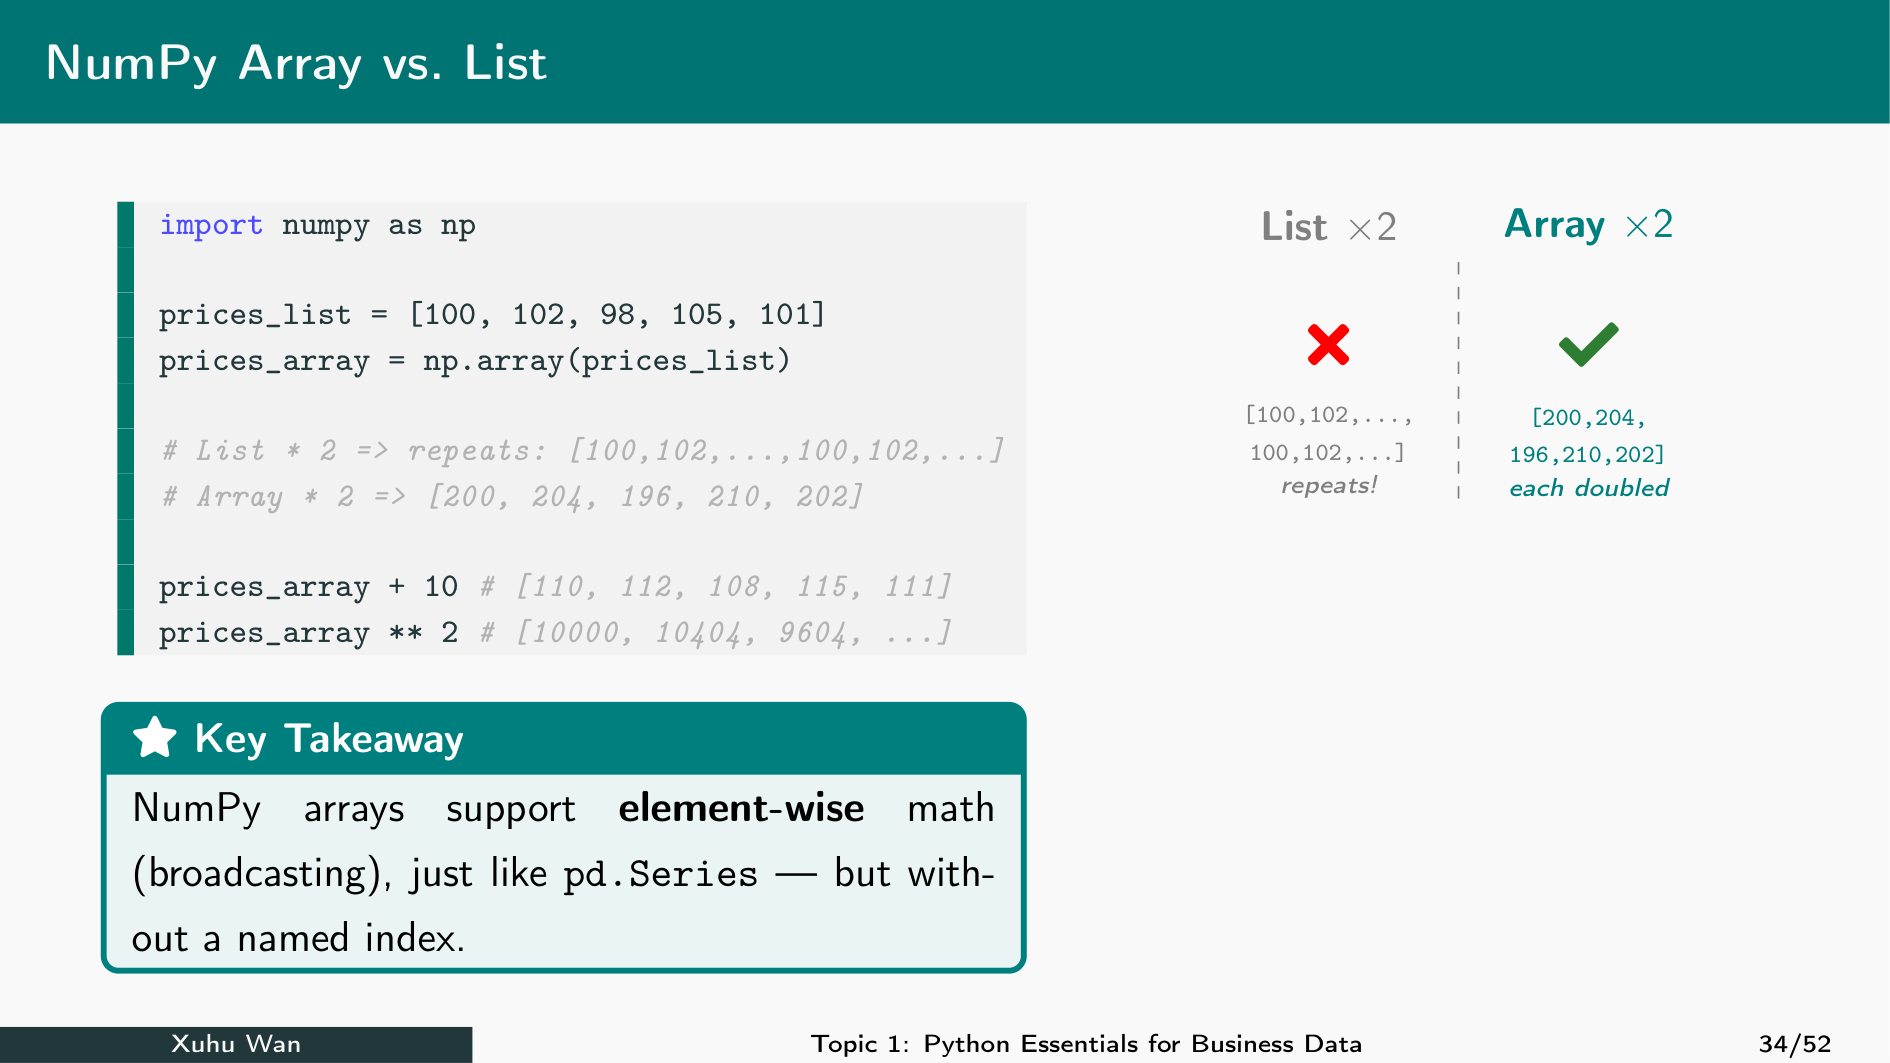
List Multiplication versus Array Multiplication
A list multiplied by 2 repeats its items. An array multiplied by 2 doubles each numerical value.
The list repeats; the array multiplies element by element.
Array Multiplication: The Picture
The list repeats the sequence; the array produces one doubled value per original item. Repetition is valid list behavior, but does not calculate doubled prices.
Array Attributes and Methods
An array is an object: it stores values and provides information and tools. The dot in prices.member accesses something belonging to prices.
| Kind | Meaning | Example |
|---|---|---|
| Attribute | Information about the object; read without () |
prices.dtype |
| Method | A function belonging to the object; call with () |
prices.sum() |
The attribute shape reports dimensions: (3,) means three items in one dimension. size reports the total number of items. dtype reports the shared stored value type; dtype=float requests decimal storage. The outer print() is a separate function used to display each result. sum() and max() calculate results without changing prices.
Predict, then try: which expressions use ()? Change prices.sum() to prices.mean() and run again. The method now calculates the average price.
Read information without parentheses, such as prices.dtype. Call a method with parentheses, such as prices.sum(). shape describes dimensions; dtype describes the element type.
Calculate Revenue Element by Element
For equally shaped arrays, corresponding positions are combined. Customer count × average bill gives one dish’s daily revenue.
Units: customers/day × HK\(/customer = HK\)/day. This matches the list-and-zip result.
A Scalar Applies to Every Element
A scalar is one value. Applying it to every array item is a simple form of broadcasting. Use it for price adjustments and percentage changes.
** raises each item to a power. Other broadcasting cases require compatible shapes; arbitrary array sizes cannot always be combined.
A 10 percent increase in each price.
Conditions Create a Boolean Mask
A comparison returns one True/False result per item. Use the mask to select matching values. Its mean is the fraction of True values.
Two of four prices pass: 0.5, or 50%.
True counts as 1 and False as 0 in numerical aggregation.
Array Summary Statistics
Use sum, mean, median, min, and max to summarize observations. Interpret the units: a mean is not a guarantee about every observation.
The mean is 101.2 customers/day. Observed counts range from 98 to 105. Level and variability answer different questions.
customers.mean() is an array method. np.median(customers) calls a function from NumPy with the array as its argument. A Pandas Series also provides a .median() method.
Standard Deviation: Choose the Denominator
Standard deviation measures spread in the original units. NumPy defaults to ddof=0: variance divides by n. The usual sample standard deviation uses ddof=1: variance divides by n−1.
Outputs: 2.315 and 2.588 customers. Match the convention to the question; pandas defaults to ddof=1.
Variance uses n−1 in its denominator; standard deviation is its square root.
Sources: NumPy std
Random Numbers: A Reproducible Simulation
A simulation creates artificial data. np.random.normal draws numbers from a normal model: loc=28 sets the mean to 28 minutes, scale=6 sets the standard deviation to 6 minutes, and size=5 asks for five numbers.
These are simulated delivery times, not observations. The optional np.random.seed(42) line makes the example repeatable; 42 is an arbitrary seed. Change size=5 to size=10 and run again to generate ten values. Section 6 explains the normal model.
In-Class Practice: A Price Increase
Increase prices by 10%. Print updated prices and select only those above HK$50.
Checkpoint: only the updated Char Siu price is above HK$50.
Section 3 Practice — NumPy Arrays
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Create an array
Warm-up. Create an array from [10, 20, 30] and print it.
Write your answer, then run it.
2. Predict multiplication
Warm-up. Print values * 2 and its array equivalent. Explain the difference in a comment.
Write your answer, then run it.
3. Read attributes
Warm-up. Create a float array from [42, 58, 28]. Print shape and dtype.
Write your answer, then run it.
4. Adjust prices
Build your skills. Add HK$2 to all prices and print the updated array.
Write your answer, then run it.
5. Compute revenues
Build your skills. Calculate corresponding count × bill revenues and their total.
Write your answer, then run it.
6. Select high prices
Build your skills. Print the mask for prices >= 50 and the selected values.
Write your answer, then run it.
7. Calculate a proportion
Build your skills. Print the fraction of observed deliveries above 40 minutes, with two decimal places.
Write your answer, then run it.
8. Choose the convention
Challenge. Print the mean and sample standard deviation to three decimals.
Write your answer, then run it.
9. Measure percentage changes
Challenge. Use slices to compute successive percentage changes for [100, 110, 99]. Print rounded percentages.
Write your answer, then run it.
10. Revenue after a discount
Challenge. Reduce bills by 10%, keep counts fixed, and calculate revenues. Print dish revenues and total to two decimals. Explain the fixed-count assumption.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Create an array
import numpy as np
print(np.array([10, 20, 30]))Expected output
[10 20 30]np.array converts a list.
2. Predict multiplication
import numpy as np
values = [10, 20, 30]
print(values * 2)
print(np.array(values) * 2)
# The list repeats; the array doubles its values.Expected output
[10, 20, 30, 10, 20, 30]
[20 40 60]The array keeps three items; the repeated list has six.
3. Read attributes
import numpy as np
prices = np.array([42, 58, 28], dtype=float)
print(prices.shape)
print(prices.dtype)Expected output
(3,)
float64(3,) means three items in one dimension.
4. Adjust prices
import numpy as np
prices = np.array([42, 58, 28])
print(prices + 2)Expected output
[44 60 30]The scalar applies to every value.
5. Compute revenues
import numpy as np
counts = np.array([85, 110, 140])
bills = np.array([42, 58, 28])
revenue = counts * bills
print(revenue)
print(revenue.sum())Expected output
[3570 6380 3920]
13870Matching positions refer to matching dishes.
6. Select high prices
import numpy as np
prices = np.array([42, 58, 28, 65])
mask = prices >= 50
print(mask)
print(prices[mask])Expected output
[False  True False  True]
[58 65]A mask has one Boolean per item.
7. Calculate a proportion
import numpy as np
times = np.array([25, 42, 30, 45, 38])
print(f"{np.mean(times > 40):.2f}")Expected output
0.40Two of five observations exceed 40: 40%.
8. Choose the convention
import numpy as np
customers = np.array([100, 102, 98, 105, 101])
print(f"{customers.mean():.3f}")
print(f"{np.std(customers, ddof=1):.3f}")Expected output
101.200
2.588ddof=1 gives the sample standard deviation.
9. Measure percentage changes
import numpy as np
prices = np.array([100, 110, 99])
changes = (prices[1:] - prices[:-1]) / prices[:-1]
print(np.round(changes * 100, 1))Expected output
[ 10. -10.]Two adjacent comparisons give two percentage changes.
10. Revenue after a discount
import numpy as np
counts = np.array([85, 110, 140])
bills = np.array([42, 58, 28], dtype=float)
revenue = counts * (bills * 0.90)
print(np.round(revenue, 2))
print(f"{revenue.sum():.2f}")
# Demand is held fixed; actual counts may change.Expected output
[3213. 5742. 3528.]
12483.00This is an arithmetic scenario, not an estimated response of demand.
Pandas Series
Identify values with labels and interpret summaries, rankings, and aligned calculations.
Create a Labelled Series
A pandas Series pairs values with an index of labels. These dish names identify which revenue belongs to which dish.
The labels provide meaning beyond numerical positions. Series is a pandas class; you create an object with pd.Series(…). The name describes the collection; it is separate from the item labels.
Labels used to identify its values.
Sources: Pandas Series
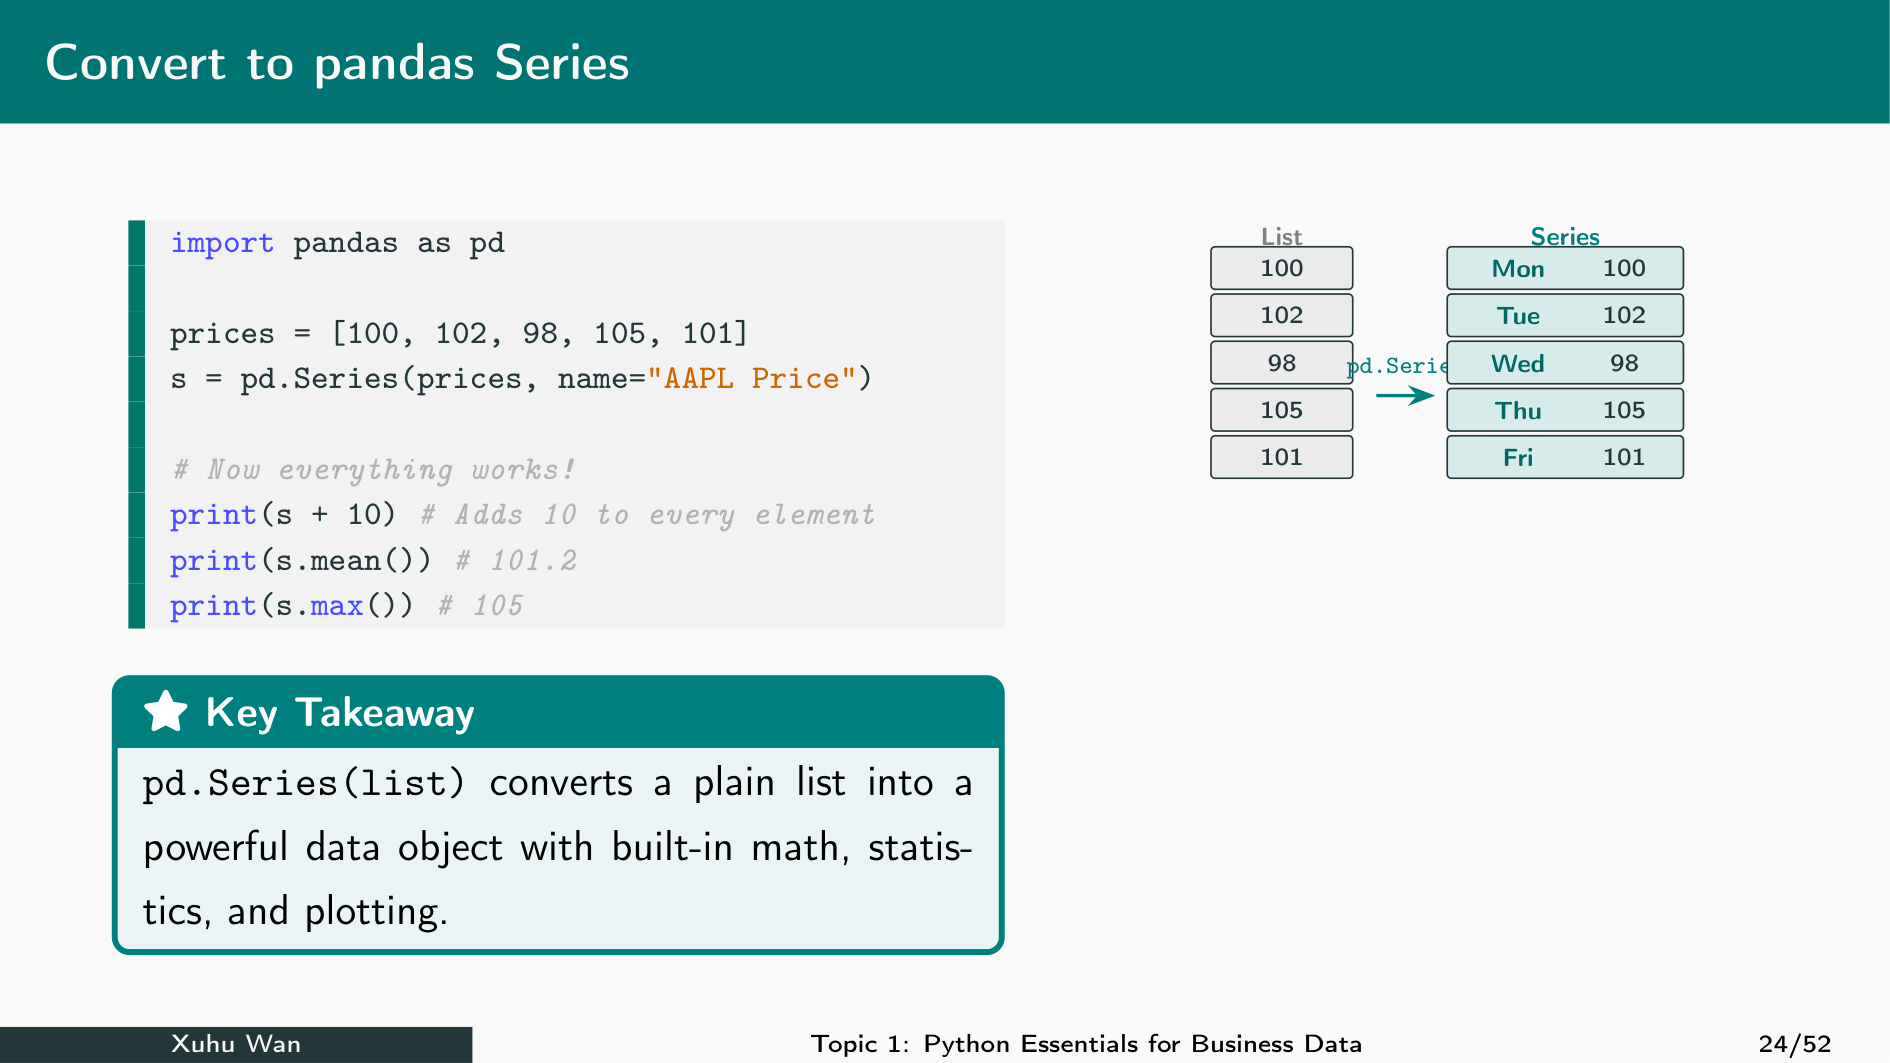
Series Labels: The Picture
The right column attaches weekday labels to the same five values. A Series can have a default numerical index or labels that you supply explicitly.
Select by Label or Position
.loc selects by an index label, such as a dish name. .iloc means integer-location selection: it selects by numerical position. Positions start at 0: the first item is at 0, the second at 1, and the third at 2.
Remember: .iloc[1] selects the second item, not the first. Here .loc["Char Siu"] and .iloc[1] select the same value using a label and a position respectively.
loc for a label; iloc for a numerical position. Positions start at 0, so iloc[0] selects the first item and iloc[1] selects the second.
Series Attributes and Methods
A Pandas Series is also an object with attributes and methods. Attributes describe it: index gives labels, name gives its name, shape gives dimensions, and dtype gives the stored value type. Read them without (). Methods do something: mean() calculates an average; median() finds the middle sorted value; head(2) returns the first two items. Call methods with (); put any arguments inside.
The dot looks up the named member on sales. The outer print() displays the result; list() converts the index labels to a familiar list. In sales.head(2), 2 is an argument controlling how many items to return. mean() and head(2) do not change the original sales Series. Integer inputs here have dtype int64; decimal inputs or dtype=float give floating-point storage.
Try: change head(2) to head(1) and run again. For selection, .loc[...] and .iloc[...] use square brackets rather than the method-call parentheses used by .mean().
name is an attribute containing information, so read it without (). mean is a method that calculates a result when called with (). A method can accept arguments, as in sales.head(2).
Mean, Median, and Spread
A mean summarizes average level; a median is the middle sorted value. Standard deviation measures spread, so two series with the same mean can behave differently.
These counts have mean 101.2, median 101.0, and sample standard deviation 2.588 customers. Large variation may matter for staffing even if the average is acceptable.
Spread around the mean, in the original units.
describe: A Summary in One Call
describe() reports count, mean, sample standard deviation, minimum, quartiles, and maximum for numerical data. The 50% row is the median.
A quartile is a percentile cutoff. 25% marks the first quartile and 75% the third. These are summaries of observed data, not a claim that its distribution is normal.
The sample median.
Sources: Pandas describe
Pandas and NumPy: Match ddof
Pandas defaults to ddof=1; NumPy defaults to ddof=0. Use matching choices when comparing answers.
Outputs: 2.588, 2.588, 2.315. Neither default is automatically appropriate for every business question.
Their defaults use different denominators. Match ddof to compare like with like.
Filter and Rank a Series
A Boolean condition selects labelled values. sort_values orders values; idxmax identifies the label of a maximum value.
Revenue ranking alone does not establish profit ranking because costs are not included. If maximum values tie, idxmax returns the first matching label.
No. Profit also depends on costs.
Count Categories
value_counts() counts how often each category occurs. Use it for survey responses, product categories, and order types.
Tea appears three times and Coffee twice. Counts differ from averages of numerical measurements.
Series Arithmetic Aligns Labels
Pandas matches index labels in Series arithmetic, even when their order differs. Check labels before combining records.
The Wonton count is paired with its labelled bill, not the first position in bills. If a label is absent on one side, the result can contain NaN.
No. It normally aligns matching index labels.
In-Class Practice: Explain a Revenue Summary
Create a labelled Series, print its mean and largest-revenue dish, then explain why revenue alone cannot determine profitability.
Checkpoint: Char Siu has the largest daily revenue, but costs are missing.
Section 4 Practice — Pandas Series
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Create labels
Warm-up. Create a Series of [100, 120, 110] labelled Mon, Tue, Wed, and print it.
Write your answer, then run it.
2. Select a label
Warm-up. Print Tue using loc and the first observation using iloc.
Write your answer, then run it.
3. Summarize totals
Warm-up. Print the sum and mean of this Series.
Write your answer, then run it.
4. Interpret describe
Build your skills. Use describe to print its count and 50% values. Explain 50% in a comment.
Write your answer, then run it.
5. Select high days
Build your skills. Print only values above 110, keeping their day labels.
Write your answer, then run it.
6. Rank days
Build your skills. Print the Series in descending order and the label of its largest value.
Write your answer, then run it.
7. Count order types
Build your skills. Print value_counts for Tea/Coffee orders, then print the Tea count alone.
Write your answer, then run it.
8. Match standard deviations
Challenge. Print pandas default std and NumPy std with a matching ddof, both to three decimals.
Write your answer, then run it.
9. Align dish labels
Challenge. Calculate count × bill with the Series below. Print the result and explain why differently ordered labels still pair correctly.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Create labels
import pandas as pd
sales = pd.Series([100, 120, 110], index=["Mon", "Tue", "Wed"])
print(sales)Expected output
Mon    100
Tue    120
Wed    110
dtype: int64The index identifies each observation.
2. Select a label
import pandas as pd
sales = pd.Series([100, 120, 110], index=["Mon", "Tue", "Wed"])
print(sales.loc["Tue"])
print(sales.iloc[0])Expected output
120
100loc["Tue"] selects the Tue label. iloc[0] selects the first observation because numerical positions start at 0.
3. Summarize totals
import pandas as pd
sales = pd.Series([100, 120, 110])
print(sales.sum())
print(sales.mean())Expected output
330
110.0330 is the total; 110 is the daily average.
4. Interpret describe
import pandas as pd
sales = pd.Series([100, 120, 110])
summary = sales.describe()
print(summary.loc["count"])
print(summary.loc["50%"])
# 50% is the median, not half the sum.Expected output
3.0
110.0The median of the sorted observations is 110.
5. Select high days
import pandas as pd
sales = pd.Series([100, 120, 110], index=["Mon", "Tue", "Wed"])
print(sales[sales > 110])Expected output
Tue    120
dtype: int64A Boolean condition preserves the selected labels.
6. Rank days
import pandas as pd
sales = pd.Series([100, 120, 110], index=["Mon", "Tue", "Wed"])
print(sales.sort_values(ascending=False))
print(sales.idxmax())Expected output
Tue    120
Wed    110
Mon    100
dtype: int64
Tueidxmax identifies the label, not the numerical maximum.
7. Count order types
import pandas as pd
orders = pd.Series(["Tea", "Coffee", "Tea", "Tea", "Coffee"])
counts = orders.value_counts()
print(counts)
print(counts.loc["Tea"])Expected output
Tea       3
Coffee    2
Name: count, dtype: int64
3The category index lets you select one frequency.
8. Match standard deviations
import numpy as np
import pandas as pd
sales = pd.Series([100, 102, 98, 105, 101])
print(f"{sales.std():.3f}")
print(f"{np.std(sales.to_numpy(), ddof=1):.3f}")Expected output
2.588
2.588Both calculations use the sample denominator.
9. Align dish labels
import pandas as pd
counts = pd.Series([85, 110], index=["Wonton", "Char Siu"])
bills = pd.Series([58, 42], index=["Char Siu", "Wonton"])
print(counts * bills)
# Pandas matches dish labels rather than array positions.Expected output
Char Siu    6380
Wonton      3570
dtype: int64Char Siu is 110×58; Wonton is 85×42.
10. Interpret revenue shares
import pandas as pd
revenue = pd.Series([3570, 6380, 3920], index=["Wonton", "Char Siu", "Milk Tea"])
shares = revenue / revenue.sum() * 100
print(shares.round(1))
# Costs are missing, so revenue share is not profit share.Expected output
Wonton      25.7
Char Siu    46.0
Milk Tea    28.3
dtype: float64Each dish is divided by total revenue. The rounded shares need not sum to exactly 100.
Matplotlib
Choose a chart, label it clearly, and explain what its evidence supports.
Choose a Chart for the Question
| Question | Chart |
|---|---|
| How does revenue change over time? | Line |
| Which dish has more revenue? | Bar |
| How are delivery times distributed? | Histogram |
| Do two numerical variables move together? | Scatter |
First identify the business question. A chart type is a choice about what comparisons should be visible. Always label variables and units.
A bar chart.
Sources: Matplotlib quick start
Matplotlib: A Figure and Its Labels
plt is the alias for matplotlib.pyplot. A figure is the picture area. plot adds a line; show displays it. Labels explain what the picture measures.
figsize specifies width and height in inches. The first plot argument gives horizontal positions; the second gives vertical values. marker=“o” marks observations. tight_layout reduces label clipping.
Line Chart: Follow Time Order
Plot days on the horizontal axis and daily revenue on the vertical axis. A connecting line helps follow chronological changes.
Friday is the largest observation. Five days do not establish a long-term trend.
Bar Chart: Compare Categories
Use separate bars for dish categories. Compare heights on the same numerical scale. Revenue does not include costs.
Bar length encodes magnitude; a truncated baseline can exaggerate differences.
Histogram: Show a Distribution
A histogram groups numerical observations into intervals called bins. Bar heights count observations within each interval. It shows spread and concentration.
Changing bins changes the displayed detail. A histogram groups a measured numerical variable; a category bar chart compares named groups.
A histogram groups numerical ranges; a bar chart compares categories.
Scatter Plot: Compare Two Variables
Each dot represents one observation. Use a scatter plot to inspect association between two numerical variables. An association alone does not prove cause and effect.
Higher spend and higher orders may share other causes, such as demand or promotions. This plot alone does not estimate the incremental effect of advertising.
No. Other explanations must be considered.
A Series Can Use Matplotlib
A Series plotting method uses its index labels. kind="bar" requests bars. You can then use plt to label and display the figure.
The explicit plt.bar and Series method answer the same category-comparison question.
In-Class Practice: Repair a Chart
Draw a bar chart comparing the three dishes. Add a meaningful title and axis labels including revenue units. Explain why a line joining dish names would be less suitable.
Checkpoint: three bars; a labelled vertical axis in HK$/day.
Section 5 Practice — Matplotlib
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Complete a title
Warm-up. Run this chart after adding the title Daily customers and a show call. Print “Line chart displayed”.
Write your answer, then run it.
2. Label units
Warm-up. Make a line chart for days [1, 2, 3] and revenue [3200, 3500, 3300]. Label axes Day and Revenue (HK$/day). Print “Units labelled”.
Write your answer, then run it.
3. Compare categories
Warm-up. Draw bars for Tea and Coffee with counts [30, 20]. Add labels and print the larger category.
Write your answer, then run it.
4. Show delivery spread
Build your skills. Draw a histogram of the supplied times using four bins. Label both axes and print the number of observations.
Write your answer, then run it.
5. Inspect an association
Build your skills. Draw a scatter plot of spend [100, 200, 300] and orders [80, 100, 110]. Add a comment explaining why the plot alone cannot prove causation. Print “Association is not causation”.
Write your answer, then run it.
6. Plot a labelled Series
Build your skills. Use a Series method to draw a bar chart of the supplied dish revenues. Keep labels horizontal and print the largest dish.
Write your answer, then run it.
7. Change histogram detail
Build your skills. Draw the delivery histogram with three bins, then six bins, in separate figures. Label both charts and print “Same data, different bins”.
Write your answer, then run it.
8. Choose a suitable chart
Challenge. For unordered dishes [Wonton, Char Siu, Milk Tea], select a chart to compare revenues [3570, 6380, 3920]. Draw it, then print your chart type and explain the choice in a comment.
Write your answer, then run it.
9. Plot a calculated quantity
Challenge. Compute daily revenues from counts [80, 90, 100] and a fixed HK$40 bill. Plot against Mon, Tue, Wed. Print the total and explain the trend limitation.
Write your answer, then run it.
10. Revenue is not profit
Challenge. Plot dish revenues [3570, 6380, 3920] as bars with a zero baseline. Print the highest-revenue dish and add two comments: one supported conclusion and one claim the data cannot support.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Complete a title
import matplotlib.pyplot as plt
plt.figure(figsize=(6, 3))
plt.plot([1, 2, 3], [100, 120, 110])
plt.title("Daily customers")
plt.xlabel("Day")
plt.ylabel("Customers")
plt.tight_layout()
plt.show()
print("Line chart displayed")Expected output
Line chart displayedThe output also contains a line chart with its title and labels.
2. Label units
import matplotlib.pyplot as plt
plt.figure(figsize=(6, 3))
plt.plot([1, 2, 3], [3200, 3500, 3300])
plt.title("Daily revenue")
plt.xlabel("Day")
plt.ylabel("Revenue (HK$/day)")
plt.tight_layout()
plt.show()
print("Units labelled")Expected output
Units labelledLabels make the values interpretable; the chart also appears.
3. Compare categories
import matplotlib.pyplot as plt
plt.figure(figsize=(6, 3))
plt.bar(["Tea", "Coffee"], [30, 20])
plt.title("Orders by drink")
plt.xlabel("Drink")
plt.ylabel("Number of orders")
plt.tight_layout()
plt.show()
print("Tea")Expected output
TeaThe chart has two bars. Tea has the larger observed count.
4. Show delivery spread
import matplotlib.pyplot as plt
times = [20, 25, 28, 30, 35, 40, 42, 50]
plt.figure(figsize=(6, 3))
plt.hist(times, bins=4, edgecolor="white")
plt.title("Delivery-time distribution")
plt.xlabel("Time (minutes)")
plt.ylabel("Number of deliveries")
plt.tight_layout()
plt.show()
print(len(times))Expected output
8The histogram contains eight observations grouped into four bins.
5. Inspect an association
import matplotlib.pyplot as plt
plt.figure(figsize=(6, 3))
plt.scatter([100, 200, 300], [80, 100, 110])
plt.title("Spend and orders")
plt.xlabel("Spend (HK$/day)")
plt.ylabel("Orders/day")
plt.tight_layout()
plt.show()
print("Association is not causation")
# Other factors may affect both variables.Expected output
Association is not causationThe plot shows three observations, not an identified causal effect.
6. Plot a labelled Series
import pandas as pd
import matplotlib.pyplot as plt
revenue = pd.Series([3570, 6380, 3920], index=["Wonton", "Char Siu", "Milk Tea"])
revenue.plot(kind="bar", figsize=(6, 3), rot=0)
plt.title("Revenue by dish")
plt.xlabel("Dish")
plt.ylabel("Revenue (HK$/day)")
plt.tight_layout()
plt.show()
print(revenue.idxmax())Expected output
Char SiuThe Series index supplies category labels. Char Siu has the highest revenue.
7. Change histogram detail
import matplotlib.pyplot as plt
times = [20, 25, 28, 30, 35, 40, 42, 50]
for bins in [3, 6]:
    plt.figure(figsize=(6, 3))
    plt.hist(times, bins=bins, edgecolor="white")
    plt.title(f"Delivery times: {bins} bins")
    plt.xlabel("Time (minutes)")
    plt.ylabel("Number of deliveries")
    plt.tight_layout()
    plt.show()
print("Same data, different bins")Expected output
Same data, different binsBoth charts use the same observations; binning changes the visual detail.
8. Choose a suitable chart
import matplotlib.pyplot as plt
plt.figure(figsize=(6, 3))
plt.bar(["Wonton", "Char Siu", "Milk Tea"], [3570, 6380, 3920])
plt.title("Revenue by dish")
plt.xlabel("Dish")
plt.ylabel("Revenue (HK$/day)")
plt.tight_layout()
plt.show()
print("Bar")
# Unordered categories are compared by bar heights.Expected output
BarConnecting categories with a line can imply an order that is not part of the question.
9. Plot a calculated quantity
import numpy as np
import matplotlib.pyplot as plt
revenue = np.array([80, 90, 100]) * 40
plt.figure(figsize=(6, 3))
plt.plot(["Mon", "Tue", "Wed"], revenue, marker="o")
plt.title("Daily revenue")
plt.xlabel("Day")
plt.ylabel("Revenue (HK$/day)")
plt.tight_layout()
plt.show()
print(revenue.sum())
# Three increasing observations do not establish a lasting trend.Expected output
10800The calculated total is HK$10,800; the chart contains only three days.
10. Revenue is not profit
import pandas as pd
import matplotlib.pyplot as plt
revenue = pd.Series([3570, 6380, 3920], index=["Wonton", "Char Siu", "Milk Tea"])
revenue.plot(kind="bar", figsize=(6, 3), rot=0)
plt.ylim(bottom=0)
plt.title("Daily dish revenue")
plt.xlabel("Dish")
plt.ylabel("Revenue (HK$/day)")
plt.tight_layout()
plt.show()
print(revenue.idxmax())
# Supported: Char Siu has the largest observed revenue.
# Unsupported: Char Siu has the largest profit; costs are absent.Expected output
Char SiuBars support a revenue comparison, not a profit or causal claim.
SciPy Probability
Distinguish CDF and PPF, calculate probabilities and cutoffs, and state model assumptions.
SciPy: A Normal Probability Model
scipy.stats supplies probability distributions. A normal distribution is a bell-shaped model described by a mean and standard deviation. Its use is an assumption about the data.
loc is the mean μ and scale is the standard deviation σ, not the variance. Times here are measured in minutes. A normal model allows negative values, so its suitability for time data must be checked.
Standard deviation 2, not variance 2.
Sources: SciPy normal distribution
CDF: A Value Gives a Probability
CDF means cumulative distribution function: P(X ≤ x). For the normal model with mean 8 and standard deviation 2, what fraction of waiting times is at most 10 minutes?
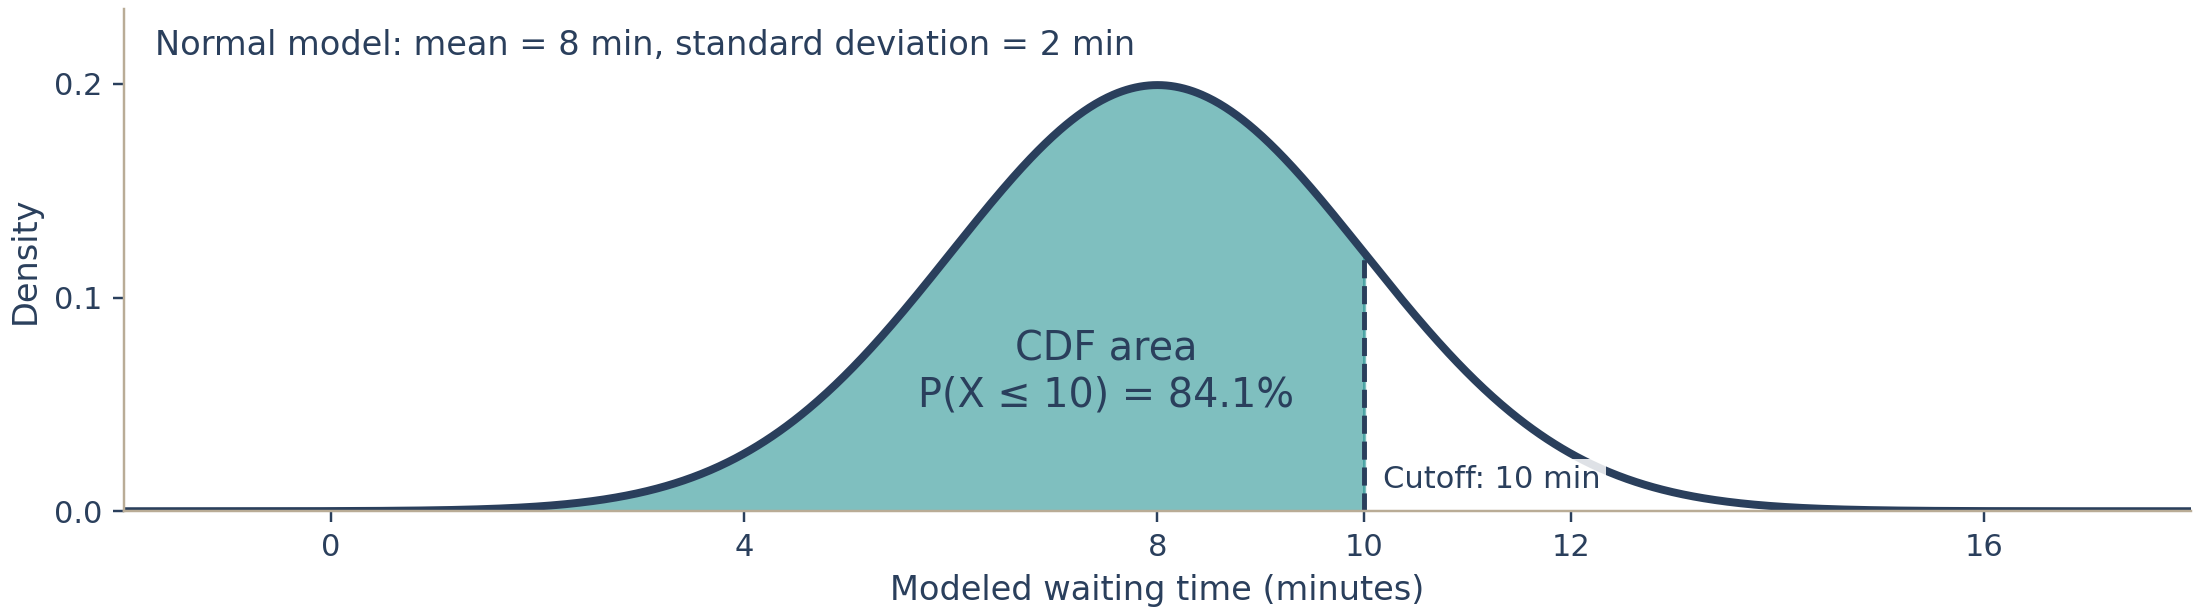
About 84.1% lie at or below 10 minutes under this model. For a continuous normal distribution, < and ≤ give the same probability.
A cutoff value goes in; a probability comes out.
Upper Tail: Exceeding a Limit
For the same normal model (mean 8, standard deviation 2), shade the area to the right of 10 minutes: P(X > 10). The total area is 1, so subtract the CDF’s left-hand area from 1.
For extreme tails, SciPy’s sf (survival function) is numerically preferable to subtraction. This chapter first uses 1 − CDF to make the probability reasoning explicit.
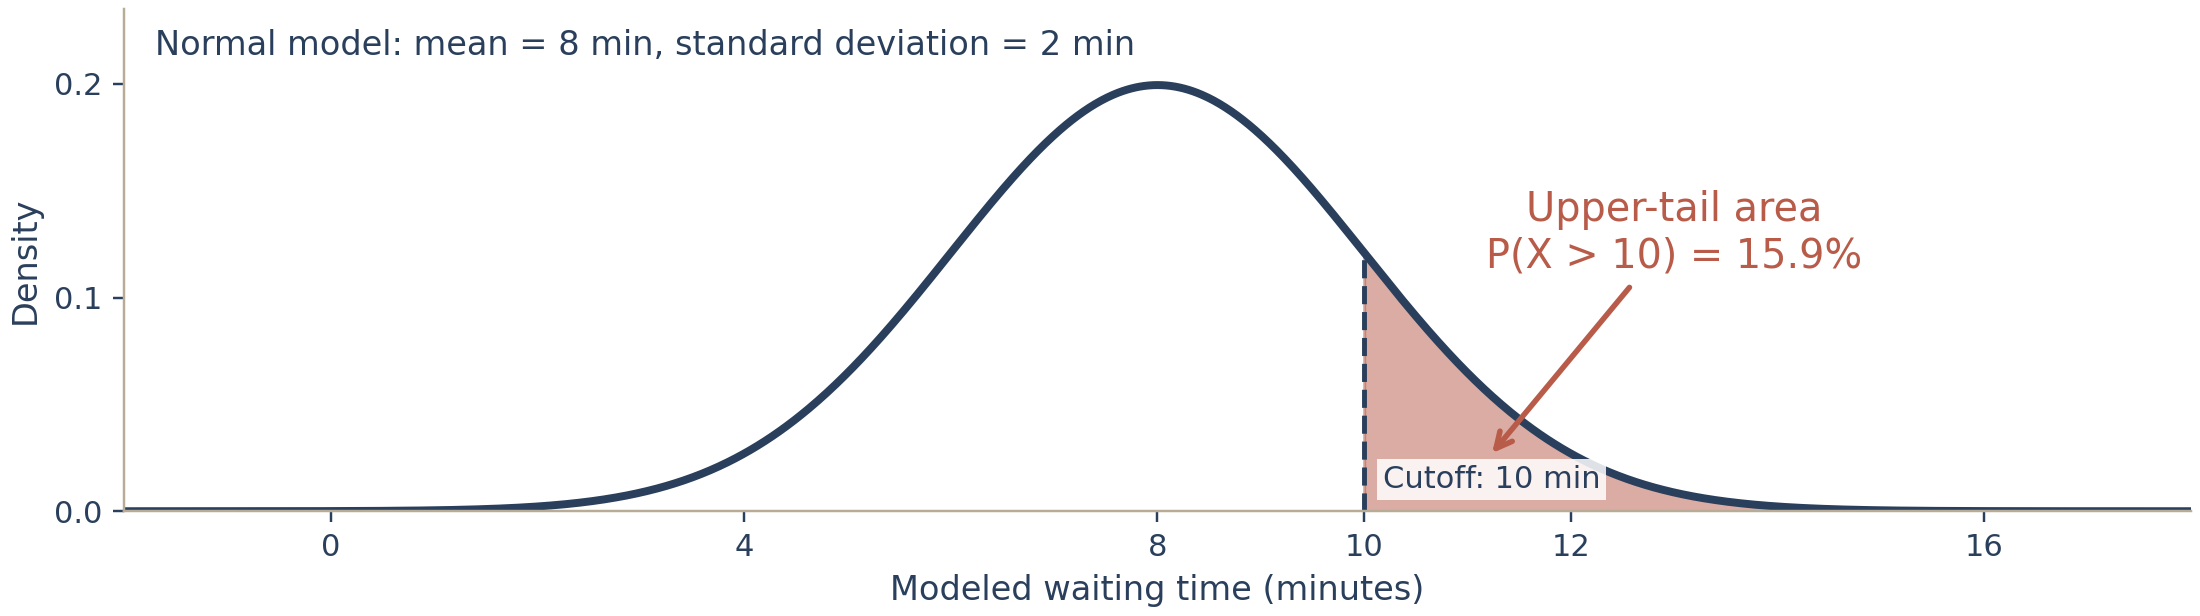
The shaded upper tail is about 15.9%. The two areas sum to 100%: 84.1% + 15.9%.
Probability Between Two Values
To find the probability between 6 and 10 minutes, subtract the cumulative probability up to 6 from the cumulative probability up to 10.
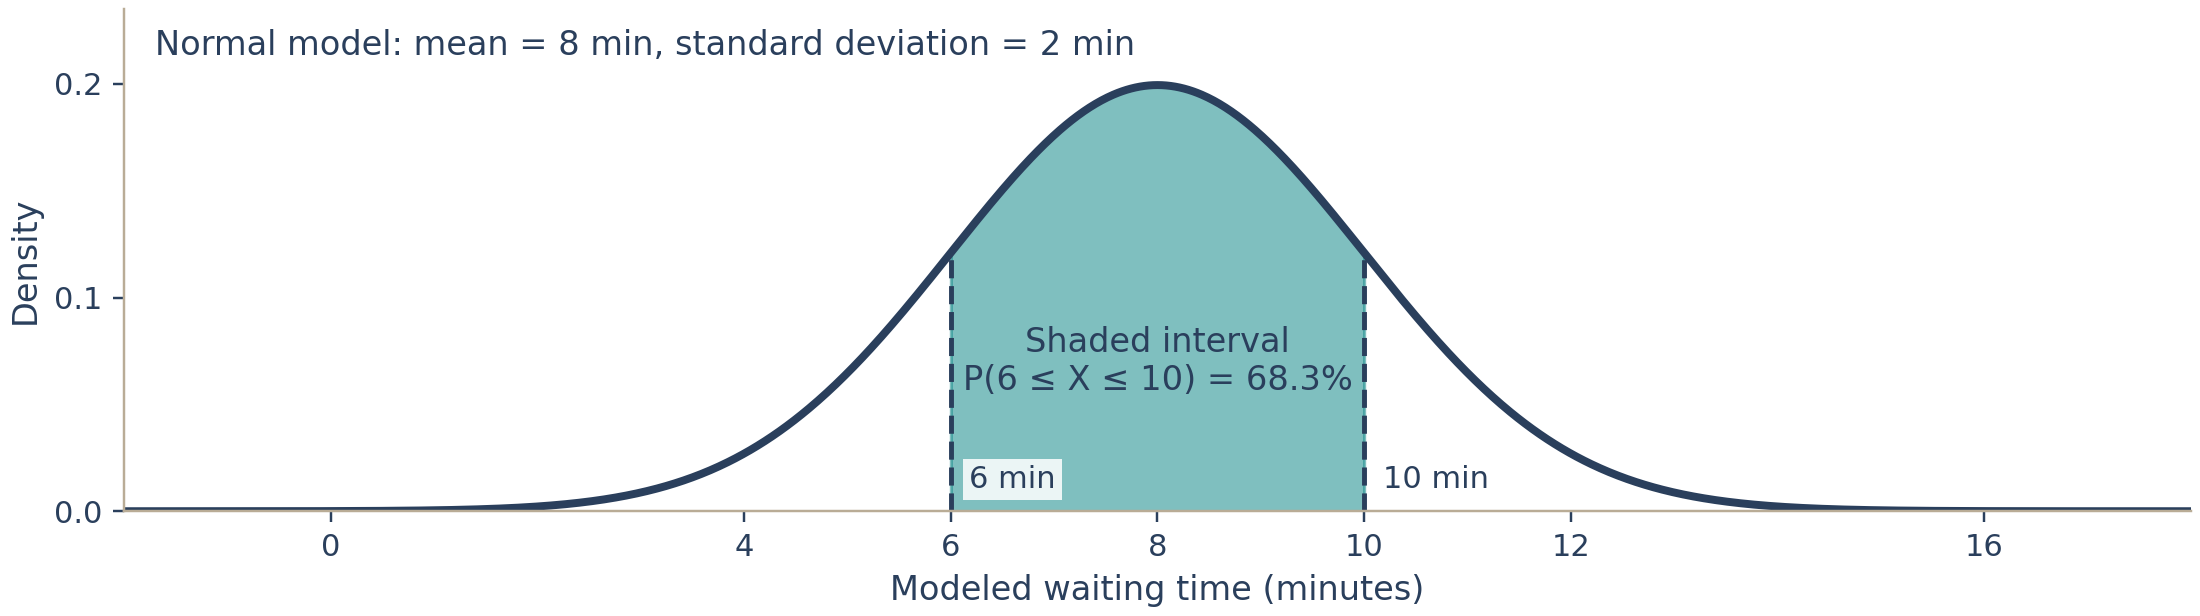
The probability is about 68.3%, matching the normal interval within one standard deviation of its mean.
CDF(b) − CDF(a), for a < b.
PPF: A Probability Gives a Value
PPF means percent point function, the inverse CDF: probability → cutoff. Start with a shaded left-tail area of 5% and find the cutoff x. Here the normal model has mean 8 and standard deviation 2.
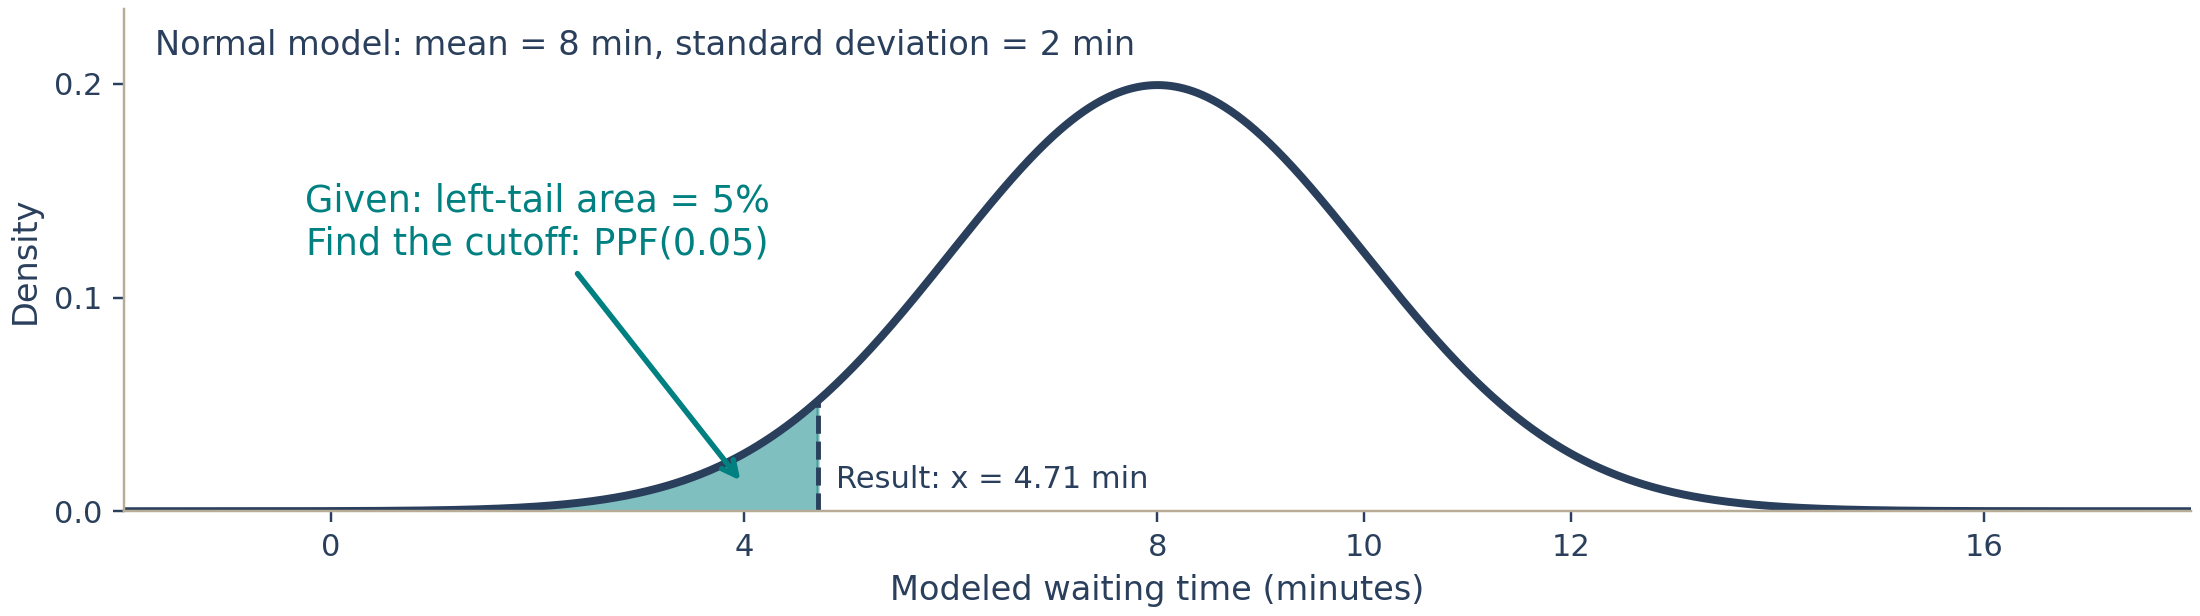
About 5% of modeled waiting times are at or below 4.71 minutes. Use 0.05, not 5.
A probability between 0 and 1 goes in; a cutoff in the original units comes out.
Delivery-Time Service Target
A service-level agreement (SLA) is a promised service standard. Assume delivery times follow a normal model with mean 28 and standard deviation 6 minutes. How often is a 40-minute limit exceeded?
The model assumes the same distribution applies to these deliveries. Traffic, extreme delays, or different routes may invalidate it. The percentile does not guarantee every order arrives in that time.
About 2.28% exceed 40 minutes; the modeled 95th percentile is 37.87 minutes. These are model estimates, not observed frequencies.
Observed Data versus a Probability Model
An observed proportion summarizes the sample. A normal CDF uses an assumed model. An observed sample quantile is not automatically the same as the model’s PPF.
The sample has only five observations. Differences need not mean a software error. The specified model and the sample are different sources of information. Series.quantile uses linear interpolation by default. No normal-model assumption is needed to summarize these observed values.
times <= 40 creates a Boolean Series. Its .mean() counts True as 1 and False as 0: four of five times pass, so the observed fraction is 0.80. times.quantile(0.95) is a Series method estimating the sample’s 95th percentile, 42.40 minutes.
No. One estimates a quantile from observations; the other calculates a quantile of a specified normal model.
Sources: Pandas Series quantile · SciPy normal distribution
PDF: Density Is Not Probability
PDF is probability density, the height of a continuous distribution’s curve. Probability is area over an interval, not the height at a point.
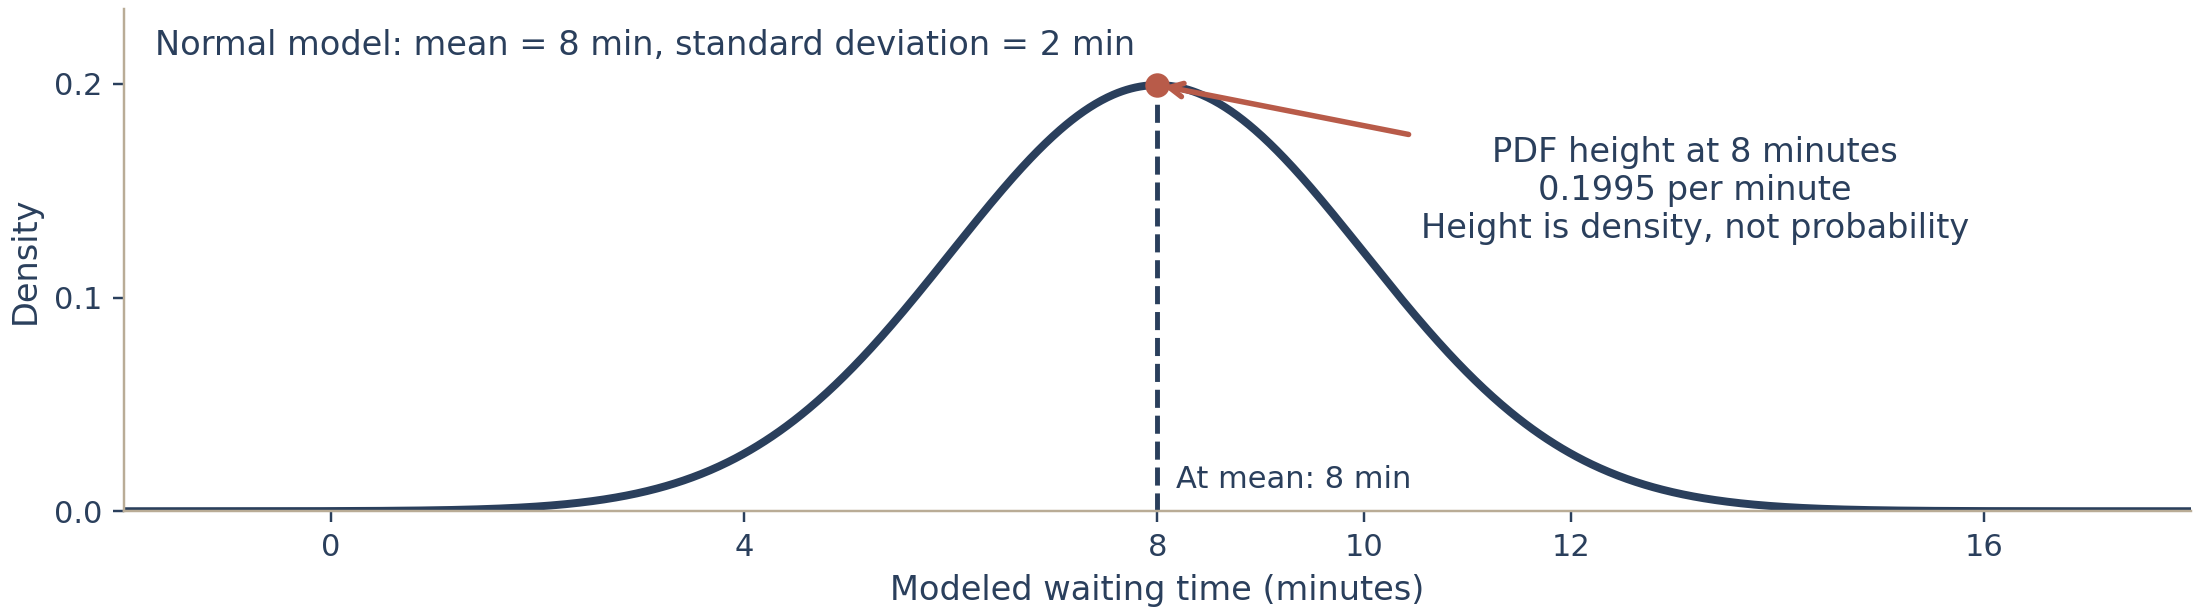
The density is about 0.1995 per minute; the cumulative probability is 0.5. They measure different things.
No. It gives density; interval probability is an area.
In-Class Practice: A 90% Delivery Target
For mean 28 and standard deviation 6 minutes, find the 90th percentile. Check it by passing that cutoff into CDF. Explain the result in one sentence.
Checkpoint: about 35.69 minutes; the checked cumulative probability is 0.90.
Section 6 Practice — SciPy Probability
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
1. Probability at the mean
Warm-up. Print the probability of a waiting time at most 8 minutes for normal mean 8, sd 2, to four decimals.
Write your answer, then run it.
2. Probability below a limit
Warm-up. Calculate P(X ≤ 10) for normal mean 8, sd 2. Print four decimals.
Write your answer, then run it.
3. Find the median cutoff
Warm-up. Calculate the 50th percentile for normal mean 8, sd 2. Print two decimals.
Write your answer, then run it.
4. Calculate the upper tail
Build your skills. Print P(X > 10) for normal mean 8, sd 2, as a percentage with one decimal.
Write your answer, then run it.
5. Calculate an interval
Build your skills. Print P(6 ≤ X ≤ 10) for normal mean 8, sd 2, as a percentage with one decimal.
Write your answer, then run it.
6. Find a service cutoff
Build your skills. For normal mean 28, sd 6, print the 95th percentile to two decimals with units. Explain its meaning in a comment.
Write your answer, then run it.
7. Check inverse functions
Build your skills. Find the 90th percentile for normal mean 28, sd 6; pass it into CDF. Print cutoff to two decimals and checked probability to four.
Write your answer, then run it.
8. Compare variability
Challenge. Compare P(X > 40) for normal models with the same mean 28 but sd 6 and sd 10. Print each percentage to two decimals and explain the result.
Write your answer, then run it.
9. Compare observations and a model
Challenge. Print the observed proportion of times above 40 and the modeled probability for mean 28, sd 6. Use four decimals and explain why they differ.
Write your answer, then run it.
10. Assess a proposed promise
Challenge. For normal mean 28, sd 6, calculate P(X ≤ 35) and the cutoff needed for 95% coverage. Print the first as a two-decimal percentage and the second to two decimals. Explain whether a 35-minute promise meets 95% under the model.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
1. Probability at the mean
from scipy import stats
print(f"{stats.norm.cdf(8, loc=8, scale=2):.4f}")Expected output
0.5000Half the symmetric normal model lies below its mean.
2. Probability below a limit
from scipy import stats
print(f"{stats.norm.cdf(10, loc=8, scale=2):.4f}")Expected output
0.8413CDF maps the cutoff to a probability.
3. Find the median cutoff
from scipy import stats
print(f"{stats.norm.ppf(0.50, loc=8, scale=2):.2f}")Expected output
8.00The normal median equals its mean.
4. Calculate the upper tail
from scipy import stats
p = 1 - stats.norm.cdf(10, loc=8, scale=2)
print(f"{p:.1%}")Expected output
15.9%Subtract cumulative probability from one.
5. Calculate an interval
from scipy import stats
p = stats.norm.cdf(10, loc=8, scale=2) - stats.norm.cdf(6, loc=8, scale=2)
print(f"{p:.1%}")Expected output
68.3%Subtract the two cumulative probabilities.
6. Find a service cutoff
from scipy import stats
cutoff = stats.norm.ppf(0.95, loc=28, scale=6)
print(f"{cutoff:.2f} minutes")
# Under the model, 95% of times are at or below this cutoff.Expected output
37.87 minutesThe probability is 0.95; the output is a value in minutes.
7. Check inverse functions
from scipy import stats
cutoff = stats.norm.ppf(0.90, loc=28, scale=6)
p = stats.norm.cdf(cutoff, loc=28, scale=6)
print(f"{cutoff:.2f}")
print(f"{p:.4f}")Expected output
35.69
0.9000CDF and PPF reverse each other for probabilities strictly between zero and one.
8. Compare variability
from scipy import stats
for sd in [6, 10]:
    p = 1 - stats.norm.cdf(40, loc=28, scale=sd)
    print(f"{p:.2%}")
# At this cutoff above the mean, more spread increases the upper-tail probability.Expected output
2.28%
11.51%The same mean does not imply the same probability of missing this service target.
9. Compare observations and a model
import pandas as pd
from scipy import stats
times = pd.Series([20, 25, 28, 32, 45])
print(f"{(times > 40).mean():.4f}")
print(f"{1 - stats.norm.cdf(40, loc=28, scale=6):.4f}")
# One describes five observed values; the other uses a specified normal model.Expected output
0.2000
0.0228Different information sources can produce different probabilities.
10. Assess a proposed promise
from scipy import stats
coverage = stats.norm.cdf(35, loc=28, scale=6)
cutoff = stats.norm.ppf(0.95, loc=28, scale=6)
print(f"{coverage:.2%}")
print(f"{cutoff:.2f} minutes")
# 35 minutes covers less than 95% under this model.Expected output
87.83%
37.87 minutesThe calculation is conditional on the normal model, not a guarantee for every delivery.
Chapter Summary
| Tool or concept | Main purpose | Read this example |
|---|---|---|
| List | Store, select, transform, filter | [p for p in prices if p >= 50] |
| Import | Make tools available under names | import numpy as np |
| NumPy array | Element-by-element calculations | counts * bills |
| Pandas Series | Label, select, summarize | revenue.loc["Wonton"] |
| Matplotlib | Communicate comparisons and patterns | plt.bar(dishes, revenue) |
| SciPy | Probabilities and model percentiles | stats.norm.cdf(...) / ppf(...) |
For revision, explain each row in your own words. Use ChatGPT to ask for an explanation or a hint; then run, verify, and explain the code yourself. For example: “Explain why list * 2 and array * 2 differ. Give me a hint before showing a solution.” The quiz mixes topics so you must identify the relevant tool.
Before trusting a result: check matching records, units, ddof, and model assumptions. Explain what the evidence supports. Revenue is not profit; association is not causation. Installation and import are different steps.
Quiz Review
Work from question 1 to 10. Edit your Python box, click Run Code, review the result, then click Submit attempt. Reference answers unlock after all ten attempts are submitted. This records completion, not correctness. Each box runs independently. Progress is saved in this browser.
Question 1
This cell imports math as m. Complete a valid call to find the square root of 144. In a comment, explain why sqrt(144) alone is not defined by this import.
Write your answer, then run it.
Question 2
From [42, 58, 28, 65], produce a new list containing a HK$5 discount only on prices at least 50. Print it and comment whether the original list changes.
Write your answer, then run it.
Question 3
Predict then print the two results below. Explain their different lengths in a comment.
Write your answer, then run it.
Question 4
Calculate counts [85, 110, 140] × bills [42, 58, 28]. Create a Series labelled Wonton, Char Siu, Milk Tea. Print the total and the label with the largest value.
Write your answer, then run it.
Question 5
Two classmates obtain different standard deviations from these same observations. Print both library defaults to three decimals, then change the NumPy call to match pandas. Explain in a comment.
Write your answer, then run it.
Question 6
Print the first value by position and the value labelled 10 from this Series. Explain why a label is not automatically its position.
Write your answer, then run it.
Question 7
Choose a chart for unordered dish revenues [3570, 6380, 3920]. Draw it with labels and units, then print the highest-revenue dish. State in a comment one reason this does not establish which dish is most profitable.
Write your answer, then run it.
Question 8
Assume normal delivery times with mean 28 and sd 6 minutes. Calculate the chance of exceeding 40 minutes. Print a two-decimal percentage and state the assumption in a comment.
Write your answer, then run it.
Question 9
For normal mean 28 and sd 6, find the cutoff containing 95% of times below it, then verify its cumulative probability. Print cutoff to two decimals with units, then probability to four decimals.
Write your answer, then run it.
Question 10
For observed times [20, 25, 28, 32, 45], print (1) the proportion above 40, (2) the sample 95th percentile, and (3) the normal-model 95th percentile for mean 28 and sd 6. Use two decimals. Explain why the last two need not match and why neither guarantees every delivery.
Write your answer, then run it.
Reference answers are locked until all 10 attempts are submitted.
Question 1
import math as m
print(m.sqrt(144))
# The statement introduces m; it does not introduce sqrt directly.Expected output
12.0Calls must match the imported name.
Question 2
prices = [42, 58, 28, 65]
result = [p - 5 for p in prices if p >= 50]
print(result)
# The comprehension creates a new list; prices is unchanged.Expected output
[53, 60]Filtering and transformation can be combined.
Question 3
import numpy as np
values = [10, 20]
print(values * 2)
print(np.array(values) * 2)
# The list repeats its two items; the array doubles two values.Expected output
[10, 20, 10, 20]
[20 40]The operator’s behavior depends on the object type.
Question 4
import numpy as np
import pandas as pd
counts = np.array([85, 110, 140])
bills = np.array([42, 58, 28])
revenue = pd.Series(counts * bills, index=["Wonton", "Char Siu", "Milk Tea"])
print(revenue.sum())
print(revenue.idxmax())Expected output
13870
Char SiuArrays calculate values; Series labels identify which dish has the maximum.
Question 5
import numpy as np
import pandas as pd
values = [100, 102, 98, 105, 101]
print(f"{pd.Series(values).std():.3f}")
print(f"{np.std(values):.3f}")
print(f"{np.std(values, ddof=1):.3f}")
# pandas defaults to ddof=1; NumPy defaults to ddof=0.Expected output
2.588
2.315
2.588Matching the statistical convention resolves the difference.
Question 6
import pandas as pd
s = pd.Series([100, 200, 300], index=[30, 10, 20])
print(s.iloc[0])
print(s.loc[10])
# The first position has label 30, while label 10 is second.Expected output
100
200Use explicit positional and label-based selectors.
Question 7
import pandas as pd
import matplotlib.pyplot as plt
revenue = pd.Series([3570, 6380, 3920], index=["Wonton", "Char Siu", "Milk Tea"])
revenue.plot(kind="bar", figsize=(6, 3), rot=0)
plt.title("Revenue by dish")
plt.xlabel("Dish")
plt.ylabel("Revenue (HK$/day)")
plt.tight_layout()
plt.show()
print(revenue.idxmax())
# Costs are absent; revenue is not profit.Expected output
Char SiuThe chart compares categories. It cannot rank profitability without costs.
Question 8
from scipy import stats
p = 1 - stats.norm.cdf(40, loc=28, scale=6)
print(f"{p:.2%}")
# The normal distribution and these parameters are assumed to apply.Expected output
2.28%The complement of CDF gives the upper-tail probability.
Question 9
from scipy import stats
cutoff = stats.norm.ppf(0.95, loc=28, scale=6)
print(f"{cutoff:.2f} minutes")
print(f"{stats.norm.cdf(cutoff, loc=28, scale=6):.4f}")Expected output
37.87 minutes
0.9500A probability-to-cutoff calculation is checked by reversing it.
Question 10
import pandas as pd
from scipy import stats
times = pd.Series([20, 25, 28, 32, 45])
print(f"{(times > 40).mean():.2f}")
print(f"{times.quantile(0.95):.2f}")
print(f"{stats.norm.ppf(0.95, loc=28, scale=6):.2f}")
# The sample and the assumed model are different sources of information.
# A 95th percentile leaves a tail; it is not a guarantee for every order.Expected output
0.20
42.40
37.87Observed proportions, sample quantiles, and model percentiles have different interpretations.